A paper I enjoyed reading recently: Inverse problems in spaces of measures, Bredies, Pikkarainen. Introduces a Frank Wolfe algorithm with non convex improvement to solve infinite dimensional optimization over measures. A must read. https://t.co/SgDssJFb1N
A paper I enjoyed reading recently: Breaking the Curse of Dimensionality with Convex Neural Networks, @BachFrancis (fig by @LenaicCsl ). Frames training of sparse 1 hidden layer MLP as optimization over measures, very inspiring. https://t.co/dnPZJvuhgF
New paper by my student @WehenkelAntoine: Unconstrained Monotonic Neural Networks! https://t.co/3bWLj8ck0l In this work, we show how to make use of free-form neural networks to model arbitrary monotonic functions and derive a new autoregressive flow.
@fhuszar This @SimonsInstitute 'Boot Camp' has some really insightful talks/surveys about generalization, including the effect of batch_size on generalization https://t.co/k8LRfq8PfK
Second post in the Mutual Information series: this time I address the notorious Formal Limitations paper and show how it manifests itself in different bounds.
https://t.co/KyR0Emhf3X
Recently, I've been thinking about the Mutual Information and ways to estimate it. I'd like to share some of my thoughts and start with suggesting some novel / overlooked ways to estimate the MI.
https://t.co/7d62MT5GQB
MLPerf 0.6 is out! Training speed on a single DGX-2 improved up to 1.8X over 7 months ago, and scaling efficiency to many nodes is markedly better.
The V100 GPU, 2 years after intro, is still the fastest and most general processor for deep learning.
https://t.co/mEDGgBGiIJ
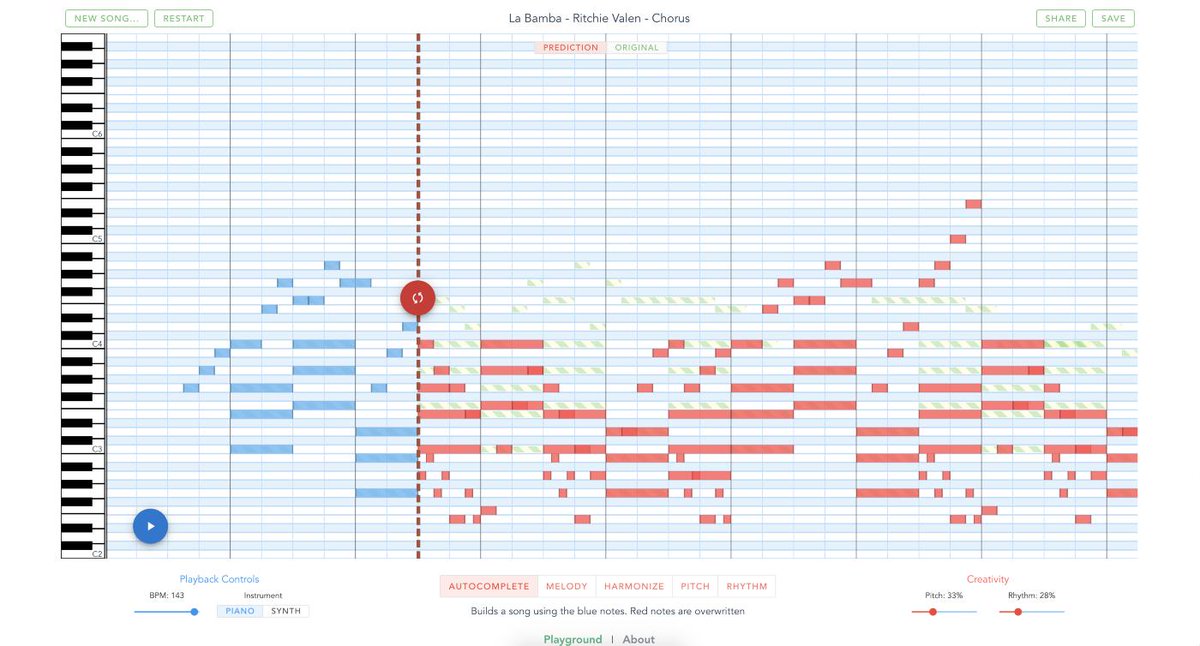
An amazing new project from @bearpelican was just released: https://t.co/DBov6sZTVS . A beautiful design; you can auto-generate a melody from chords, chords from a melody, and more.
It's technically brilliant, combining BERT, seq2seq, and Transformer XL
https://t.co/jF3mO5aXiu
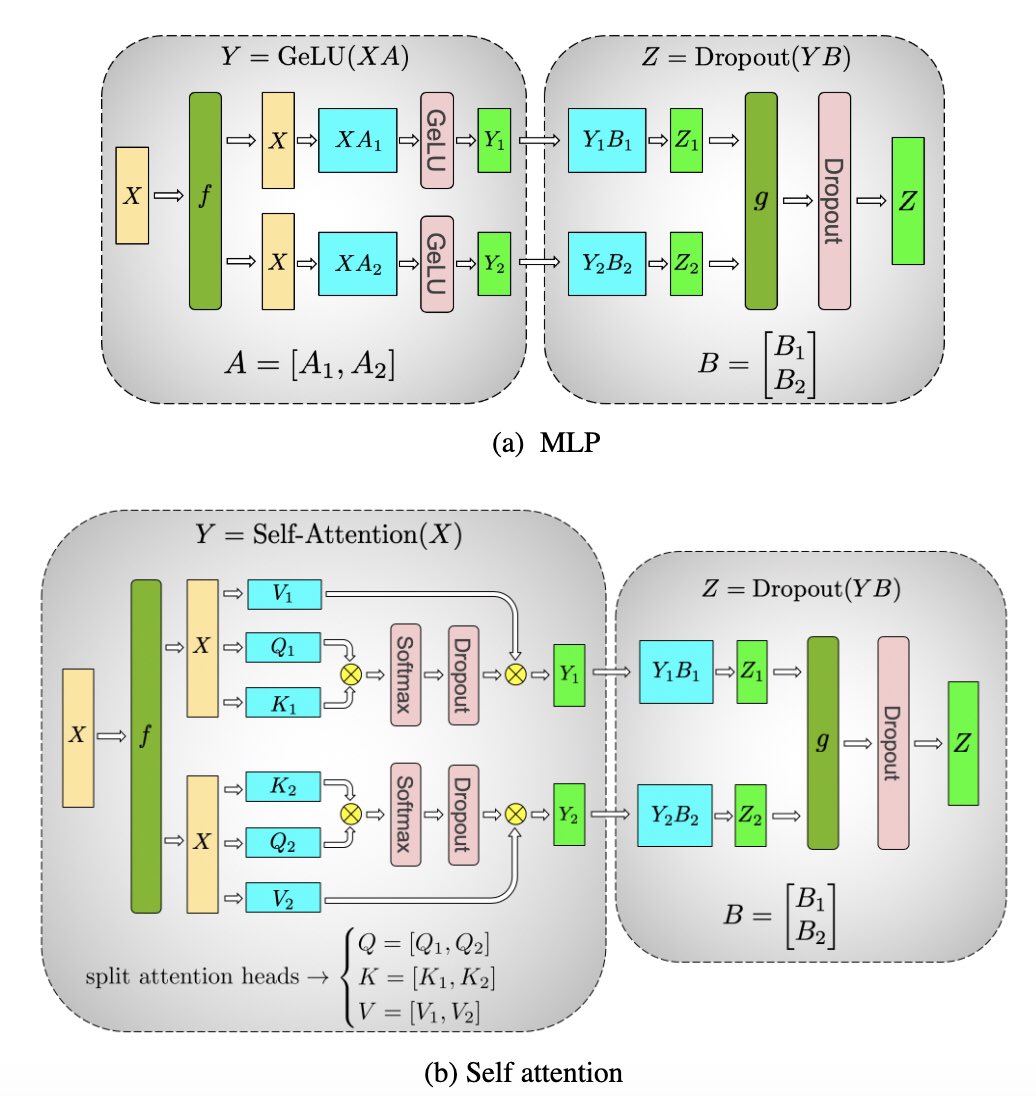
Here’s how we trained an 8.3B parameter GPT-2. We alternate row- and column- partitioning in the Transformer in order to remove synchronization and use hybrid model/data parallelism. 15 PFlops sustained on 512 GPUs. Details and code: https://t.co/7eXA6r15yX
We are excited to release Behaviour Suite for Reinforcement Learning, or ‘bsuite’ – a collection of carefully-designed experiments that investigate core capabilities of RL agents
GitHub: https://t.co/kGkRtFhezR
Paper: https://t.co/UJcALddJpc
@fhuszar a good ol' read in that regard from @jessejdavis1
https://t.co/TzkJOx1J20
they are very correlated but PR-AuC provides more information when the dataset is very unbalanced
Oldies but Goldies: D. Donoho, Compressed sensing, 2004. Introduced (jointly with Candes, Romberg, Tao) the compressed sensing idea. https://t.co/Vz1PCMEifk
Gradient descent on particles’ positions (Langrangian) is equivalent to an advection linear PDE on the density of particles (Eulerian). https://t.co/lHYMjNfyZt