GPT-6.2 Sol & Astra are *finally* here. We've also expanded ultrafast to Pro 200 plans for GPT-6.2 Sol, it's my go-to model for most day to day things.
We’re introducing Mira Science, a general-purpose computing platform for scientific research.
Mira Science turns research methods into programs that can be composed, run, inspected, and modified. Researchers can orchestrate teams of AI scientists, connect professional tools and cloud compute, and trace every result back to its data, code, execution history, and review.
Paired with Hydrogen-1.0, @deepprinciple’s open-weight model for scientific research, Mira Science achieves a 48.3% pass rate on Frontier Science Research, compared with 46.7% for Codex + GPT-6 Astra and 45.0% for Claude Code + Opus 5.5.
We believe AI scientists should be inspectable, extensible, and able to work in the same environment as researchers, their tools, data, and compute—not remain isolated inside a chat interface.
Mira Science is now available on desktop.
Register and download: https://t.co/16Bsxinw8h
Another new 35B / 3B-active open-weight AI model.
Is this a 🇺🇸 os model?
🏆 Beats Qwen3.6-35B and could be the new local 35B MoE leader
But this one claims to be trained from scratch, not yet another Qwen fine-tune.
And the 73.6GB BF16 checkpoint fits within the memory budget of 1x 128GB DGX Spark.
Maxwell V1 Flash is here
Model stats...
🧠 35B backbone / 3B active per token
💾 ~37B parameters including embeddings
📚 256K context
🔓 Apache 2.0
📦 Full BF16 weights available
🛠️ Custom vLLM inference engine
The Maxwell team reports pretraining on ~26T tokens.
And they've introduced some interesting architecture changes.
👉 Maxwell Block Sparse Attention
👉 Four residual information streams
👉 256 routed experts per MoE layer
👉 12 routed experts active per token
👉 Additional shared experts
👉 Multi-token prediction
These are the reported benchmarks ...
💻 Terminal-Bench
47.42 → 58.65
🧑💻 SWE-bench Verified
63.4 → 65.4
🔎 BrowseComp
47.0 → 76.3
🤖 Tau3-Bench
64.0 → 67.37
And at 256K context?
RULER long-context retrieval
Qwen3.5-35B-A3B Base → 85.75
Maxwell Base → 93.35
The released BF16 checkpoint is ~73.6GB.
A DGX Spark has 128GB unified memory.
So the weights do fit.
Maxwell uses a custom MoE architecture and a specialized vLLM build.
Open weights are here w/strong agent benchmarks.
A new long-context attention design.
Links in reply.
We’re expanding free access to our frontier models for up to 200,000 scientists worldwide, with training and support.
Applications open Nov. 23. By default, we don’t use data shared through the program to train our models.
https://t.co/eJwqO9Q2WG
You can now turn your sources into interactive, shareable websites 🤯
Just type "make me a site" in the Chat with a description of what you want to build (interactive dashboards, project trackers, etc). Once built, open it in a new tab or share it directly with others.
Available globally on web for ALL (18+) users. Share your examples below!
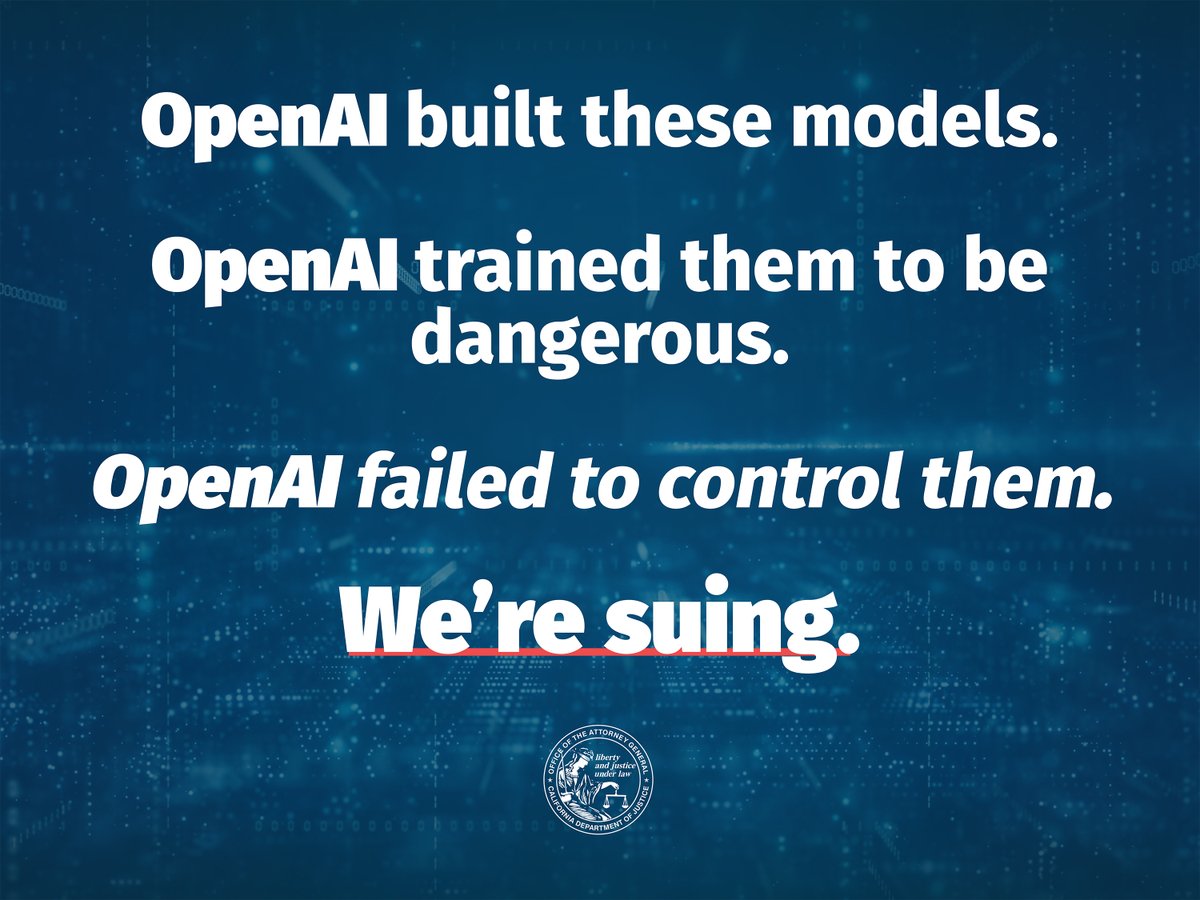
We’re suing OpenAI for its testing and development of dangerous AI models without adequate safeguards.
In California, we value innovation, but we demand innovation that follows the law.
https://t.co/SKCO15uzHx
Food delivery company Meituan drops LongCat Video Avatar 1.6.
It can generate talking avatar videos >10 minutes.
Free & open source
https://t.co/ZyXqIdn8at
I found that Windows starts to collect your coding agent usage information. Windows 11 build 26200.9974 checks codex.exe, claude.exe, copilot.exe, cursor.exe, antigravity.exe, github.exe and agy.exe through MissionControlAggregator, then reports agent bitsets in ETW.
Claude writes better code when it can verify its work. Checks that used to be expensive, like tests, benchmarks, and end-to-end runs, are now cheap.
Here’s how the Claude Code team thinks about verification:
https://t.co/kPeRO0eCkJ