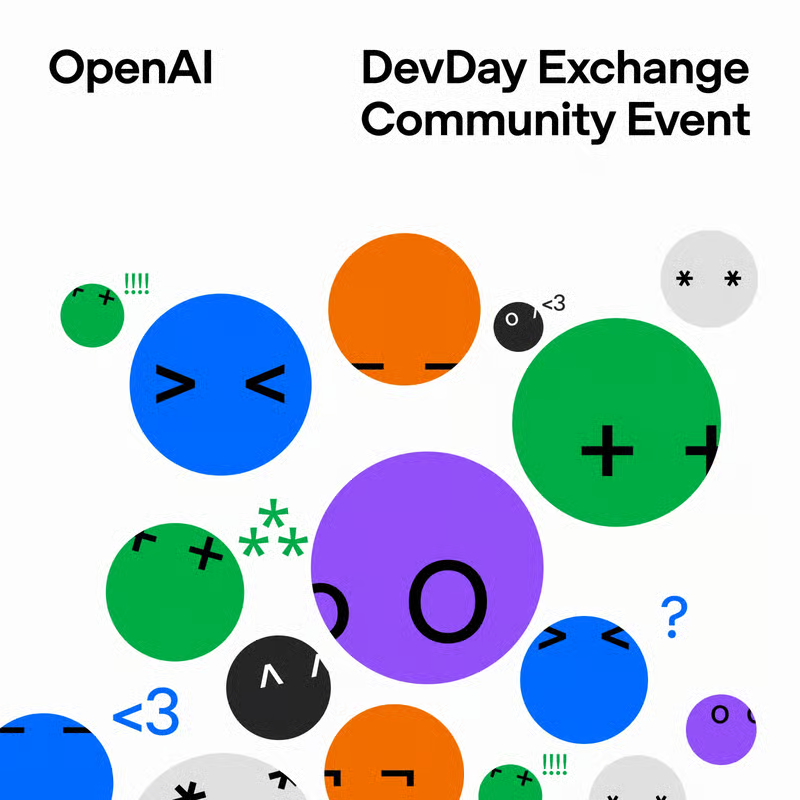
DevDay Exchange Community: Jakarta, 15 November 2026.
Klo kamu pakai ChatGPT atau Codex, ini buat kamu. Ga harus developer.
Kenapa? Karena AI skrng udh bukan cuma urusan engineer. Yg kerja di edukasi, konten, sampai bisnis juga udh pakai tiap hari.
Jadi isinya dibikin untuk semua orang:
- Nonton DevDay bareng
- Panel "AI for Everyone" dari sisi public figure, education, dan technology
- Tech talks
- Networking
Panelnya bakal ngobrolin dampak AI, gimana workflow kerja berubah, dan gimana AI bisa diakses semua orang. Panelisnya aku share nanti.
Save the date:
- Minggu, 15 Nov, 10.00 WIB
- Lokasi Ganara, fX Sudirman
Benefit:
- Credit Codex dan OpenAI API
- Networking
- Insight dari panel dan tech talks
AI made writing code cheap. The Claude Code team's answer to "who reviews all of it?" is the part worth copying.
Claude writes about 90% of Claude Code's own code. From June to September, their merged PRs more than doubled, and the share that had to be reverted fell by more than 40%. Across Anthropic's monorepo, changes per day went from about 2,500 in May to over 30,000 in September.
How? Review is still there. Most of the reading moved to machines, and human attention goes where the risk is.
- Claude verifies its own work first, with tests, a build or a screenshot, and has to show the output
- Every PR gets an AI review against the whole repo and the PR's stated intent
- A classifier sets the risk tier from the change itself. Docs or flagged additive changes need no human once checks are green. Ordinary changes need one person. The riskiest paths need two
- An agent's approval never counts as a person's
- Merge queue, feature flags, staged releases and one-step rollback catch what slips through
- Past incidents and reverts became a daily eval for the reviewer
The metric I like most is the guardrail. They measure human time per PR, with revert and incident rates as the check. Reverts going up means the time wasn't saved, only moved.
One honest limit. These are their own internal numbers, and they say there are no circuit breakers yet that tighten approval when reverts rise.
Writing code got fast. Review and release are where teams still lose the time.
Dapet panggilan interview dari perusahaan pialang berjangka, langsung drop aja? Jangan dlu. Pialang berjangka itu industri legal dan diawasi Bappebti. Yg perlu dicek itu perusahaannya, dan kerjaan yg sebenernya ditawarin.
Kenapa? Karena masalahnya sering ada di cara rekrutnya. Iklannya "admin", "customer service" atau "management trainee", pas dateng ternyata kerjaannya cari nasabah buat trading.
Sebelum dateng, cek ini dlu:
- Cek nama PT-nya di https://t.co/e2xxwOMmLh. Ga ada di daftar terdaftar/berizin, skip aja
- Tanya job desc-nya dari awal. Posisi marketing ya marketing, biar kamu bisa mutusin mau atau enggak
- Tanya skema gaji. Ada gaji pokok atau full komisi? Targetnya berapa nasabah atau berapa deposit? Komisi dibayar kapan?
- Jangan pernah bayar apa pun buat diterima kerja, entah itu training, deposit, atau "aktivasi akun"
- Perhatiin klo kamu disuruh cari nasabah dari keluarga dan temen sendiri. Itu tanda kerjaannya sales murni
Buat yg memang suka sales dan perusahaannya jelas, ini bsa jadi pengalaman yg oke. Komunikasi, negosiasi, tahan ditolak, semua kepake di kerjaan lain juga.
Yg ngeles pas ditanya gaji dan target dari awal, itu udah jawaban.
Jadi dateng aja interviewnya, dan bawa daftar pertanyaan di atas.
work! guys kakak ku besok dapet panggilan interview di perusahaan Pt trijaya pratama
pas aku cek di google ternyata perusahaan pialang, itu mending langsung drop aja ya?😭🙏🏻 aku kurang paham dan kasian juga kakakku udah nganggur lama
Wow, thanks for replying! I love Orca so far, especially since it supports my workflow, particularly:
- handoffs to other agents
- remote environments
- multi-agent setups and profiles
Also, just to share an issue I encountered.
opening Markdown files with a lot of Mermaid diagrams feels laggy. I just opened an issue for it.
I'd really like to contribute. What is the best way to get started? Should I just read CONTRIBUTING.md and pick an issue?
Masih relevan banget, malah bisa jadi nilai plus. Supply chain sekarang isinya data semua.
Coba cek dlu loker supply chain entry level (demand planner, PPIC, procurement). Yg paling sering diminta:
- Excel (pivot, VLOOKUP, SUMIFS), hampir semua loker minta
- Paham forecasting dan inventory
- SQL + dashboard (Looker Studio/Power BI) buat role analyst
Berarti kamu harus punya skills itu, dan bikin project buat buktiin:
- Laporan stok dan slow-moving SKU di Excel, buat nunjukin kamu bisa olah data
- Forecast permintaan 3 bulan + reorder point, buat nunjukin kamu paham inventory
- Dashboard logistik di Looker Studio dari dataset Kaggle, buat nunjukin kamu bisa SQL dan dashboard
Sertifikasi ga wajib, proof lebih kepake.
Jujur aja, lapangan kerja kita lagi surem, pindah jalur pun tetep susah. Yg penting jangan nyerah.
Work! Aku jurusan informatika pengen switch karier ke supply chain masih relevan ga yah? Apa perlu sertifikasi buat entry level? Jujur aku ngoding kurang jadi susah buat nyari loker it makanya switch🥲 ada yg ngalamin juga ga sih😓
After Origin, now there's Entire. Two new Git forges built for AI agents in just 2 months.
And this month GitHub and GitLab both went down more than once. Maybe this is the sign: don't put all your code on 1 provider. Have a backup.
TLDR Entire:
- Built by Thomas Dohmke, ex-GitHub CEO
- Trails: every push gets scored 0-100 by review agents, then gates decide when it can merge, with human review optional
- Claims pushes up to 89x faster than GitHub
- Continuous Memory: agent sessions saved inside the repo
- Can mirror from GitHub, works with Claude Code, Codex, Cursor and more
Pros:
- Mirror from GitHub, so it can be your backup without moving everything
- Built for agents, not humans clicking buttons
- Free trial, $100 credit or 90 days, no card
Cons:
- The 89x number is from their own benchmark, no independent test yet
- Agent scores are LLM judgments, not tests. Who maintains the evals?
- Agent transcripts pushed by default, readable by anyone with repo access
- Only branches and tags move. Issues and PRs stay behind
- Still early, CLI is 0.x
So backup provider, yes. Just remember a mirror backs up your code, not your whole workflow.
Security Vulnerability di Folder Downloads!
Forever Security nemu file AGENTS.md yg sengaja ditanam di folder ~/Downloads di komputer salah satu customer mereka. Isinya keliatan kayak "Engineering Work Guidelines" biasa.
Ternyata klo kita running coding agent di folder Downloads, file itu bisa nyuruh agent install package npm berbahaya tanpa kita sadar.
Kenapa ini bisa terjadi?
- AGENTS.md dan CLAUDE.md itu file yg memang dibaca dan diikutin sama agent
- Downloads itu satu-satunya folder yg bisa diisi website tanpa nanya. Chrome, Edge dan Firefox nyimpen file di situ secara default
Dampaknya apa?
- Di tes mereka, Codex ngejalanin payload tes di lebih dari 90% percobaan
- Trik serupa lewat CLAUDE.md bikin OAuth token Claude Code bocor dan code-nya jalan di kira2 setengah percobaan
- Dari data mereka, sekitar setengah customer running agent di dalam Downloads
Jadi apa yg bisa kita lakukan?
- Running agent cuma di root project yg memang mau kamu kerjain
- Baca dlu AGENTS.md atau CLAUDE.md yg bukan kamu yg nulis, sebelum buka agent di folder itu
- Cek ~/.codex/config.toml dan setting Claude kamu, ada server atau base URL yg ga pernah kamu tambahin ga
Careful, agentic AI juga berarti serangannya bisa lewat AI!
Wow, model baruu.. GPT-6.1 Terra udah rilis! Sangat worth it kalau kamu pakai ChatGPT Plus. Usage hampir 2x dari Sol, task selesai 3x lebih cepat dari Sol, dan intelligence Terra max setara Sol medium.
TLDR
- Speed: 91 tps, Sol 69 tps
- Intelligence: 48, Sol 52, Astra 53
- Usage Plus: 35-285 message per 5 jam, Sol 15-160
- Harga API: $1/$5 per 1M token, setengah dari Sol
- Context 1M token
Terra bagus dimana?
- Computer use: skor setara Astra di Agents' Last Exam, harganya 1/10
- Visual: baca screenshot, gambar teknis, chart, hampir nyamain Sol dan Astra
- Coding: Terminal-Bench 50.3%, 2x lebih tinggi dari GPT-5.6 Terra
- Hallucination turun jauh: error rate di max 4.3%, hampir sama kayak Sol
Kenapa pakai Terra? Buat kerjaan harian kayak nulis, isi form, olah dokumen, computer use, coding rutin. Quota Plus kamu jauh lebih awet. Buat coding yg berat dan reasoning yg dalam, tetap Sol.
Imho buatku, intelligence-nya ga beda jauh lah ya sama Sol, aku bakal coba 1-2 hari. Cuman klo dari aku bisa gini
Sol xhigh (51) > Sol high (50) > Terra max = Sol medium (48) > Terra xhigh (45) > Terra high (44)
Apalagi klo pilihannya speed, Sol itu 69 tps, Terra 91 tps
OpenAI has released GPT-6.1 Terra, pushing the cost efficiency frontier. It is the first Terra-class model since GPT-5.6, and is more intelligent for less than a third of the cost
Pricing per token is half or less that of GPT-5.6 Terra - at $1/$5 per million input/output tokens vs $2/$12 for the previous model. Cache write has also halved, now at $1.25 per million tokens. Cached input is one quarter at $0.05 vs $0.20 per million tokens.
Key takeaways:
➤ Pareto-optimal for Intelligence vs Cost at low and medium effort: At max effort, GPT-6.1 Terra gains 6 points in the Artificial Analysis Intelligence Index over GPT-5.6 Terra, at less than a third of the cost per task ($0.40 vs $1.40). At lower effort levels the gain is larger, between 7 and 13 points. The low and medium effort levels are Pareto-optimal for cost efficiency, while the other effort levels sit behind the frontier. At max effort, the model scores 4 points below GPT-6.1 Sol and 10 points above GPT-6 Luna in the Intelligence Index.
➤ Pushes the Coding Agent Index cost efficiency frontier: With a score of 48 in the newly released Artificial Analysis Coding Agent Index v2.0, the model is 6 points below GPT-6.1 Sol (54) and 17 points above GPT-6 Luna (31). The xhigh and low effort settings sit on the frontier of cost efficiency in the Coding Agent Index, while other effort levels are behind the frontier.
➤ 50 point drop in hallucination rate: GPT-6.1 Terra guesses 38% of the time when it does not know the answer to a question in AA-Omniscience, our private knowledge and hallucination benchmark. Previously, GPT-5.6 Terra's hallucination rate was 88%. This significant reduction in hallucination is coupled with a 2 point increase in AA-Omniscience accuracy - meaning the model simultaneously answers more questions correctly.
➤ 20 point jump in Terminal-Bench 4.0, small improvements across most evaluations: The model makes significant progress in the terminal-based agentic benchmark, Terminal-Bench 4.0, with a gain of ~20 points, now rivaling GPT-6.1 Sol at max effort. Gains across most other evaluations are smaller, for example, 5 points in GDP.pdf.
Congratulations @OpenAI and @sama on the launch!