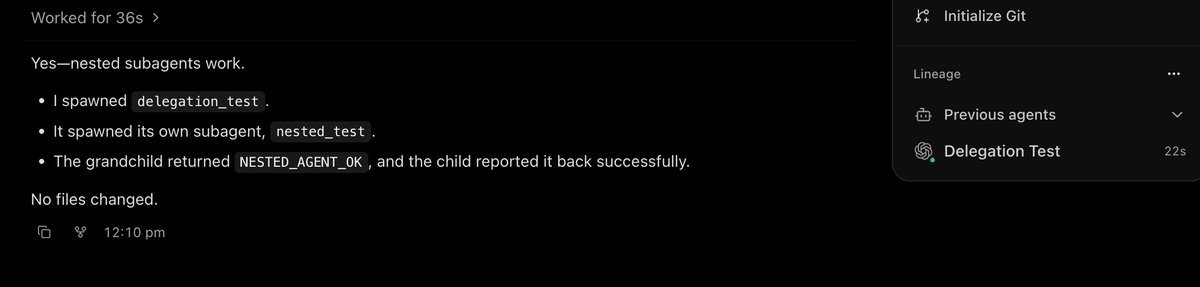
My Orchestrator created an orchestrator subagent that created it's own worker subagents. 🤦♂️ My skill was too specific on which model should be the leader.
fyi @t3dotcodes the breadcrumbs and agent lineage don't support this.
One for the parents - built a little yoto story toolkit.
It uses @FishAudio's free TTS models to create custom stories, bundles them up with animated icons and ships them straight to a Yoto playlist.
My son loves the cars choose your own adventure stories
https://t.co/ratpjrKoMq
@lxe damn, that looks pretty useful for real device debugging. Agents have had no issues with wireless ADB on android, but I haven't looked into a good alternative on iOS.
@theo It's a great strategy, It produced some really nice changes. I made one small change and fed it a different comparison source based on the feature rather than 1:1 comparison.
@weswinder I use 1 orchestrator to spin up a bunch of subagents. They generally have their own worktrees.
the real key is setting up the skill or agent.md to consistently run the workflow. slice up the work, track events, proper subagent handoff, review.
just released KURB’s for you page.
2 user vectors matched against 150m+ item vectors. still trying to find a good ux for taste discovery embeddings though
this is the universe version
@jmt@itssotsot@theo current setup is:
t3 orchestration skill that delegates to specific subagents based on my model preferences for tasks
e,g sol.6.1 -> deepseek-v4.1-flash-1017, glm-5.3, sol.6.1
+ a verification/audit loop
it's so much faster and I feel like I can trust the output more
@jmt@itssotsot@theo Having the agents create the tasks gave me 0 visibility as to what was going on. I was constantly getting notified for approval requests for things I didn't understand (not to mention not even knowing how to approve the task clearly). The agents would get stuck all the time.
sub 1s reverse image + text search on 153m vectors. 1 qdrant collection with named vectors.
merging it cost me 4 days, a power cut mid agent run, and a zombie worker that rebuilt the old collections after deletion...
@qdrant_engine
fixed up kurb’s bm25 index query after upgrading @paradedb. changed how exclusions are applied so they filter results without affecting relevance scores.
on 51 million rows, a simple query went from 4.5 seconds to 350ms.
~13x faster, pretty happy with that
@theo haha nice! I didn't realise this was a new feature. I just set something like this up last night with my dot after your https://t.co/8BtsWFv6FZ lesson
been tinkering with kurb’s spider using contextual bandits and vowpal wabbit 🐇 32k observations and a week later on our €70 clanker. astra says we can check the results tomorrow. either it worked or i’ve wasted millions of tokens and made the poor little server work harder 💀