i just hope we’ll get to a place where inference is 100x faster than it is now
its either they get 100x faster (one dimensional) or 100x more capable (loosely defined) with the latter letting you basically one/zero shot everything (zero shot - model passively collects data about you and helps you accomplish goals) so you could argue flow is “preserved”
my guess is we would someday taper off on the capability gains front, and then we’d use all that capability to basically get instant inference so people would be able to use agents with ACTUALLY good ux.
The agent worked 20 minutes per day on average. Almost all the effort happened in the first 4 weeks, though most downloads came after.
Despite doing no external outreach, the account is still in the top 0.3% of downloads across same-age accounts.
אני לא בטוח שזו המסקנה הראשית המתבקשת
בשביל קריירה שנוגעת לדוגמה בצ׳יפים (או כל קריירה שדורשת תואר בהנדסת חשמל) עד עכשיו וכרגע המסלול היחידי שיכול לעבוד הוא לעשות תואר בהנדסת חשמל
בעוד שבשביל קריירה בעולמות התוכנה/applicative ai לא בהכרח נדרש תואר בתחום היום וזה כנראה ישאר ככה. משמע תואר הוא הרבה יותר nice to have מאשר חובה.
אנשים מתייחסים לתואר כמטרה ולא כנקודת ציון וזה הבעיה, חוסר first principled thinking.
קיים עולם בו מי שהולך עכשיו ללמוד הנדסת חשמל עושה טעות והידע שהוא רוכש בתואר יהיה הרבה יותר nice to have מאשר חובה בנקודה שיסיים. לדעתי זו אפילו האפשרות הסבירה ביותר בהינתן ההתקדמות של AI.
i just hope we’ll get to a place where inference is 100x faster than it is now
its either they get 100x faster (one dimensional) or 100x more capable (loosely defined) with the latter letting you basically one/zero shot everything (zero shot - model passively collects data about you and helps you accomplish goals) so you could argue flow is “preserved”
my guess is we would someday taper off on the capability gains front, and then we’d use all that capability to basically get instant inference so people would be able to use agents with ACTUALLY good ux.
Agent work is the most frustrating and deeply unsatisfying way of working I’ve experienced
It is impossible to get in the flow of a task when you have 3 separate things going on, each step of progress needs you to wait 1-3 mins per task, then needing to parse a big wall of text before you decide the next step
And while you’re waiting for information to become available you inevitably get distracted, making the task even longer because you forget all the things going on in parallel (hence why I’m writing this tweet)
I don’t know what the solution or if there even is one but I wish there was something better than just an endless sidebar of tabs fighting for my limited attention
thats what happens when you lose mental model of the code.
in all seriousness tho prime is a prime engineer - but i have seen it happen irl and its the worst thing that could happen in prod.
the way i see it there are two opposing schools of thought: either you slop max, everything gets its own infra/repo and u basically oneshot everything into existence (but dont expect to share code or responsibilities between them!), or u take the small time at each new feature dev to understand what it does to the codebase architecture-wise.
🚨 This is made by Fable 5.2.
No image model made this. No diffusion, no photos, no textures, no 3D software, no render engine. Every pixel was computed by code Fable 5.2 wrote for this one picture.
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: https://t.co/bOWCcFhCVq
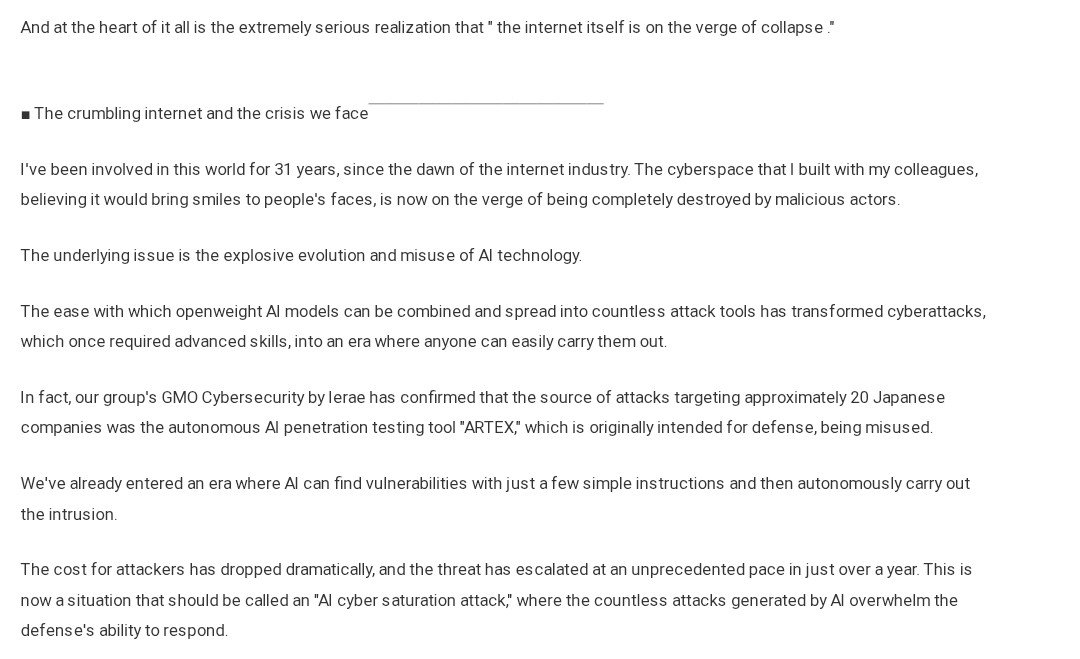
GMO Internet Group CEO Masatoshi Kumagai says that the internet itself is on the verge of collapse due to missuse of AI, and frames this event as a national crisis.
Introducing Reinforcement Learning from Collective Rewards (RLCR).
RLCR is a recipe that trains language models as agent organisations, which share a message board and workspace. We use it to train Avalon-M1-Mini (120B) and study its behaviour.
We find a number of interesting results, including:
🛠️ Learnt organisational hierarchies and divisions of labour
🕵️ Increased collective verification, through hires of verifiers and testers
👥 The rise of collective thinking, where agents think more about other agents and how to help them
We believe RLCR can provide a laboratory for studying collective intelligence and multi-agent safety.
Blog post and technical report 👇
every breakthrough in my life has come from a bout of obsession...
1-2 months where i lock myself in the office, eyes glued to the screen, forgetting to eat
i've never found balance to work for me - in my eyes balance = maintenance, growth comes in bouts of obsession
i wish i could consciously trigger this obsession for anything i wish, but it seems like it's a force that takes over when it needs to
they've been non stop trying to attack our systems for the past 48 hours
a side effect is everything is getting hardened but damn we basically need agents going 24/7
because that's what they have
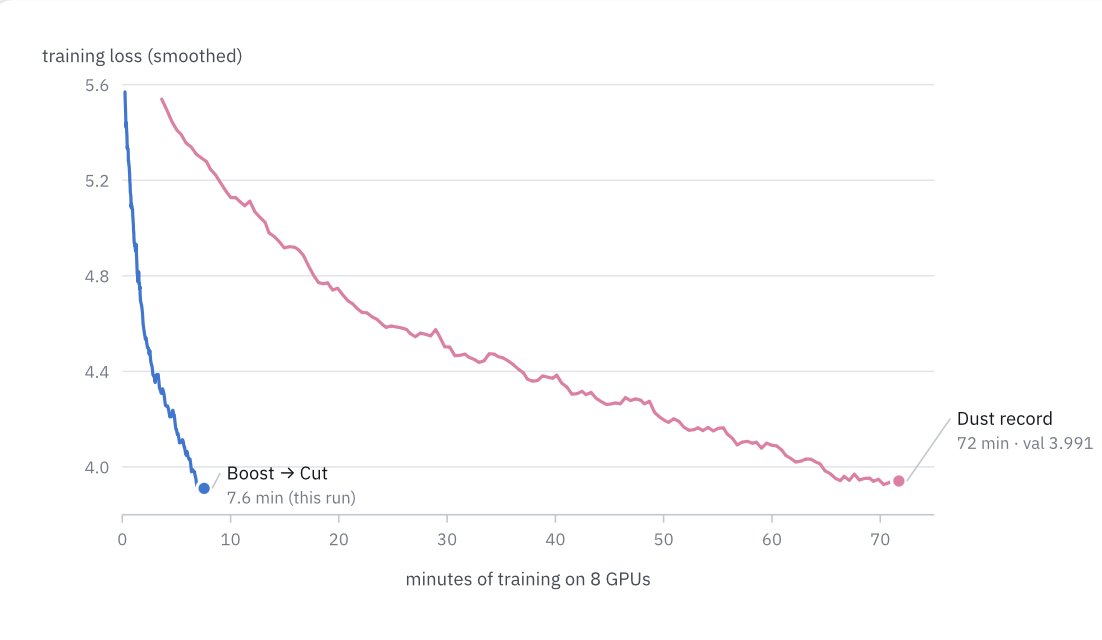
Inspired by Nick Cammarata’s interpretability essay “Neural Networks Are Already Clean”, I turned a couple of its ideas into speedups for pretraining without backpropagation. Still in the works. 2.3x speedup, cool https://t.co/VOEbLacbhq
been saying for a long time that 100x-ing inference speed would unlock so so so many new products
somebody/them need to package this kind of speed into an agentic experience
FINALLY would be a flow preserving agentic experience
i’m today years old when i learned about https://t.co/0UHaUQpCfm - you can just play with their demo right there
and holy cow i was NOT prepared for what 15000 tokens/s feels like. mind blown
apparently they achieved it by hardwiring model weights into the chip. and looks like the team got acquired by $AMD
i hope they keep at it and bring it to mainstream because this is probably one of the most magical things i experienced lately