@PeasantSmith You have a lot of models on the Model page (VERY NICE). Which do you recommend for 3090 ampere and even Blackwell GPU's please? E.g. this: DeepSeek V4.1 · EXL3 3.5 bpw vs this: DeepSeek V4.1 · UD-Q8_K_XL (similar'ish size) ?
@PeasantSmith@ItsmeAjayKV What I want to know is if it can pull the fastest milk cart in the west?
(How old are you dude - I think I just framed myself!) :-)
I have an old Xeon server with 24GB of ram. I am thinking of firing it up to see if I can get it to inference (with a low cost GPU) - if I can get Maya on that, it would further call into question the need for these massive data centers. I do have an old A770 GPU, but I don't think that works, but maybe I can codge something together. It would be a cool project...
@FloridaBoarHog@PolkCoSheriff Disagree. I voted for 3 and I sure as heck will vote for Grady. I can disagree with him and still have a brain. I know his job is tougher because of 3, but the last thing I would want is to lose him as my Sheriff.
What do you want, California law and order?
I got my answer, direct from Qwen-3.8-Flash-Next:
"Yes — a safer replacement script is absolutely the right move.
But be clear about what it will and will not do:
...{lots of explanation}...
This will prevent most of the “fuckery” from happening again."
If that alone doesn't justify local ai, what does! LOL
I wonder what Claude and co would say if I typed this to them instead of my local model:
"Ok, so that’s a lot of editing that I will screw up. It’s lower risk for me to wipe the db and re-enroll everything. Can you provide me with a fully functioning replacement script that might fix all the fuckery please?"
(A real prompt, that Qwen is running for me now, and she hasn't banned me yet!)
I am blown away by the performance of Basalt. I have never seen such performance from any model, including from my paid subscriptions. And the quality is there - I had this fixing a complex ZFS issue today, and it did the job better than Qwen-3.8-27B. It is game-changing. Friggin' awesome!!
I think people are confusing wear and tear: drive READS are fine. It's WRITING that causes harm. I don;t see how this is a big issue for any of these models since they write once (download) then ready many (operation)? So how can that cause any more wear and tear than anything else they run? What am I missing?
Dude, I run EPYC servers too - EPYC Milan 72F3 CPUs, 256GB RAM and all channels populated, so if you need me to do any testing, let me know. As long as I can understand it, I will try to execute it.
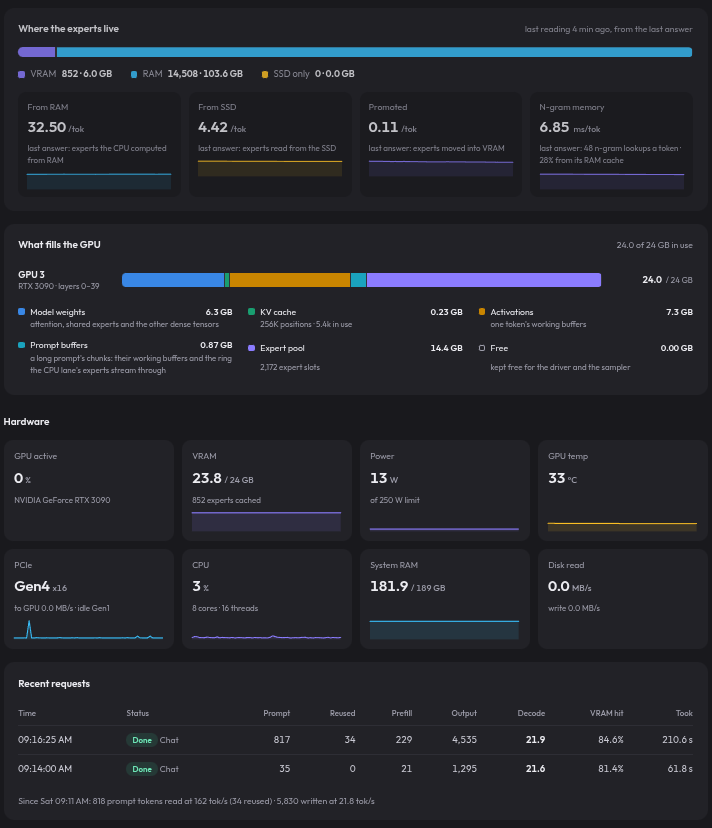
I have never run GLM on one 3090, but this is what I get on ONE 3090 with Maya running DeepSeek.