How well do vision foundation models understand the parts and the structure of objects?
Introducing SOCO, our benchmark for Semantic Object Correspondence, appearing as a Spotlight at #ECCV2026.
🌐 https://t.co/qDXYlKQZvS
👇
🚀 We're hiring multiple fully funded PhD students through the #ELLIS PhD Program!
Join us to work on generative AI, world models, and AI safety.
https://t.co/v9V1DCZJ1b
Apply by Oct 31 via https://t.co/GSIsBVzR4y
Spread the word!
@odysseyml takes the first place on Physics-IQ Verified in the video to video (v2v) category with Odyssey 3 Pro.
Full Leaderboard: https://t.co/HvkfSlIfsW
In the image to image (i2v) category we still have a head to head race with @bfl_ai.
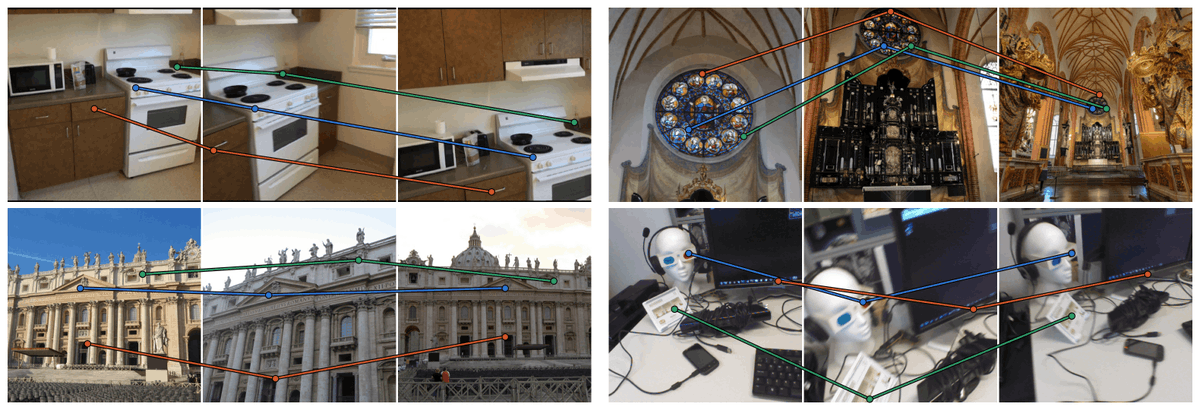
Today we release Poincar3, our newest 3D model trained entirely through SSL on RGB image sequences.
I find the coolest thing is that, without labels, it learns multi-view geometry. Just using the attention map, reliable tracks can be formed (see below).
https://t.co/P1nShNSMR6
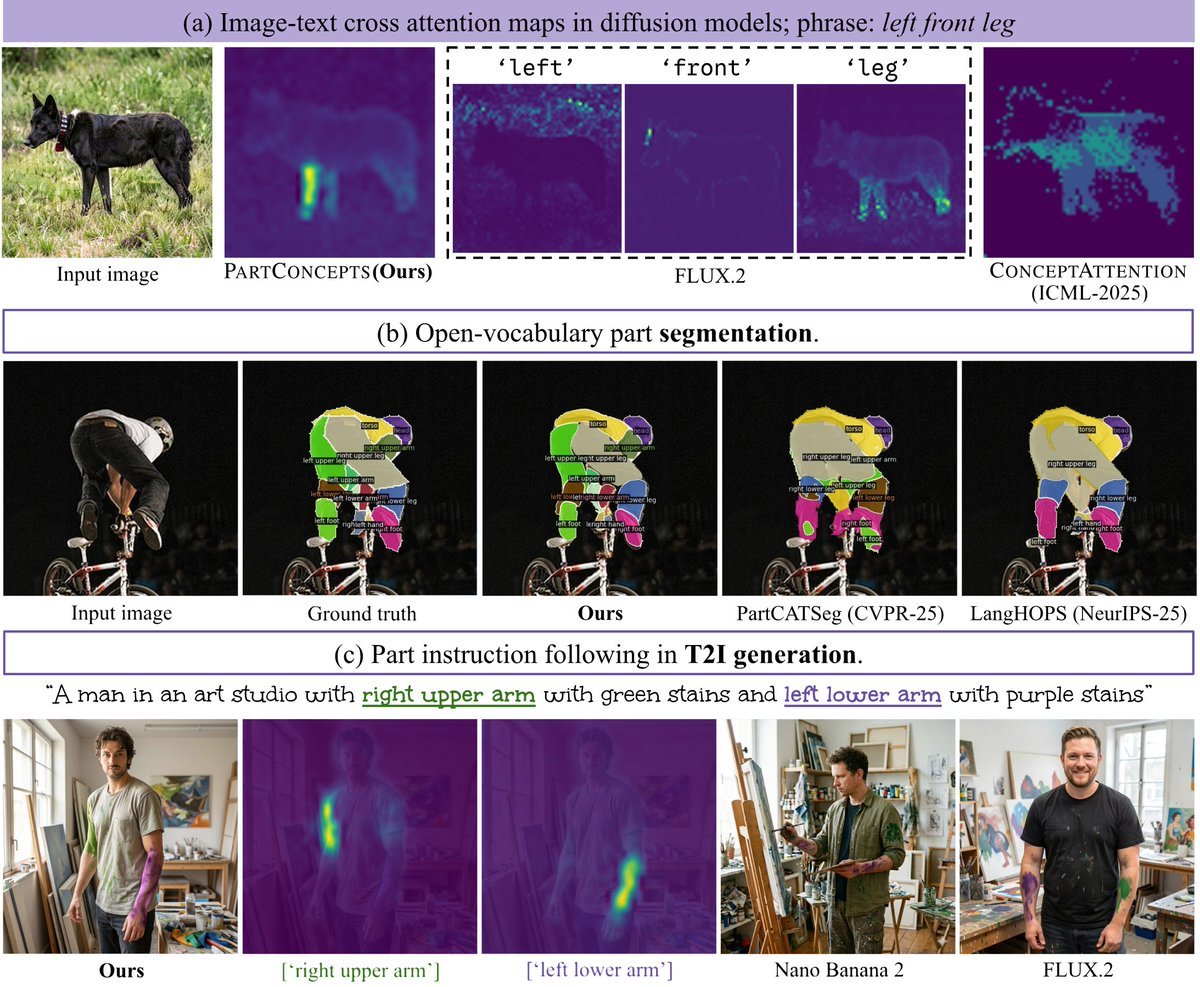
Excited to share PartConcepts, a unified mechanism for fine-grained part localization and generation, accepted to #NeurIPS 2026 @NeurIPSConf 🥳🥳🥳
🌐https://t.co/99u5qyfjP3
🏆 And congratulations again to all authors of "Target-Bench: Can Video World Models Achieve Mapless Path Planning with Semantic Targets?" for winning the Best Paper Award!
Check out their project page: https://t.co/49QSwuskcd
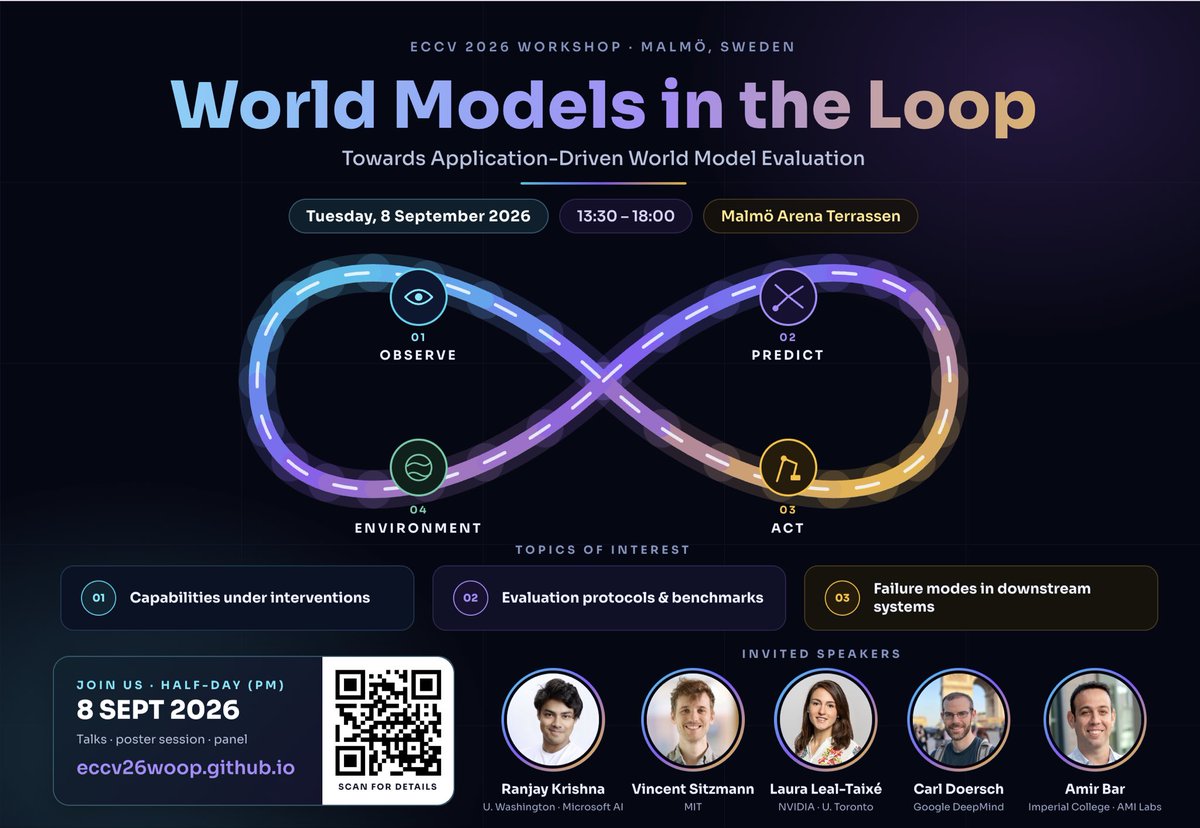
WOOP @ #ECCV2026 !
As part of the ECCV workshop on World Models in the Loop, we are inviting submissions of papers to our Non-Proceedings track, accessible via https://t.co/QbjzUakIEi
Organizers: @NhiPham49@KenJSimmoteit@thunguyenphuoc@AdamKortylewski
See you in Malmö!
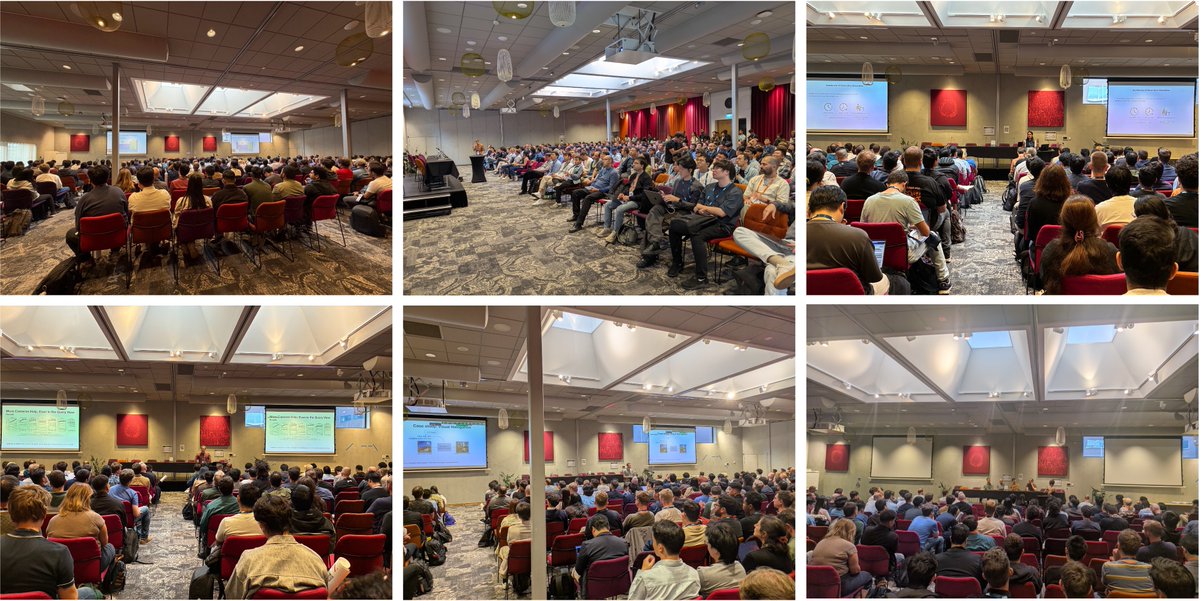
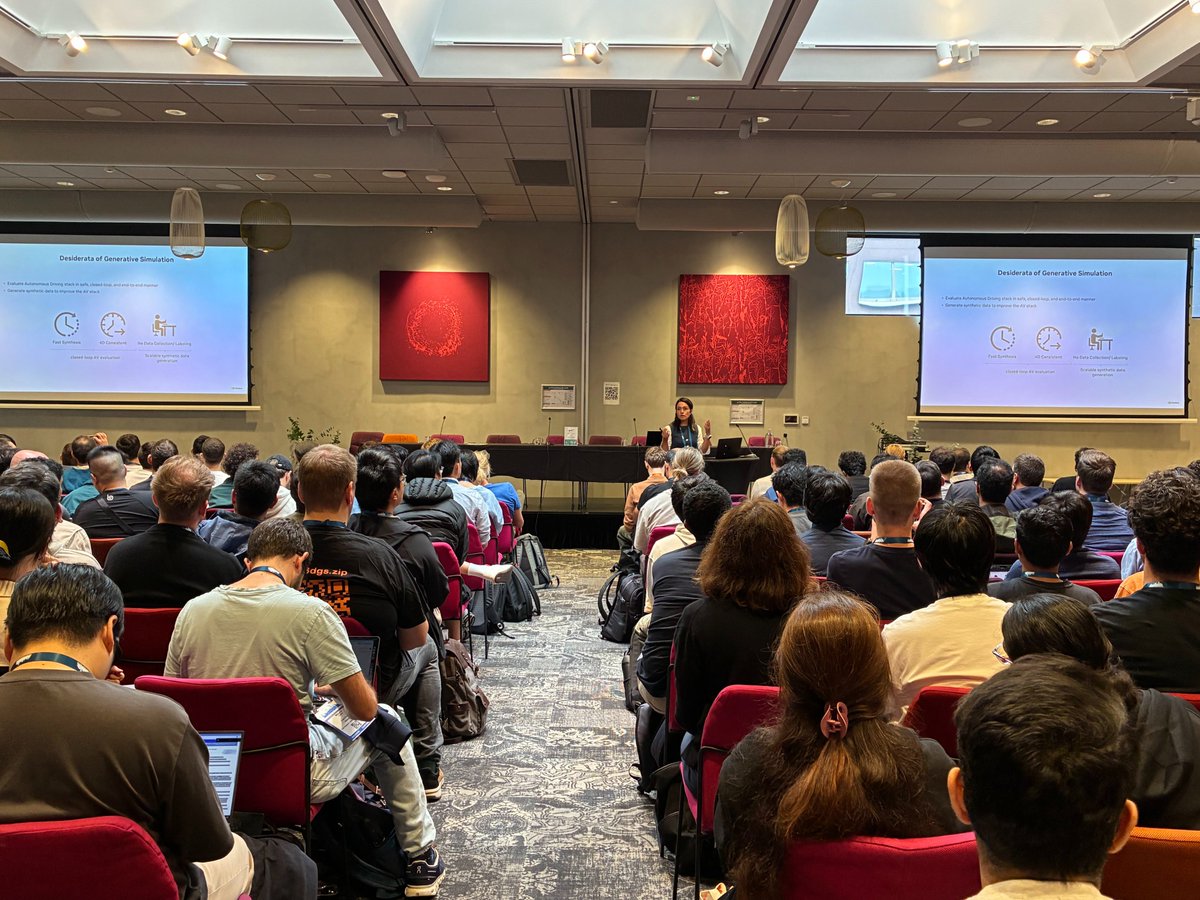
We had a great first half of our workshop !
Looking forward to our 2nd half with talks from
Carl Doersch (16:10-16:40)
Amir Bar (16:40 - 17:10)
and a surely spicy panel discussion with Amir Bar, Carl Doersch, Vincent Sitzmann, Andrea Tagliasacchi (17:10 - 17:50)
WOOP @ #ECCV2026 !
As part of the ECCV workshop on World Models in the Loop, we are inviting submissions of papers to our Non-Proceedings track, accessible via https://t.co/QbjzUakIEi
Organizers: @NhiPham49@KenJSimmoteit@thunguyenphuoc@AdamKortylewski
See you in Malmö!
17:10 - 17:50 : 🎤 Panel discussion with Amir Bar, Carl Doersch, Vincent Sitzmann, Andrea Tagliasacchi,
moderated by Thu Nguyen-Phuoc
17:50 - 18:00: Closing Remarks
WOOP @ #ECCV2026 !
As part of the ECCV workshop on World Models in the Loop, we are inviting submissions of papers to our Non-Proceedings track, accessible via https://t.co/QbjzUakIEi
Organizers: @NhiPham49@KenJSimmoteit@thunguyenphuoc@AdamKortylewski
See you in Malmö!
17:10 - 17:50 : 🎤 Panel discussion with Amir Bar, Carl Doersch, Vincent Sitzmann, Andrea Tagliasacchi,
moderated by Thu Nguyen-Phuoc
17:50 - 18:00: Closing Remarks
WOOP @ #ECCV2026 !
As part of the ECCV workshop on World Models in the Loop, we are inviting submissions of papers to our Non-Proceedings track, accessible via https://t.co/QbjzUakIEi
Organizers: @NhiPham49@KenJSimmoteit@thunguyenphuoc@AdamKortylewski
See you in Malmö!
@Gerrylwk Examples might be heavy weather changes, impact by external effects like flooding etc.
Essentially, we are targeting not only evaluating point matching but also registration, which can be also relevant for scenes, not only objects.
How well do vision foundation models understand the parts and the structure of objects?
Introducing SOCO, our benchmark for Semantic Object Correspondence, appearing as a Spotlight at #ECCV2026.
🌐 https://t.co/qDXYlKQZvS
👇
@Gerrylwk Our current setting focuses one single objects but extending this formulation to scenes would be surely interesting! Eg finding correspondences across scenes that have similar scene layout / object composition / semantics etc but still vary substantially...?
Shared work with
@SunagadR (equal contribution)
Haoran Wang, @DavidTHoffmann, Christian Theobalt & @AdamKortylewski
Find us at #ECCV (Thu Sep 10):
🎤 Spotlight: 10:05–10:10
📌 Poster #477: 10:30–12:30
Happy to discuss about correspondence, representations, and model eval!
[5/6]
Alongside SOCO, we also release OmniProbe, a unified framework for evaluating visual representations across:
→ Correspondence
→ Segmentation
→ Depth & surface normals
→ 3D pose
→ Detection
→ Tracking
→ Classification
→ and more
🔧 https://t.co/ICrHWpO0lg