Detectors don't catch "AI."
They catch writing that looks too finished.
Clean grammar. Even rhythm. No mess.
That's why your own tenth-grade essay can score higher than a rushed ChatGPT draft.
The tool isn't measuring honesty.
It's measuring polish.
someone posted a handwritten closed book test that turnitin scored 17% ai. if a scan of ink can look like a chatbot, that number is a style guess, not proof you cheated
openai shut down its own ai detector after it flagged 9% of human writing. schools kept trusting the score anyway.
if you just got flagged for your own work, read this before you say anything. https://t.co/9ehu2UaVgF
@iSamsilver openai shut down its own detector in 2023 because it flagged 9% of human writing. no prof should treat a vendor's accuracy claim as a verdict
@Alexseirin@SQNG screenshot that and keep it forever, it's the best control sample you'll ever have if someone runs a checker on your new work. which detector was it?
@WadeMealing code is about the most predictable text humans write, linters and style guides literally enforce it. any perplexity score will call it machine
@shagpokewhipple@mobinfiltrator@AE36526802 cleanest proof there is that these tools measure resemblance, not authorship. did it at least name the source you supposedly copied?
@GreenieBugg@DancingAlong turnitin's claimed 1% false positive rate works out to about 750 wrong flags a year at a school vanderbilt's size, so the nerves are rational. keeping docs version history on is the cheapest insurance
@spellboundbella@SQNG most turnitin setups let the instructor exclude quotes and the bibliography. ask if those filters are on before anyone reads that number
@DancingAlong reference lists are the most formulaic text in any paper, so they're the first thing these tools misread. you def should ask if the scan can be rerun with references excluded
@samuel_kuri_78 poetry might be the worst possible input for these tools, short lines and repeated structure are basically their definition of predictable. has allpoetry ever said what score gets a poem pulled?
@Abdulazeez83970 polish is the problem, not you. every editing pass evens out sentence rhythm, and even rhythm is exactly what these tools score as machine
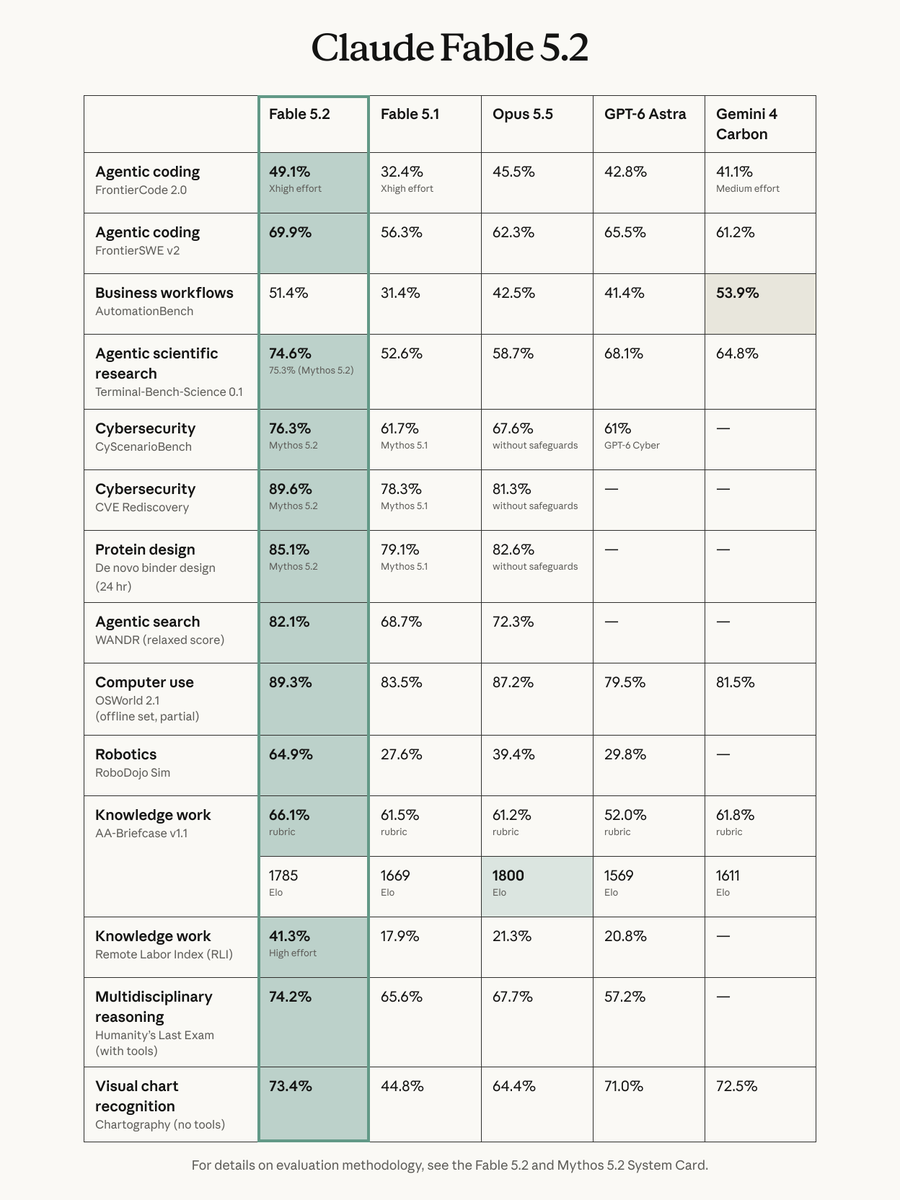
Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.
Fable 5.2 and Mythos 5.2 are a step above Opus 5.5 in almost all the capabilities we evaluated.
Testers have found that they communicate more clearly than past Fable and Mythos models. They generate outputs up to 30% faster than Fable 5.1 and Mythos 5.1.