Today we are releasing two small models: Mathstral 7B and Codestral Mamba 7B.
On the MATH benchmark, Mathstral 7B obtains 56.6% pass@1, outperforming Minerva 540B by more than 20%. Mathstral scores 68.4% on MATH with majority voting@64, and 74.6% using a reward model.
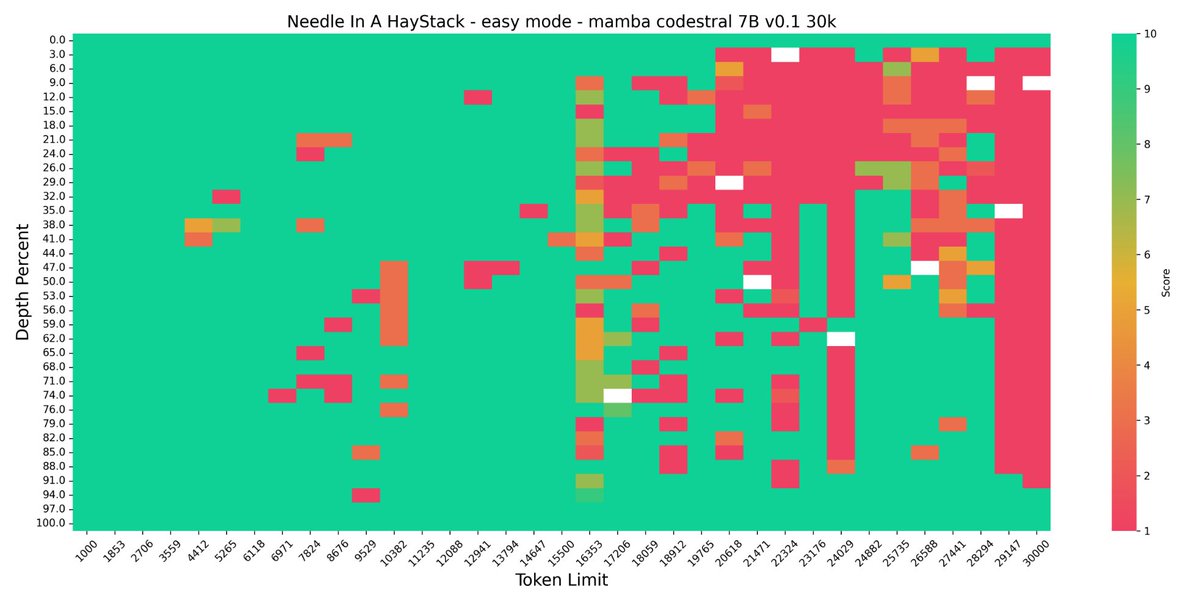
Codestral Mamba is one of the first open source models with a Mamba 2 architecture. It is the best 7B code model available, and is trained with a context length of 256k tokens.
Both models are released under the Apache 2 license.
https://t.co/R2pc6u45zL
https://t.co/9szAM62xi5
🚀Exciting new!
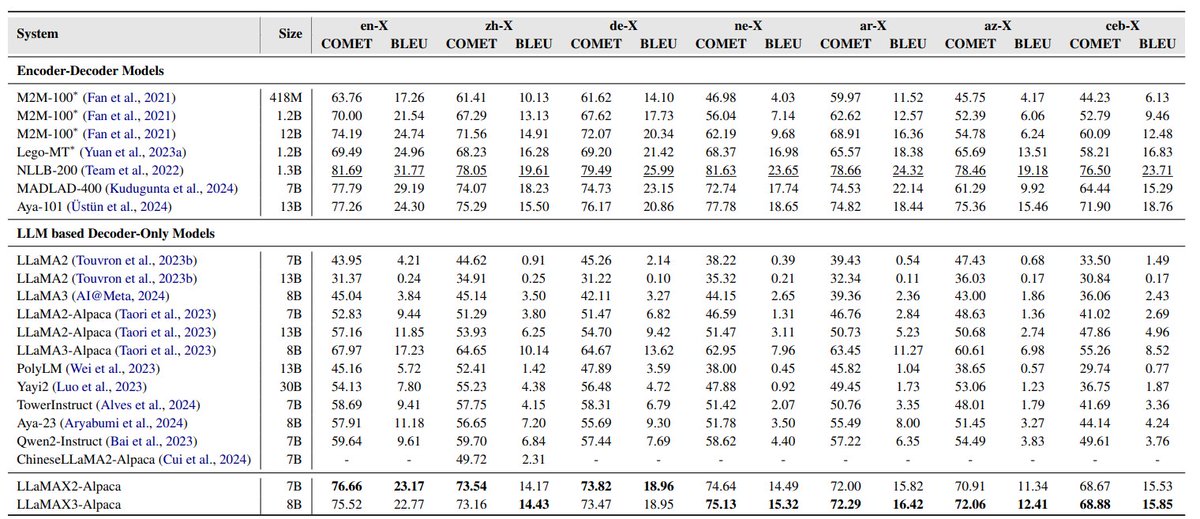
Introducing LLaMAX, a powerful LLM with enhanced translation performance across all 101 languages.
🔥 LLaMAX provides a better starting point for multilingual tasks and lots of analysis on the multilingual continual pre-training.
https://t.co/0RdwuA3k0v
🚀 Exciting research alert! 📘 Our latest paper on "Scaling Laws for Linear Complexity Language Models" is reshaping scaling laws for linear complexity language models boundaries! 🧠✨
🔍 We delve deep into three cutting-edge linear complexity architectures: TNL, HGRN2, and cosFormer2, and benchmark them against the classic LLaMA. Discover how these models, ranging from 70M to 7B parameters, tackle a massive 300B-token corpus across various tasks!
🔗 Dive into the full study for a peek into the future of linear complexity language models.
https://t.co/RH5UFTnwn3
#LLM #ScalingLaws #LanguageModels #MachineLearning #AIResearch
🚀 Introducing TAVGBench: the ultimate benchmark for Text to Audible-Video Generation! With over 1.7M clips and 11.8K hours, our new TAVDiffusion model aligns audio-video with cutting-edge cross-attention and contrastive learning techniques. Discover how our Audio-Visual Harmoni score (AVHScore) quantifies synchronization excellence. Dive into the future of multimedia research! 🎥🔊
Paper: https://t.co/WIkqbEWRGr
GitHub: https://t.co/6PVc9sklEI
Youtube: https://t.co/sfkAtekDOm
#AI #MachineLearning #TAVGBench
Introduce to our novel Audible-Video Generation Datasets and Diffusion Model
We present TAVGBench, a benchmark with 1.7 million clips for text-based audio-video generation, and introduce TAVDiffusion, a model that enhances audio-video alignment using advanced learning techniques, validated by our novel Audio-Visual Harmoni score (AVHScore).
https://t.co/gAdrvO8iMs
HGRN2
Gated Linear RNNs with State Expansion
Hierarchically gated linear RNN (HGRN,Qin et al. 2023) has demonstrated competitive training speed and performance in language modeling, while offering efficient inference. However, the recurrent state size of HGRN remains
We are excited to introduce HGRN2, the latest innovation in the field of efficient language modeling. Building upon the success of Hierarchically gated linear RNN (HGRN), HGRN2 represents a significant advancement in training speed, performance, and inference efficiency.
Arxiv: https://t.co/AO0exz0ZvX.
GitHub: https://t.co/SV8ksjsFmm
Huggingface Collections (model will release soon): https://t.co/ILxGQFAjci
We propose an upgrade to the Hierarchically Gated Linear RNN: HGRN2!
HGRN2 enhances language and image processing by using a state expansion mechanism that doesn't add extra parameters. This novel approach not only speeds up training but also enables more expressive models and hardware-efficient training. Our studies show significant improvements over HGRN in various tasks.
In meanwhile, we announce Rhino General as our mascot of HGRN2!
Coding is now available on: https://t.co/SV8ksjsFmm.
#HGRN #HGRN2
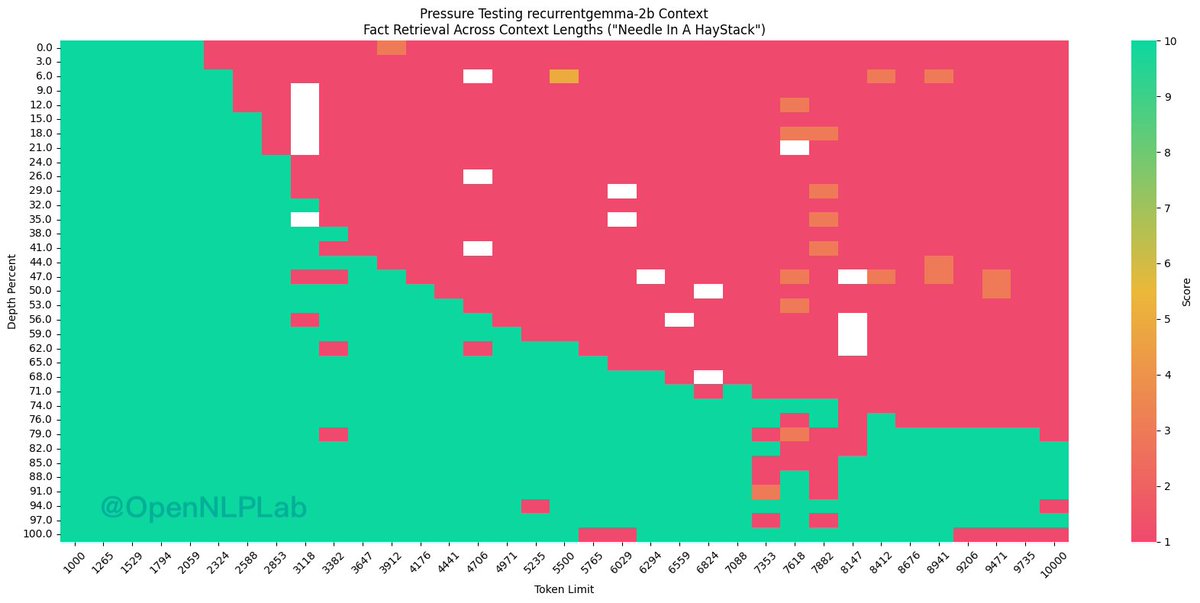
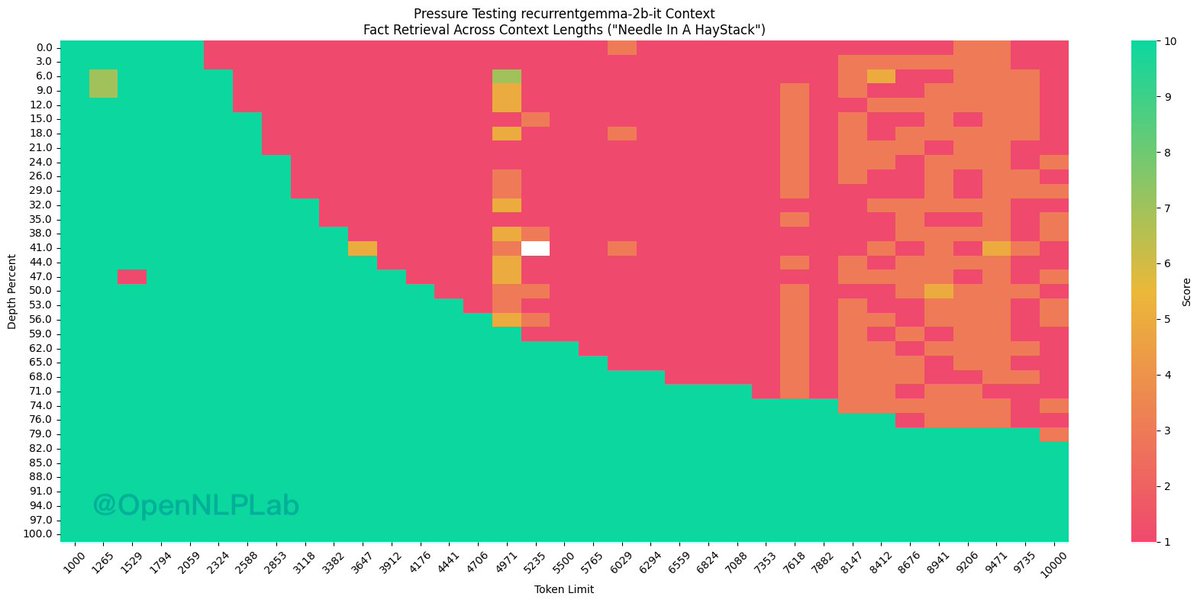
We've recently benchmarked the Needle in a Haystack of RecurrentGemma 2B and its instruction version @Google@SamuelMLSmith using this resource: https://t.co/uqKWHlyUVu.
The results achieve our expectations, showcasing a mix efficiency model architecture that combines window attention with linear RNN.
#NeedleInAHaystack #RecurrentGemma
TransNormerLLM-15B Training Progress - Day 105
Today's Training Progress Update:
Data Consumption:
The model has digested over [1422B] of data.
Performance Improvement:
The model's loss value hovers around [2.34].
Our training has advanced to Stage-2, where the sequence length has been increased to 11K.
TransNormerLLM-15B Training Update - Scaling to 10M Seq Length
After completing the Stage-1 training phase, we will gradually increase the sequence length to 10M (original training length) and have used a series of updated and longer datasets for subsequent training phases.
Based on some feedback we've received, we've decided to adjust the frequency of progress updates for subsequent training: instead of daily updates, we will now provide updates twice a week, specifically on Monday and Thursday evenings. At the same time, the release time for evaluations is adjusted to Tuesday and Friday evenings, while weight updates are scheduled for every Monday.