nanochat now trains GPT-2 capability model in just 2 hours on a single 8XH100 node (down from ~3 hours 1 month ago). Getting a lot closer to ~interactive! A bunch of tuning and features (fp8) went in but the biggest difference was a switch of the dataset from FineWeb-edu to NVIDIA ClimbMix (nice work NVIDIA!). I had tried Olmo, FineWeb, DCLM which all led to regressions, ClimbMix worked really well out of the box (to the point that I am slightly suspicious about about goodharting, though reading the paper it seems ~ok).
In other news, after trying a few approaches for how to set things up, I now have AI Agents iterating on nanochat automatically, so I'll just leave this running for a while, go relax a bit and enjoy the feeling of post-agi :). Visualized here as an example: 110 changes made over the last ~12 hours, bringing the validation loss so far from 0.862415 down to 0.858039 for a d12 model, at no cost to wall clock time. The agent works on a feature branch, tries out ideas, merges them when they work and iterates. Amusingly, over the last ~2 weeks I almost feel like I've iterated more on the "meta-setup" where I optimize and tune the agent flows even more than the nanochat repo directly.
Could this loop execute in parallel, and run orders of magnitude faster? Project Babylon (experimental) allows running Java code directly on the GPU (yes, even the one in your laptop). See how in our @Jfokus talk with @ammbra1508 https://t.co/sZI74ByO9K
New TornadoVM release v1.1.1!
Packed with new features and optimizations that unlock GPU acceleration for Llama3 in pure Java!
🧬JIT-compiled kernels for high performance.
👏 Thanks to our amazing contributors.
👉 https://t.co/FiQtx0m5SA
#opensource#AI#LLM#Java#TornadoVM
Here is the transcript of the PDF made with AWS Textract, awk and manually. Details are in the repo. A reasonable next step could be a port to NASM. Anyone in the mood?
#altairbasic#microsoft#retrocomputing#pdp10
https://t.co/ayWQzJVf30
https://t.co/VsolXaAqFX
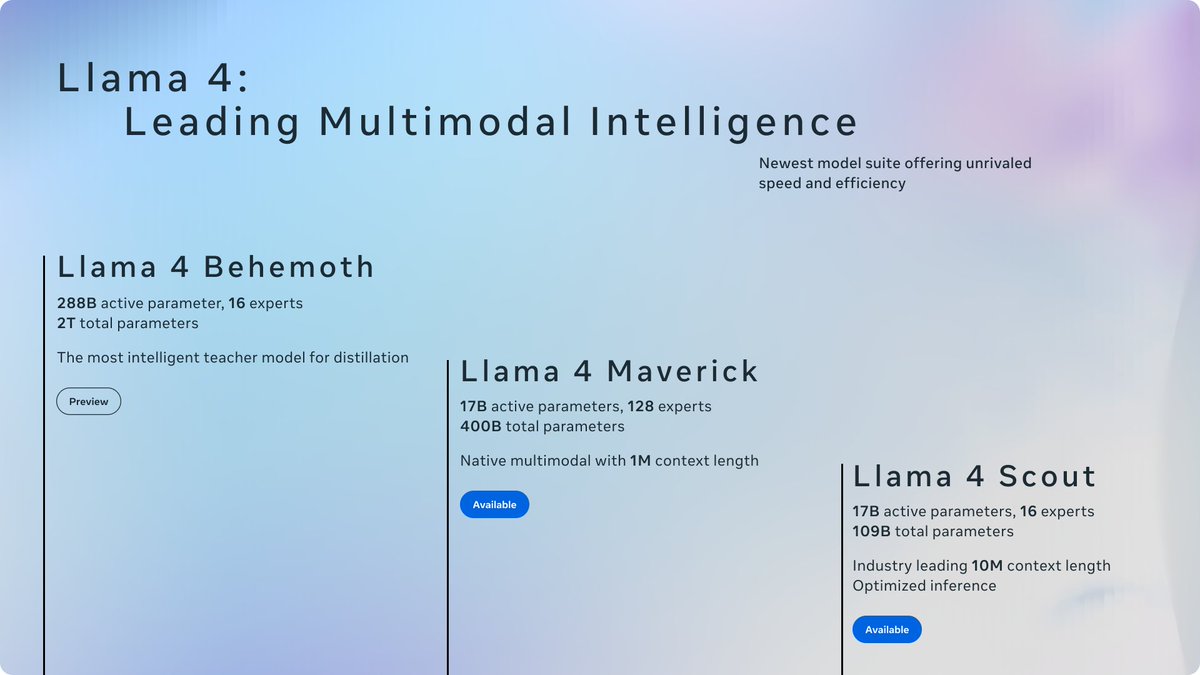
Today is the start of a new era of natively multimodal AI innovation.
Today, we’re introducing the first Llama 4 models: Llama 4 Scout and Llama 4 Maverick — our most advanced models yet and the best in their class for multimodality.
Llama 4 Scout
• 17B-active-parameter model with 16 experts.
• Industry-leading context window of 10M tokens.
• Outperforms Gemma 3, Gemini 2.0 Flash-Lite and Mistral 3.1 across a broad range of widely accepted benchmarks.
Llama 4 Maverick
• 17B-active-parameter model with 128 experts.
• Best-in-class image grounding with the ability to align user prompts with relevant visual concepts and anchor model responses to regions in the image.
• Outperforms GPT-4o and Gemini 2.0 Flash across a broad range of widely accepted benchmarks.
• Achieves comparable results to DeepSeek v3 on reasoning and coding — at half the active parameters.
• Unparalleled performance-to-cost ratio with a chat version scoring ELO of 1417 on LMArena.
These models are our best yet thanks to distillation from Llama 4 Behemoth, our most powerful model yet. Llama 4 Behemoth is still in training and is currently seeing results that outperform GPT-4.5, Claude Sonnet 3.7, and Gemini 2.0 Pro on STEM-focused benchmarks. We’re excited to share more details about it even while it’s still in flight.
Read more about the first Llama 4 models, including training and benchmarks ➡️ https://t.co/9G3QgVdCkB
Download Llama 4 ➡️ https://t.co/eVomRvEr0w
New release #TornadoVM v1.1.0 is out!
Key highlights:
✅ Mixed precision computations (FP16 to FP32)
✅ New memory and buffer management features for hardware accelerators (persist & reuse data)
🔗https://t.co/kfWQMdx2Ot
Thanks to all contributors!
#opensource#Java#AI
Der zweite Teil meines Tutorials in #iX 4/ 25 bringt #LLaMA mithilfe von #ExecuTorch auf‘s iPhone, und eine Mini-App für #Xcode in #Swift zeigt, wie sich auf dem Fon mit dem #LLM chatten lässt.
https://t.co/4BVALoy7Zj
Das neue @iXmagazin 2/ 2025 bringt Teil 1 meines Tutorials zu ExecuTorch. Das Framework und API macht große LLMs passend für Smartphones und Edge-Devices. Vielen Dank an die Redaktion. #executorch#ix#heise#LLM
https://t.co/gPIiEG0MGa
Is there anybody out there in the mood for porting #CUDA kernels to #Metal compute shaders in #llm.c? Link to repo included in blog post. PRs welcome. 🙂Any other feedback as well. #Swift#LLM#GPT2#parallelcomputing#macos#ios
https://t.co/705GC6xFIw