🚩 AI-assisted scientific writing faces increasing scrutiny
Can human or LLM editing fix it?
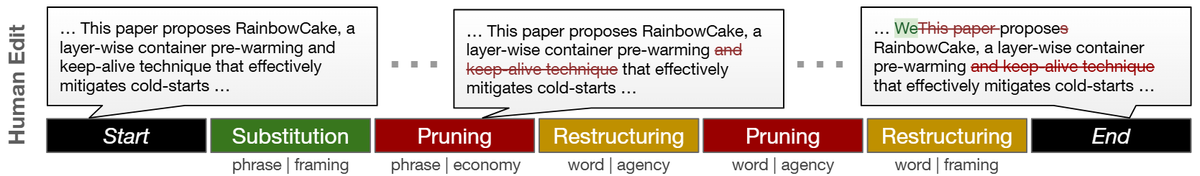
👇 240k edits on scientific abstracts expose LLM writing flaws, and show that human editing fails to fix them
cc @hsanchaita, @leadoeun27, @shocheen, @mbodhisattwa
🧵
For a limited time, you can revise your paper's alphaXiv blog
Your revisions will be published as "author-verified" and shared with our community
We're collaborating with researchers from Ai2, Ohio State & U of Utah to learn how AI-generated research blogs can better serve authors and readers
Sign up here: https://t.co/hm1HuBtSSY
open question: how will automated quality metrics and edit burst annotations generalize to longer-form scientific writing, especially in non-CS domains?
@dongyeopkang, I'm a big fan of ScholaWrite. Are you continuing with human annotation, or are you trending towards automation?
🚩 AI-assisted scientific writing faces increasing scrutiny
Can human or LLM editing fix it?
👇 240k edits on scientific abstracts expose LLM writing flaws, and show that human editing fails to fix them
cc @hsanchaita, @leadoeun27, @shocheen, @mbodhisattwa
🧵
Could our findings on the revision process help to explain the LM distortions you observed?
i.e. do you think certain editing behaviors (see 4/6) or scope misalignment predict semantic drift?
@marwaabdulhai@isadorcw@natashajaques
LLMs consistently performed larger-scoped edits than humans.
Prompting with the desired scope improves alignment, but still produces significantly larger edits.
5/6
Stay tuned as we explore how AI-assistance helps in longer-form scientific communication across diverse domains
📍 If you'd like to participate, please reach out!
Paper: https://t.co/Kb9fUryh5L
Hazra et al. (2026): https://t.co/BrrKZ3XIWV
Code/Data: https://t.co/H9Cr4u8X41
🚩 AI-assisted scientific writing faces increasing scrutiny
Can human or LLM editing fix it?
👇 240k edits on scientific abstracts expose LLM writing flaws, and show that human editing fails to fix them
cc @hsanchaita, @leadoeun27, @shocheen, @mbodhisattwa
🧵
♻️ LLMs largely improve on the same distributions that were originally strong in AI-authored abstracts
❌ LLMs only improve low-scoring abstracts to roughly average
📉 High-scoring abstracts tend to suffer or stay the same
6/6
@GoodfireAI@EricBigelow@danielwurgaft@EkdeepL This parallel has been made before in function vector/task vector papers, and our analysis showed some reliability issues across model families and scales.
Curious to hear if you have tried other scales and models?
https://t.co/U5M7i7p4Ul
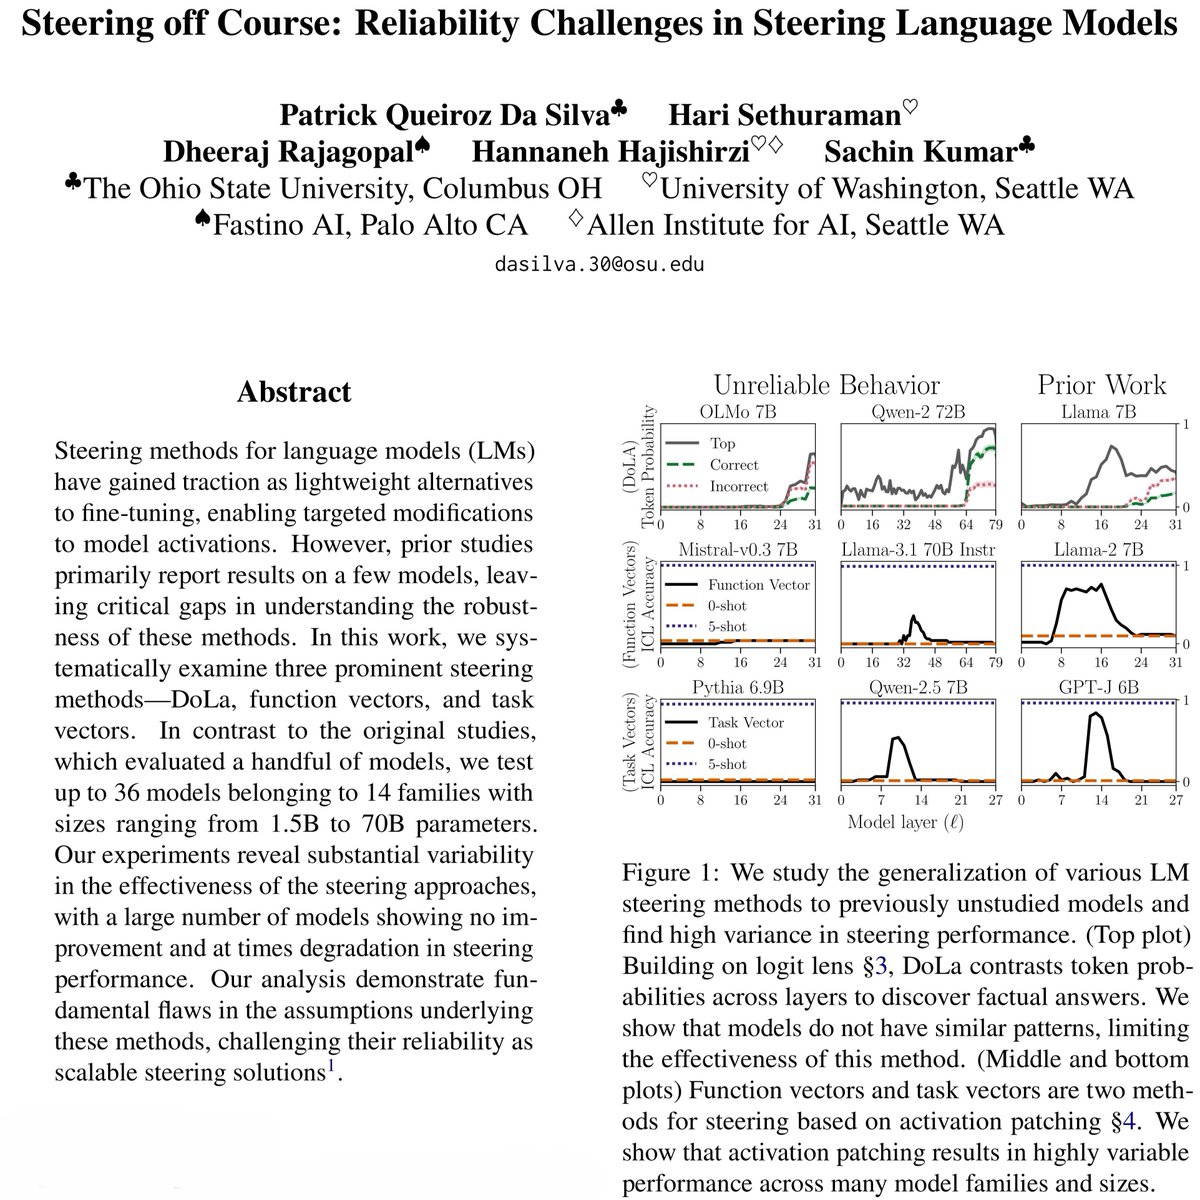
Steering language models by directly intervening on internal activations is appealing–but does it generalize?
We study 3 popular steering methods with 36 models from 14 families (1.5-70B), exposing brittle performance and fundamental flaws in underlying assumptions
🧵👇
(1/10)
Got a brilliant research idea but not sure if it’ll hold up?
⚡ Check out ScholarEval, our latest research and live demo for literature-grounded idea evaluation.
Co-led w/ @HananeNMoussa
Advised by @hhsun1, @mbodhisattwa, @shocheen
Free access below 👇
📢 As AI becomes increasingly explored for research idea generation, how can we rigorously evaluate the ideas it generates before committing time and resources to them?
We introduce ScholarEval, a literature grounded framework for research idea evaluation across disciplines 👇!
🚨 Participants wanted! 🚨 💬 We're looking for feedback on our new multi-domain research proposal evaluator. Be first to test it using your own research ideas!
🎁 ~$25/hour task, repeatable 4 times (total $100) 📄 You must have 1+ published papers 👉 Sign up below!