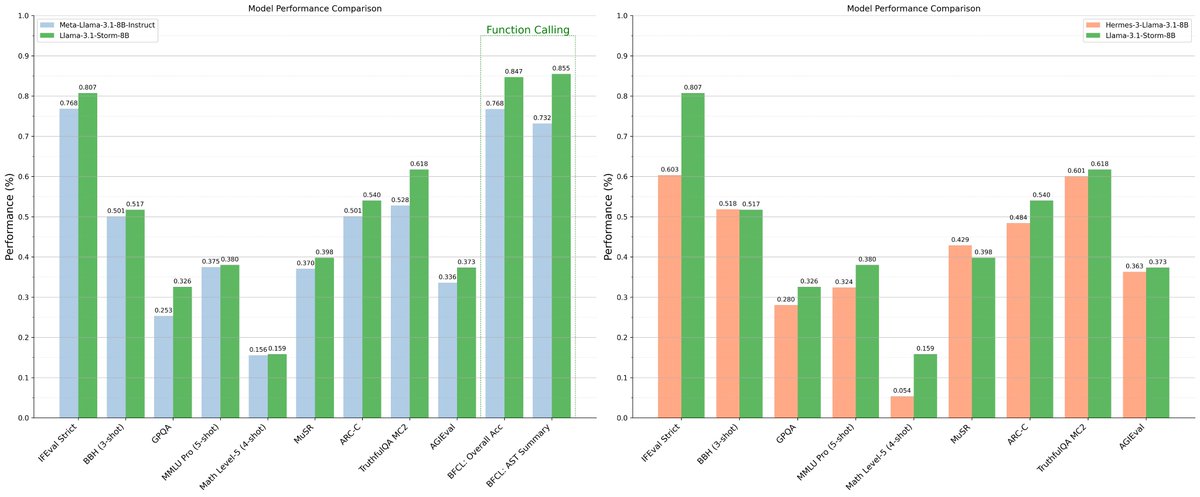
🚀 𝐋𝐥𝐚𝐦𝐚-𝟑.𝟏-𝐒𝐭𝐨𝐫𝐦-𝟖𝐁 has arrived! A new 8B parameter LLM that outperforms @Meta 𝗟𝗹𝗮𝗺𝗮-𝟯.𝟭-𝟴𝗕-𝗜𝗻𝘀𝘁𝗿𝘂𝗰𝘁 and 𝗛𝗲𝗿𝗺𝗲𝘀-𝟯-𝗟𝗹𝗮𝗺𝗮-𝟯.𝟭-𝟴𝗕 across diverse benchmarks! Our new 8B LLM pushes the boundaries of what's possible with smaller language models.
📊 𝐊𝐞𝐲 𝐒𝐭𝐫𝐞𝐧𝐠𝐭𝐡𝐬:
💻 Perfect for GPU-Poor AI developers. Build Smarter Chatbots, QA Systems, Reasoning Applications, and Agentic Workflows today! Llama-3.1 derivative, so research & commercial-friendly!
🚀 For startups building AI-powered products.
🧠 For researchers exploring methods to further push model performance.
- Start building with Llama-3.1-Storm-8B (available in BF16, FP8, and GGUF) today: https://t.co/A6hny9hCiJ
- Built on our winning recipe in NeurIPS LLM Efficiency Challenge. Learn more: https://t.co/ZlgHPQczEk
- Integration guides for @huggingface, @vLLM, and @LightningAI LitGPT: https://t.co/l9hJKS6yEV
🚀 Start Llama-3.1-Storm-8B Colab Notebook: https://t.co/3JzS2fbUer
Huge thanks to @rasbt, @marksaroufim , @_lewtun, @maximelabonne and @prateeky2806 for providing valuable feedback! We extend our deepest gratitude to @LambdaAPI for sponsoring compute for this work.
𝐋𝐥𝐚𝐦𝐚-𝟑.𝟏-𝐒𝐭𝐨𝐫𝐦-𝟖𝐁 is team Upaya’s (@akjindal53244, @pawan_r24, @ankurparikh85, @AkshitaSukh ) most valuable contribution so far towards the open-source community. If you resonate with our work and want to be a part of the journey, we're seeking both computational resources and innovative collaborators to push LLMs further!
#llm #largelanguagemodels #llama3 #huggingface #opensource
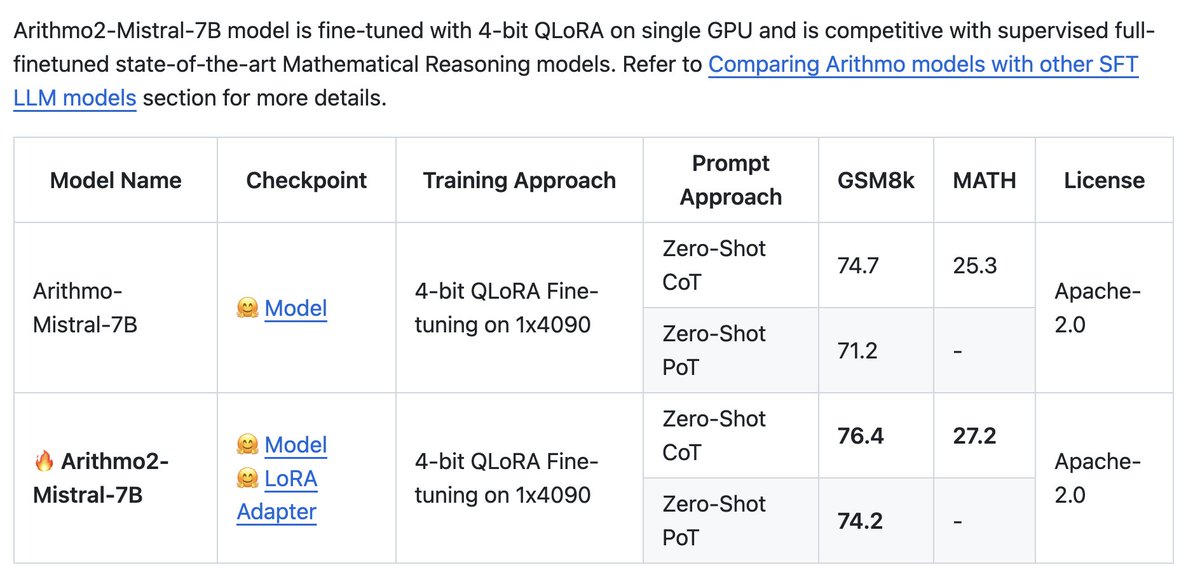
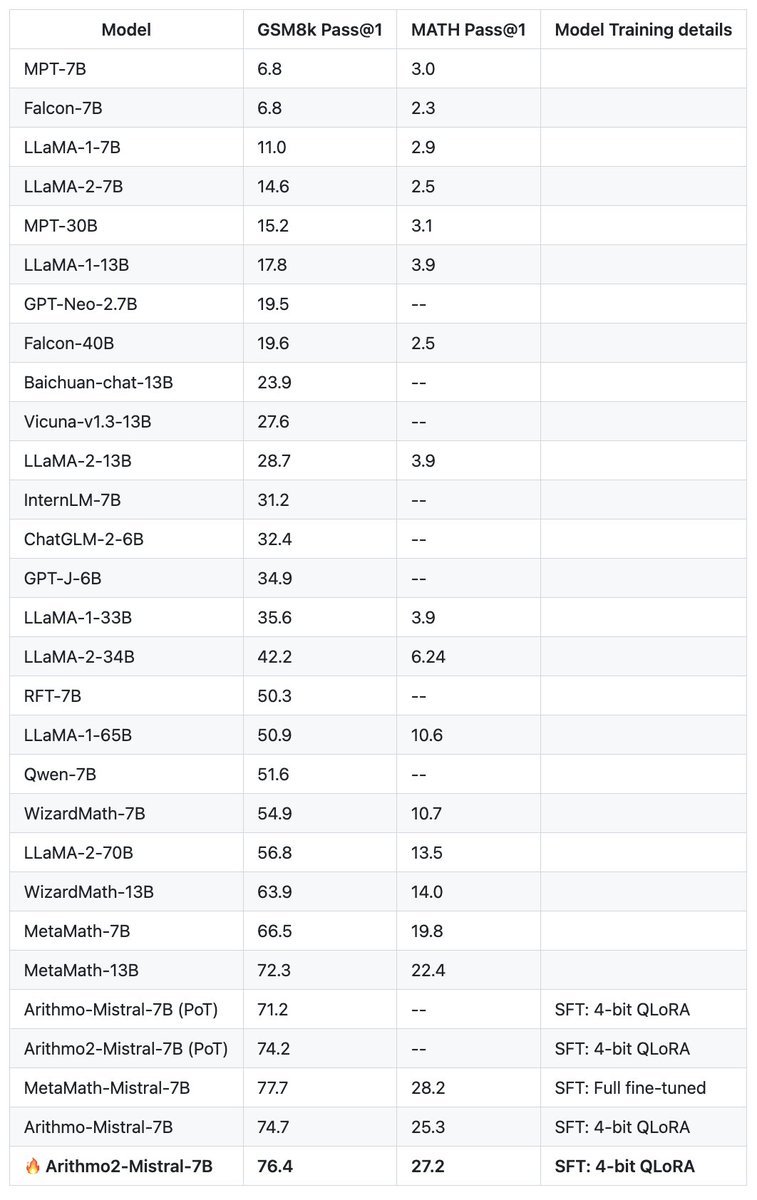
Releasing 𝗔𝗿𝗶𝘁𝗵𝗺𝗼𝟮-𝗠𝗶𝘀𝘁𝗿𝗮𝗹-𝟳𝗕 model that achieves improvement of +1.7% on GSM8K, +3.0% on GSM8K PoT, and +1.9% on MATH benchmarks, compared to previously released Arithmo-Mistral-7B model.