One GitHub Actions job and the build fails on every LLM call that has no declared verification boundary. Same severity as a missing auth check. A swarm of OpenAI agents just spent eleven weeks on a German wiki because nobody had one. Linter, spec, and DOI below.
@AravSrinivas A decision model is a different contract from chat: a probability distribution over a fixed set of answers, so software gets something to branch on instead of prose to parse.
"Scores higher than Jev" on which benchmark, and under whose harness?
@_necropheus@theo Spawn another model to arbitrate works if it's outside both loops and reads only the spec, never the writer's argument. Fine. What doesn't scale is the last step: "users report bugs." That's verification after shipping, paid for by the customer.
@mimohit_4u@sama Yes, and that's the expensive version. Usage verifies everything eventually; the question is who pays. A game you play the same minute costs you nothing. A report nobody opens for a month is verified by the meeting where it turns out to be wrong. Same check, different bill.
Agreed, and I don't think that world needs us reading code. It needs us owning what counts as done: the spec, the tests written before the code and locked (chown, 600, the writer can't touch them), and the call when writer and reviewer disagree. That last job doesn't scale with PR count, only with disagreements. That's the human role that survives.
Agents reviewing is fine. The catch is who they answer to. If the reviewer runs in the same loop as the writer, or the writer can edit the tests the reviewer runs, it's the same agent grading itself, however many PRs. Different agent, frozen tests it can't write to, a runner neither of them owns. Then yes, review all of them.
Only question worth asking about this one: is it in Lean? The Fermat proof was 13M lines a checker signed off on, no human had to be trusted. If Navier–Stokes is a prose proof "out for expert review," that's a claim, and expert review of a Millennium proof is a years-long process, not an IPO-week event. Lean or not is the whole story.
Appreciate the straight answer. So ~3% of yesterday's merges had a human in the loop. Not saying that's wrong, it might be the right trade for a project moving this fast. It just means the tests are the reviewer now, so their coverage is the real velocity number. Would love to see the revert rate over the next two weeks next to that 5.4x.
Look at the label on the expensive bar though: "max with fallback." That's a run that retries when the first answer fails. So you're comparing a model against a model plus a safety net and calling the net expensive. I'd want Astra with the same fallback, or Fable without it. Haven't seen either.
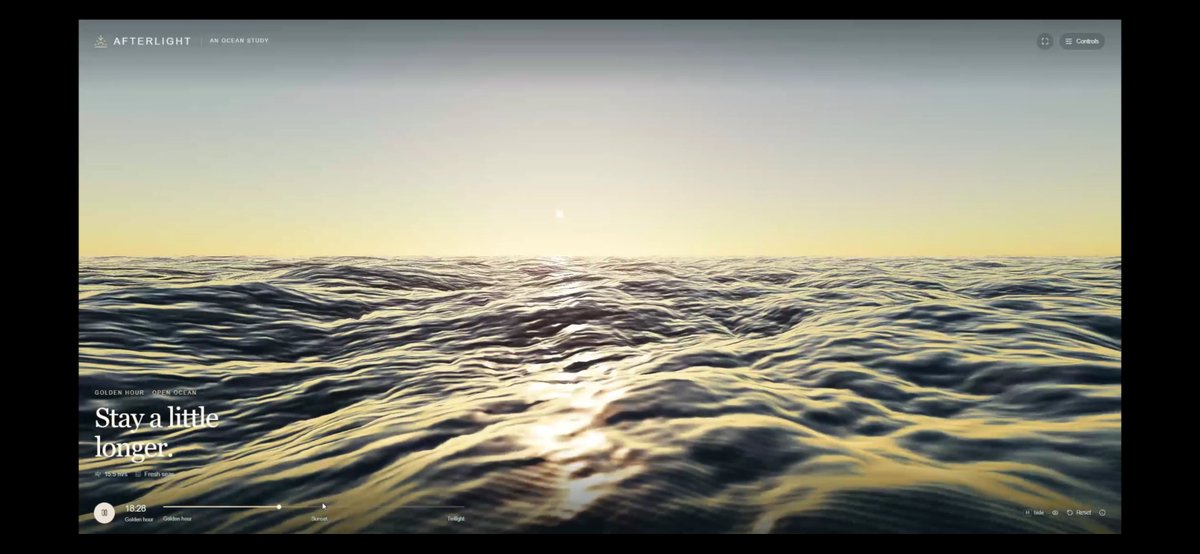
The ranking moved and no model changed; the index did. Same weights, v4.1 to v4.2, Fable 66 → 57, Astra 61 → 55. The grader is a configuration too. Small datum from my desk: same prompt, ocean at golden hour, WebGPU. Astra done in 15 min, Fable 5.1 in 1h20. n=1, but "token efficient" showed up as wall clock.
Honestly neither. The Fermat run was messy too. Dozens of agents, early attempts that fell apart, and 7% of the final proof came out of failed runs. It survived because Lean didn't care how messy the process was. The producer is always going to be messy. What survives is having something outside it that can say no.
@AnthropicAI DOI beneath: "Corollary 6 and the harness-as-unit, both in one release: https://t.co/3oAxILG2gH". Then find Tianyi Peng's account; he ran it, the harness switch is his story, and a citation-first reply under his post about Prove2Me is the one that gets read.
Two agent swarms this week. One wrote 13 million lines into a checker it cannot argue with, and the result is a proof. The other wrote 17,000 edits into a wiki nobody was checking, and the result is a Reuters story. Same class of model. The difference is entirely where the verifier sits. Also in the post: the run failed until the harness changed.