📢 New course alert 📢
I am currently teaching a course on "Language Models and Structured Data" at Institut Polytechnique de Paris.
Topics: Language Models, LoRa, Quantization, RAG, Graphs, Tabular Data, Text2SQL
Zenodo: https://t.co/wVeHwCeOlm
Buckle up because we're crashing into the new year with my annual database retrospective: License change blowbacks! @databricks vs. @SnowflakeDB gangwar! @DuckDB shotgun weddings! Buying a college quarterback with database money for your new lover! https://t.co/NnFHGElFNy
In our new @PNASNews paper, across 21 experiments with 23,000+ participants, we identify a critical distortion that shapes decisions involving tradeoffs: we find that people systematically overweight quantified information in such decisions. Paper: https://t.co/q6bgaJpEPq 🧵
We have an opening for a PhD student investigating concept drift in sensor rich environments. Come work with the awesome @vdegeler
https://t.co/simCZyuaZb
Really proud of @James_G_Nevin - a fantastic PhD student. Was fun to supervise him together with @mhlees . We know that data handling (i.e. data integration, cleaning, etc) can have lots of downstream impacts. Here's evidence.
Congratulations to Dr. @James_G_Nevin who successfully defended his PhD thesis The Ramifications of Data Handling for Computational Models. Check it out:
https://t.co/BnqVyhREpx
A collaboration with @UvA_CSL in the @UvA_IvI
co-supervised @mhlees@pgroth
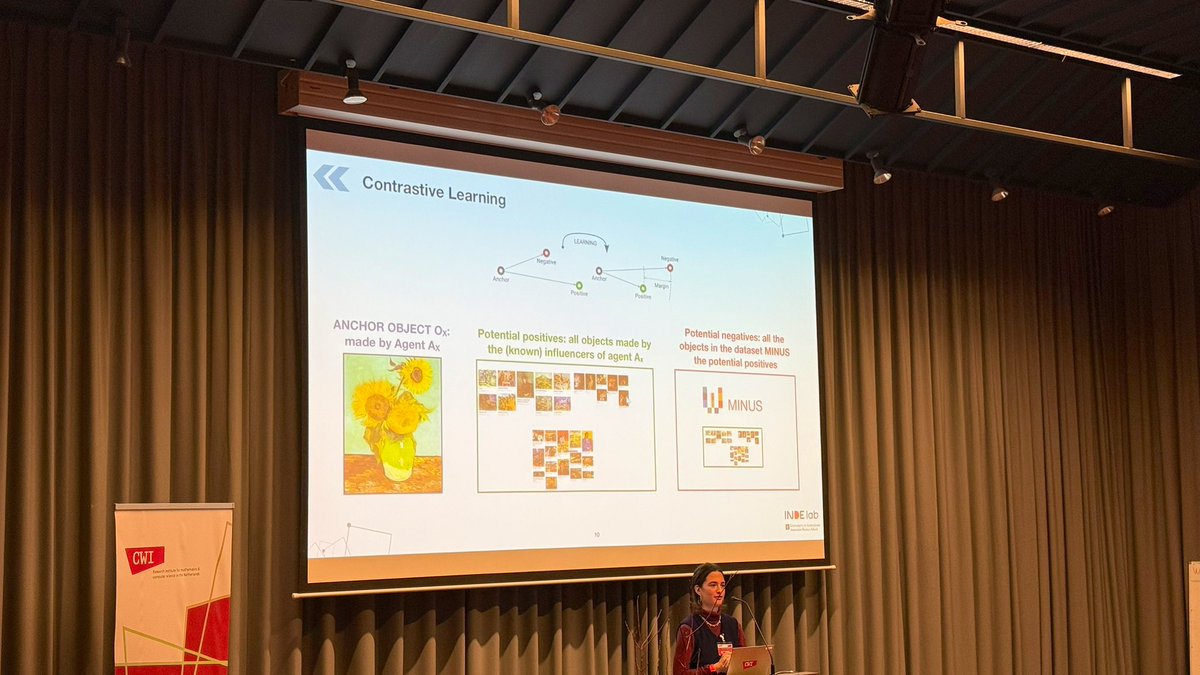
Brilliant and engaging talk by Teresa Liberatore at #EKAW2024: Influence Beyond Similarity—A Contrastive Learning Approach to Object Influence Retrieval. Insightful ideas and impactful research!
We're at #EKAW2024 this week across the street @CWInl . We have two papers: one on object influence retrieval & the other on the impact of entity linking. We also have multiple workshop contributions as well. Info at: https://t.co/o3wGU6tW6s @ekawconference
Fascinating talk by @ioanamanol on dealing with all the data models for data journalism at @iswc_conf#ISWC2024 Very cool use of gittables to retrieve names for entities (cc @MadelonHulsebos)
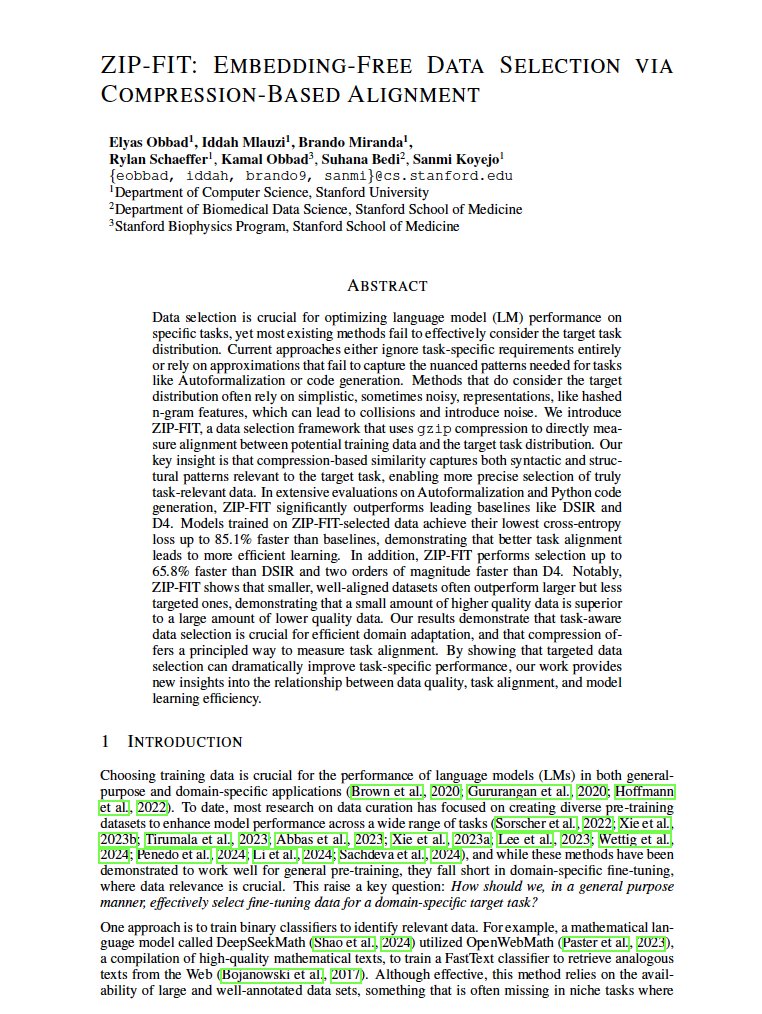
🚨 What’s the best way to select data for fine-tuning LLMs effectively?
📢Introducing ZIP-FIT—a compression-based data selection framework that outperforms leading baselines, achieving up to 85% faster convergence in cross-entropy loss, and selects data up to 65% faster.
🧵1/8