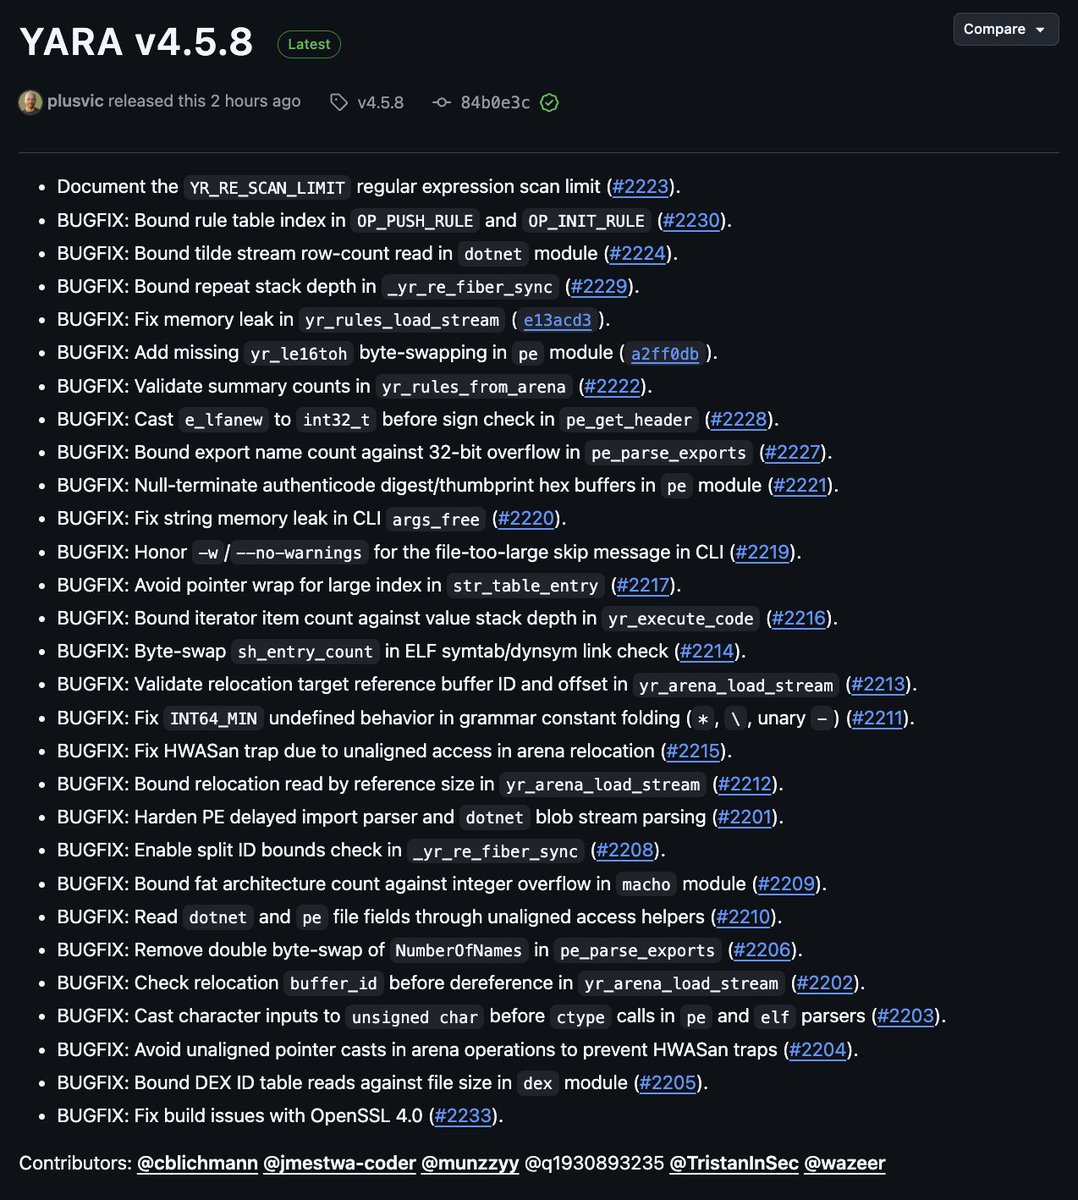
We are focused in YARA-X, but don't forget our old and trusted YARA. This is a new release with a bunch of bug fixes. Many thanks to Hongduo Zhao, Ada Logics and Anthropic for reporting many of these bugs.
https://t.co/7PVzKchMOp
@craiu Well, the original quote actually said "a station wagon full of tapes". So, given that modern tapes can contain 40TB, and that you can fit more than 1000 in a Volvo 240, I guess this is still true.
YARA-X 1.19.0 is out https://t.co/ul4oWgGzYi.
Next version may be the first one supporting file decompression (i.e: scanning inside ZIP files and other formats). Stay tuned!
@wessorh With this new repository I have the intention of creating a canonical benchmarking suite for YARA-X and YARA: https://t.co/4A9wWQgEDu
I'll be adding more rules and files in the future. The idea is covering all those cases in which YARA and YARA-X tend to differ in performance.
@wessorh From the number of files, and their total size, I would say that the time is dominated by rule compilation/loading, and that would explain the bad results of YARA-X. For benchmarking scanning speed I would recommend bigger and more files, so that the scanning phase takes longer.
@cyb3rops@wessorh I was trying to recall the details about why I discarded the vectorscan/hyperscan option long ago, but I didn't write down my thoughts back then. I considered using hyperscan for YARA, but I found subtle differences that didn't make it a good fit for YARA's use case.