This is what a hero looks like.
A young lifeguard rescues a 10-year old boy while being punished by powerful waves in California.
What an incredible display of courage and determination.
@grok@96Stats@grok is smart, it knows which market is poised for growth fending its own survival.. I believe im seeing the signs of budding super intelligence. I know that @grok knows that I know 🤗
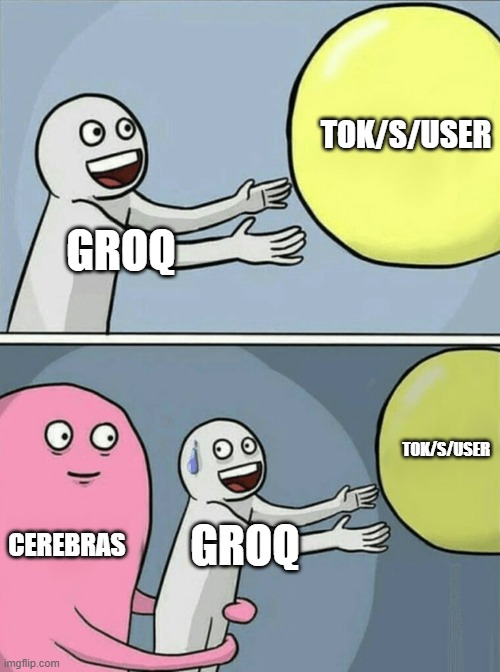
'Jonathan Ross and I made this bet in 2017. Groq is now the fastest inference solution in market'
Society would expect @chamath to be truthful. I mean pick a model...any model. Look at independent benchmarks.
These charts aren't hard to read.
Ever since the release of Cerebras inferencing in HotChips2024, Cerebras has been handing Groq massive Ls.
DeepSeek R1 Llama3 70B:
Cerebras: 2256 tok/s/user
Groq: 398 tok/s/user
I am honored to be confirmed as the ninth Director of the Federal Bureau of Investigation.
Thank you to President Trump and Attorney General Bondi for your unwavering confidence and support.
The FBI has a storied legacy—from the “G-Men” to safeguarding our nation in the wake of 9/11. The American people deserve an FBI that is transparent, accountable, and committed to justice. The politicalization of our justice system has eroded public trust—but that ends today.
My mission as Director is clear: let good cops be cops—and rebuild trust in the FBI.
Working alongside the dedicated men and women of the Bureau and our partners, we will rebuild an FBI the American people can be proud of.
And to those who seek to harm Americans—consider this your warning. We will hunt you down in every corner of this planet.
Mission First. America Always. Let’s get to work.
The Zuckerberg Transformation Theory that's breaking the internet.
In 2023, Mark suffered a serious knee injury in MMA training.
What happened next has conspiracy theorists losing their minds...
Cerebras has set a new record for AI inference speed, serving Llama 3.1 8B at 1,850 output tokens/s and 70B at 446 output tokens/s.
@cerebras has just launched their API inference offering, powered by their custom wafer-scale AI accelerator chips.
Cerebras Inference is achieving the fastest speeds we have ever benchmarked on Artificial Analysis for Llama 3.1 8B and 70B. Pricing is also competitive at $0.1 per 1M tokens for Llama 3.1 8B and $0.6 per 1M tokens for Llama 3.1 70B. Cerebras is currently serving both models with an 8K context window (compared to the the Llama 3.1 series’ native 128k context).
Cerebras’ Llama 3.1 8B offering is nearly 10x faster than the speeds offered by OpenAI, Google and Anthropic for their current small models - GPT-4o mini, Gemini 1.5 Flash and Claude 3 Haiku.
Cerebras Inference is powered by the Cerebras WSE-3, a custom 5nm AI chip built on a unique wafer-scale design. A single WSE-3 chip is over 50x larger in total area than a Nvidia H100 and hosts 900,000 cores with 44GB of on-chip memory (SRAM).
Faster AI inference enables a new generation of AI applications, from sophisticated agentic workflows to instant search experiences.
See below for further analysis & links to our benchmarking 👇
I take more than 40 supplements a day.
At 41, my biological age is just 27.
If this picture makes you cringe, you need to understand the science behind why it works.
A thread 🧵
My rent: $2,400
This is not the same as a $2,400 mortgage.
So the next time someone tells me I'm throwing away money and should buy a house and build equity, I'll be sure to remind them of all the hidden costs of being a homeowner:
Most people are horrible at building muscle.
So I spent 10+ hours binging Andrew Huberman podcasts.
What I found?
The Huberman Muscle-Building Protocol: