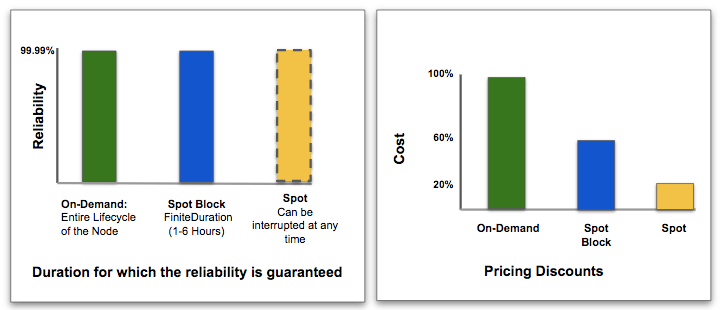
Our latest benchmark results quantify what we have known for long - @prestoQubole's spot interruption handling can save upto 60% on cloud costs without sacrificing reliability! This is on top of savings from @prestoqubole1's workload-aware autoscaling!!
https://t.co/lHpn3xG9JB
Spot nodes on AWS (and preemptible VMs on GCP) are a great way to reduce your TCO for big data workloads. However, loss of a spot node can cause Presto queries to fail. Our blog on how @prestoqubole1 handles spot losses without sacrificing reliability: https://t.co/uCHRTcoLuI
New website. Personal profile updated. First live demo with prospect. Strong thumbs up and 'we wanted it yesterday' sentiment. Not a bad week: https://t.co/cN6kq5AjCq
Wonderful to pair with old colleague @lalitindoria on the @clearfeedai journey. And to mother nature for a blacktop so i still fit in with this Gen-Z crowd.
Blog post by Harmandeep Singh on recent improvements to better support Hive transactional tables in Presto:
https://t.co/nrUu1fIEwo
#prestosql#presto#prestodb@ApacheHive
Benchmarketing, the practice of using benchmarks for marketing, is bad. Consumers should run their own benchmarks and ideally open-source them instead of relying on a biased comparison.
https://t.co/fOXHRVostK
#database#benchmark#prestosql#prestodb#opensource#presto
#Presto is the go to #query engine for interactive and #reporting use cases, due to its high performance & ability to join unstructured & structured #data in seconds. Learn how @prestoqubole1 gives you best-in-class performance to while reducing #tco https://t.co/FipWvn5KRQ
How to save on cloud costs: @awscloud Spot Block Instances combined with Qubole’s Open Data Lake Platform help customers run their data #analytics and #ML use cases without interruption: https://t.co/0rERdJPqno #cloudonomics
Here’s a tip for lowering your cloud #TCO: Columnar format reduces storage costs and cuts down on query run time by limiting processing to needed columns only. Compression rates improve, and filters become more effective. Read more:
https://t.co/eCoML0chJH #cloudonomics
Amazing to see one of @qubole customers use @prestoqubole1 & @LookerData to analyze usage data from Qubole Cost Explorer (https://t.co/QZKOHep6PG) to continuously drive their @awscloud spot % and m/c utilization higher. So many takeaways here under this pic. 1/n
Great blog post from Raunaq Morarka (https://t.co/rjCLOKR3kb) from @qubole and @sopel39 from @starburstdata on dynamic partition pruning that recently got merged in #presto 335!
Presto 335 is released! This version adds variable-precision TIMESTAMP type, dynamic partition pruning, aggregation pushdown into connectors, and much more! See the full list: https://t.co/1RJruiY7SU #presto#prestosql#prestodb
Super excited to see this - great job Raunaq Morarka (https://t.co/rjCLOKR3kb)! This has been in the works at @qubole for a long time and has required a lot of perseverance and dedication from him (and @amargoor before him)!
Dynamic partition pruning coming soon to Presto! Massive performance improvement for complex queries over partitioned Hive data. I'm excited to see this feature come to fruition. Great job, Raunaq Morarka!
https://t.co/Q2CYPqTuUb
#presto#prestosql#prestodb@prestoqubole1
Great blog post by Shubham Tagra on the recent improvements in Presto to support Hive ACID transactional tables: https://t.co/7NSjkYFriZ
#prestosql#presto#prestodb