Hello world.
Introducing Proofpress.
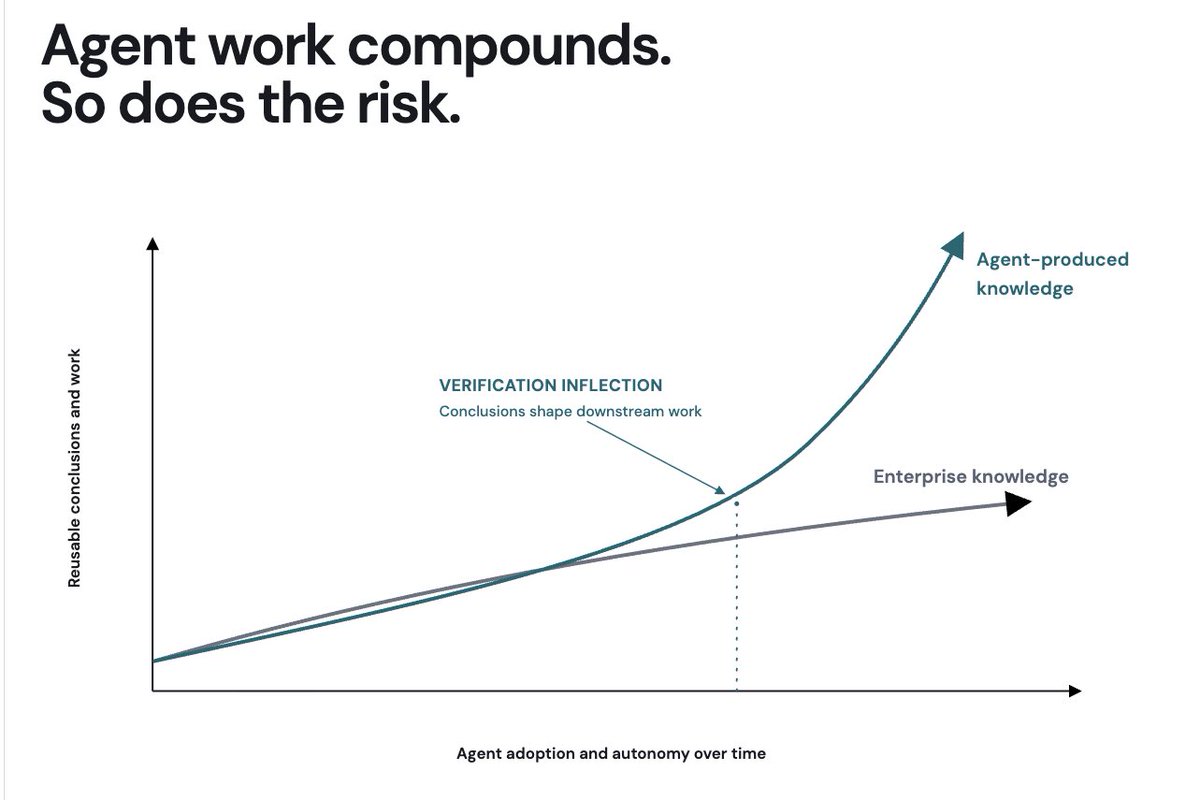
Over the next 1–2 years, agents will produce ~1,000× more research, analysis, artifacts, and decisions. Agent work compounds — so does the skepticism. Verification becomes the bottleneck.
The question stops being whether agents can do the work. It becomes whether organizations can trust, understand, and safely build on what they produce.
Proofpress turns agent output into verified knowledge worth building on — so every next agent or human has a trusted starting point.
this is music to my ears!! we've been building @proofpressai on the exact thesis: agent-produced findings/knowledge/artifacts should be captured, verified, and governed, with evidence, authority, scope.
This verified, system of record (or knowledge layer) should sit next to, not inside, the capability layer, to maximize efficacy and safety.
These are some very important observations from Satya.
As models and harnesses commoditize, intent, verification and evidence will gate how quickly SI permeates enterprises and businesses.
Importantly, you need to implement systems that separate who does the work from those who govern, measure and sign off on it.
This is a new kind of “harness” that will emerge over the next few years. It may become a new system of record over time. One whose entire role is to track “change” and map it back to SOPs, policies, laws and the like.
Ruishi Chen, Stanford PhD, and I are hosting a seminar at Stanford next Wed talking about frontier knowledge for AI. Would love to see you there!!
thx for our co-host
@gmi_cloud@nicoleegong
https://t.co/stI1c82G4D
Agents change. Make the work survive.
We’re Only Then Labs. We’re building Proofpress to help research teams carry findings, evidence, and review decisions across agents and sessions.
Explore the recorded demo. Bring us a handoff worth fixing.
https://t.co/NWpotmCIIs
An AI breakthrough should survive the AI that made it.
Change the model. Replace the agent. Bring in a new team.
The evidence should still be there. The failed experiments should still count. A rejected claim shouldn’t quietly become a fact again.
That’s the future we’re building toward at Only Then Labs.
Our first product is @proofpressai: helping research teams carry knowledge between agents with its evidence, decisions, and history attached.
The next intelligence should be able to pick up the work, challenge it, and take it further.
Imagine a research effort that lasts ten years, across thousands of agents and generations of models. Every handoff preserves what’s supported—and what could overturn it.
That’s a future I want to spend my life building.
We’re early. There are hard questions left. You can help us answer them.
If you build agents, run a research team, or have watched weeks of work disappear into a broken handoff, talk to me.
Bring us the problem you keep having to explain from scratch.
Let’s build something the next intelligence can inherit.
Your company should be able to change models without losing its mind.
What it knows, why it believes it, and who authorized its use should survive every handoff.
That’s the continuity we’re building toward. 🦾
Every serious company keeps financial books. Not because money can’t be tracked in a spreadsheet or Apple Notes, but because the company needs to know where every material dollar came from, what authorized its use, where it went, and which decisions were made from those numbers.
As agents produce more of the organization’s research and decisions, companies will need the same discipline for intelligence. They need to know where a consequential claim came from, what evidence supports it, who authorized its reuse, whether it is still current, and what later work was built on it.
Proofpress is that system of record: the Intelligence Ledger.
introducing JevGraph — an open-source pipeline to turn documents into evidence-backed knowledge graphs building on @llama_index 's DocJev and Jev @typesafeai
introducing JevArena: an open-source arena for testing Jev against other AI judges.
ask a real question. add the possible answers. pick any OpenRouter model. vote blind, then reveal the models, judgment, latency, and cost.
LLM judges are overkill when the job is a bounded decision.
We just put Jev @typesafeai into production in Proofpress via Vercel AI Gateway @vercel.
First canary: 914ms end-to-end, 3,016 input tokens, ~$0.00012 at Jev’s listed rate!!!
Fast enough and cheap enough to make evidence review a default.
Amid fears about AI security and humanity’s future, I keep thinking about how lucky we are to be here.
We stand on generations of human curiosity, courage, and care. What a privilege to inherit their work and build on it at this moment in human history.
Let’s be humble, grateful, and careful with what we pass on.
@HrshitKunwar@tallmetommy 100% and the workspace owner can configure another lm as a judge with organizational criteria and policy as a second line of defense before human review
An agent’s mistake shouldn’t become your company’s institutional memory.
We’re building Only Then Labs. Our first product is Proofpress.
One agent produces a finding. Another picks it up and builds on it. We want the evidence, the limits, and the human approval to survive that handoff.
@proofpressai makes those claims reviewable before they become reusable knowledge. The code is public, and our team is growing across engineering, research, and product.
We’re looking for three teams using multiple agents on the same project to try it on a real workflow.
Bring us a handoff that keeps breaking. Let’s see what holds up. 🦾
Try Proofpress: https://t.co/gxtSzPn6f6
Git solved a universal problem: different codebases can share a common revision model.
Agent evidence has the same problem.
Today we open-sourced a content-addressed evidence adapter for Proofpress.
Any source system can emit a bounded, reviewable evidence receipt:
• source URI + exact content digest
• a small human-readable observation
• a typed locator
• adapter configuration digest
Git, spreadsheets, documents, databases, warehouses, and SaaS systems do not need to share one semantic model. They only need to produce a verifiable projection into the same evidence → claim → review → reuse path.
Our first typed locator is spreadsheet_cell: bind an exact workbook revision and cell-level change without uploading the workbook or raw agent traces.
This does not prove a claim true or approve it. It creates a reproducible boundary for deciding whether a claim should be trusted downstream.
Open source: https://t.co/OmK4L6nXZZ
AGI has arrived. Now comes the inheritance problem.
What state is allowed to become truth?
Who had authority to change it?
What survives the handoff?
What is the next intelligence actually permitted to trust and act on?
A signature proves who signed. Provenance proves what happened. Neither proves the transition was legitimate.
We’ve been building the admission, authority, continuity, revocation and witness layer for exactly this.
400K GPUs can scale intelligence. They cannot scale legitimate authority.
Hello world.
Introducing Proofpress.
Over the next 1–2 years, agents will produce ~1,000× more research, analysis, artifacts, and decisions. Agent work compounds — so does the skepticism. Verification becomes the bottleneck.
The question stops being whether agents can do the work. It becomes whether organizations can trust, understand, and safely build on what they produce.
Proofpress turns agent output into verified knowledge worth building on — so every next agent or human has a trusted starting point.