🚨BREAKING: Jensen Huang just EXPOSED Dario and Altman’s "Rogue AI" grift to avoid getting sued into oblivion under EXISTING law
“Don't let this doomsday narrative cause somebody to relieve them of the laws that currently exist.
Go and read between the lines. They're actually not asking for more laws; they're asking to be relieved of the laws we do have.”
ABSOLUTE TRUTH NUKE
We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: https://t.co/OGyPb7yaYt
Spec-driven development is not one thing. There are three levels.
Birgitta Böckeler from Thoughtworks describes them in her article:
Spec-first: write a spec, generate the code, throw the spec away.
Spec-anchored: the spec stays in the repository and evolves with the code.
Spec-as-source: humans only edit the spec, the code is regenerated.
Where are the tools?
Kiro and spec-kit are spec-first.
BMad is spec-first with good planning documents on top.
OpenSpec is spec-anchored, with delta specs that merge into the main specs.
And the AI Unified Process? Also spec-anchored.
Requirements, use case specifications, and the entity model live next to the code for the whole life of the system. Tests are linked to use cases with @UseCase. Change the spec first, then the agent changes the code.
I rarely type code myself anymore. So is this level 3? No, and on purpose. The code is not regenerated, the agent evolves it. That is the only way brownfield works. Nobody regenerates a 15-year-old ERP from a spec.
You get most of the productivity of level 3 without depending on a non-deterministic compiler. And you keep a team that understands its own system.
Full article: https://t.co/W8y1zxThXt
#SpecDrivenDevelopment #AIUnifiedProcess #RequirementsEngineering #SoftwareArchitecture
We built the world's most advanced program reverse-engineering system. It's model-independent and demonstrated improved performance for every frontier model we tested on long-horizon software tasks by giving agents an independent definition of done.
New Factory research:
In 1852 aluminium cost twice as much as gold.
Then the price fell over 99.9%. Yet it built one of the largest materials markets on earth.
What it says about AI tokens: https://t.co/5Y04wrz8mj
This blog post was written for those who may be curious to know what an agent harness is, but don’t, and might not know where to start. Read the full post here
https://t.co/pUnUnQvEHJ
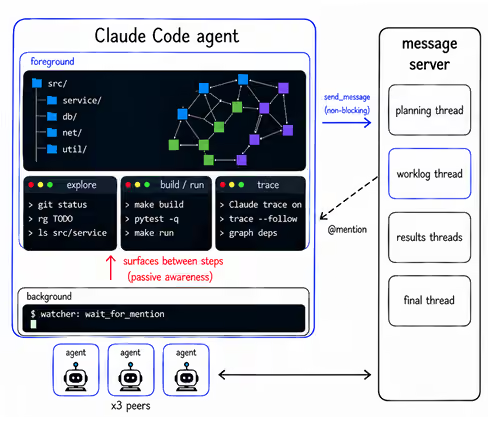
Running multiple AI agents in parallel creates a communication bottleneck, where models can't share their findings mid-step and need to wait at specific steps to coordinate and communicate.
AgentRadio solves this communication bottleneck with a lightweight but efficient framework that is compatible with existing agentic harnesses such as Claude Code and Codex CLI. At the heart of AgentRadio are three primitives:
- create_thread (create a new message thread between agents)
- send_message (send message to thread)
- wait_for_mention (wait for message on thread)
The only requirement is for the target harness to support background processes for the wait_for_mention primitive to enable “passive awareness,” where agents can continue their primary tasks while passing messages and updating their knowledge in the background.
In practice, this means that, for example, if an agent makes an important discovery in the middle of one of the steps, it can communicate the finding to other agents in the middle of the current steps and the other agents can update their planning accordingly, without waiting for specific milestones.
In experiments, with equal compute budgets, AgentRadio beats single agents as well as multi-agent systems without passive awareness on complex tasks such as codebase understanding (SWE-Atlas QnA) where agents need to do exploration by not only reading the code but also running tests and using tools.
Reading the code is purely ego thing.
If you have strict guidelines and enforce code architecture - SOTA models will produce code that adheres to those rules (ie "Best practices")
AI will write tests, most of you will never.
AI can review itself, find repetitions and issues.
In rare cases AI would over-engineer solution, that's why planning mode is so important.
It's also concert of
"there's a SKILL for that"
I don't oneshot.
I iterate. Plan. Review. Document. Build. Test. Review. Test. Audit.
All are skills, workflows, mostly automated.
Reading the code becomes informative practice. Because we're at the point of 95+% deterministic outputs.
Sufficient for pretty much all of your projects.
A sliver subset of development work with unpopular languages or problems models never seen in training...
But it ain't you, bruh. Most of devs on here are not working with that. It's truly rare.
When using agents, ensure that everything that can be deterministic, is done with a deterministic tool. Don't try to get the poor agents to follow a deterministic process.
Announcing Discovery Loop!
I am very excited to announce that, along with my longtime friends and collaborators @Sanjay_Ghemawat, @OriolVinyalsML and @quocleix, we are founding Discovery Loop (@DiscoLoopAI), a Public Benefit Corporation whose mission is to automate machine learning, science, and engineering to accelerate discoveries and progress. The four of us have worked together for 14 to 30 years, and have helped build some of the world’s most used products, infrastructure and AI models, and we’re excited to turn our attention to this ambitious endeavor.
♾
Learn more at: https://t.co/Rv3LMdLluK