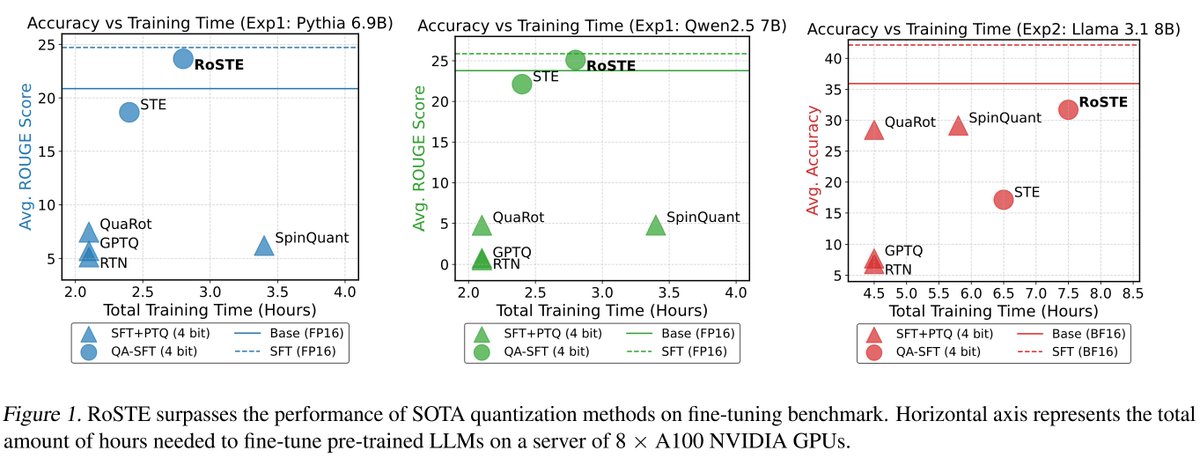
RoSTE: An Efficient Quantization-Aware Supervised Fine-Tuning Approach for Large Language Models (https://t.co/2h4RSHN7hP) with @quanwei0 & @yauchungyiu on Wed 16 Jul 11am-1:30pm East Hall (3/3).
Interesting project with @willcb@quanwei0 @Mingyi552237 and other collaborators. We show that turn-level credit assignment indeed helps a lot for multi-turn tasks.
Multi-turn task is the setting where we may think bringing MDP and other classic RL thoughts back to the table.
new paper with @ZengSiliang and other collaborators about some of our multi-turn findings from the past couple months :)
lots of experiments about the pros and cons of structured rewards and credit assignment, particularly relevant when doing tool-use RL with 7B models
Our new quantization-aware training algorithm RoSTE can fine-tune quantized LLMs and break state-of-the-art benchmark accuracy on 4-bits Pythia, Qwen and Llama models! Thank you @quanwei0 for the great effort👏
Paper: https://t.co/ztc3jUjh7u
Code: https://t.co/UZpq9nyBUk
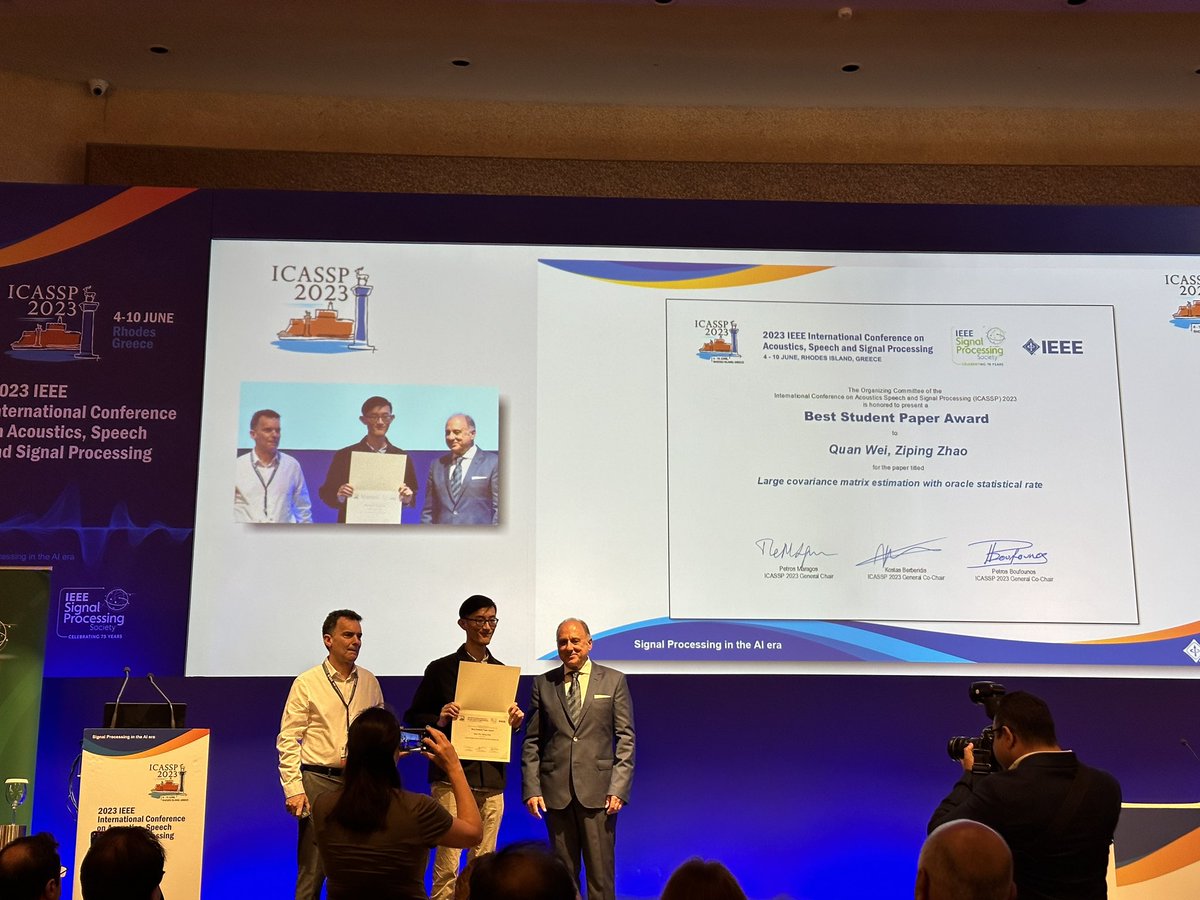
I am honored to receive the Best Student Paper Award at #ICASSP2023 with Prof. Ziping Zhao for our paper "Large covariance matrix estimation with oracle statistical rate"!