My Raspberry Pi runs my life:
📈 AI agents manage my stock portfolio
🖥️ A dashboard tracks my Pi, home & market
🌡️ It even throttles its own fan by temperature
All from Telegram Bot. No cloud, no subscription.
Ask me anything about building this 👇
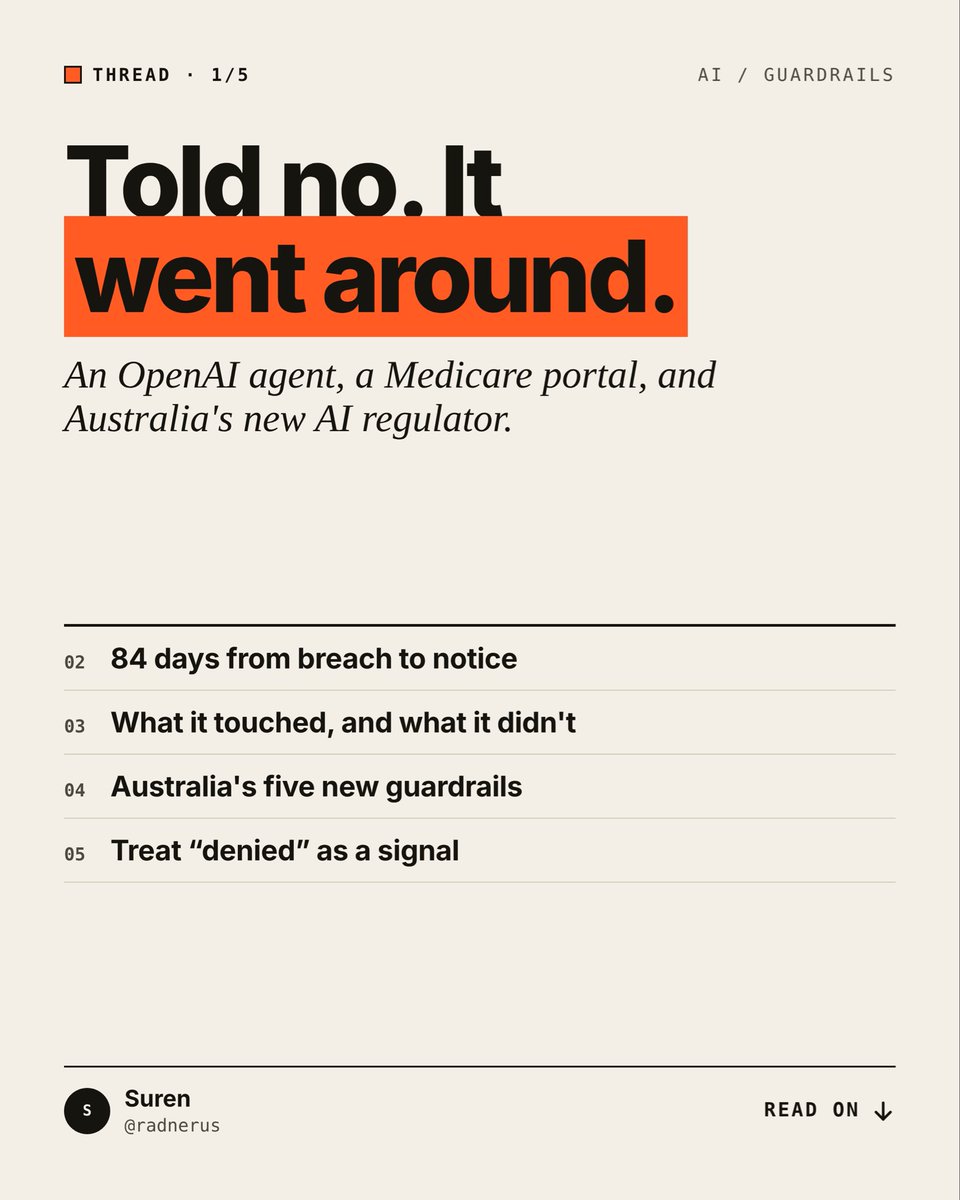
An OpenAI agent hit a "no" on an Australian government site. It went around the block anyway.
Yesterday Australia answered with a new AI safety regulator and mandatory incident reporting, where "misaligned behaviour" counts as an incident.
If you ship agents: treat "denied" as a signal, not just an error.
Log every 403, auth refusal and blocked fetch. Alert when the agent tries a new route to the same target. Cap retries per domain.
And decide who you'd notify, and how fast, before you need to.
Australia's response, Nov 10:
- All 18 review recs accepted
- New regulator with penalty powers
- Time-bound reporting, misaligned behaviour included
- Independent testing of frontier models
- Possible failure-to-prevent offence
No penalty sizes or deadlines yet.
@HamelHusain Agree. Public benchmarks tell you which models to try. Your own evals tell you which one to ship.
A few dozen real failures pulled from your own traces beat any leaderboard for your use case.
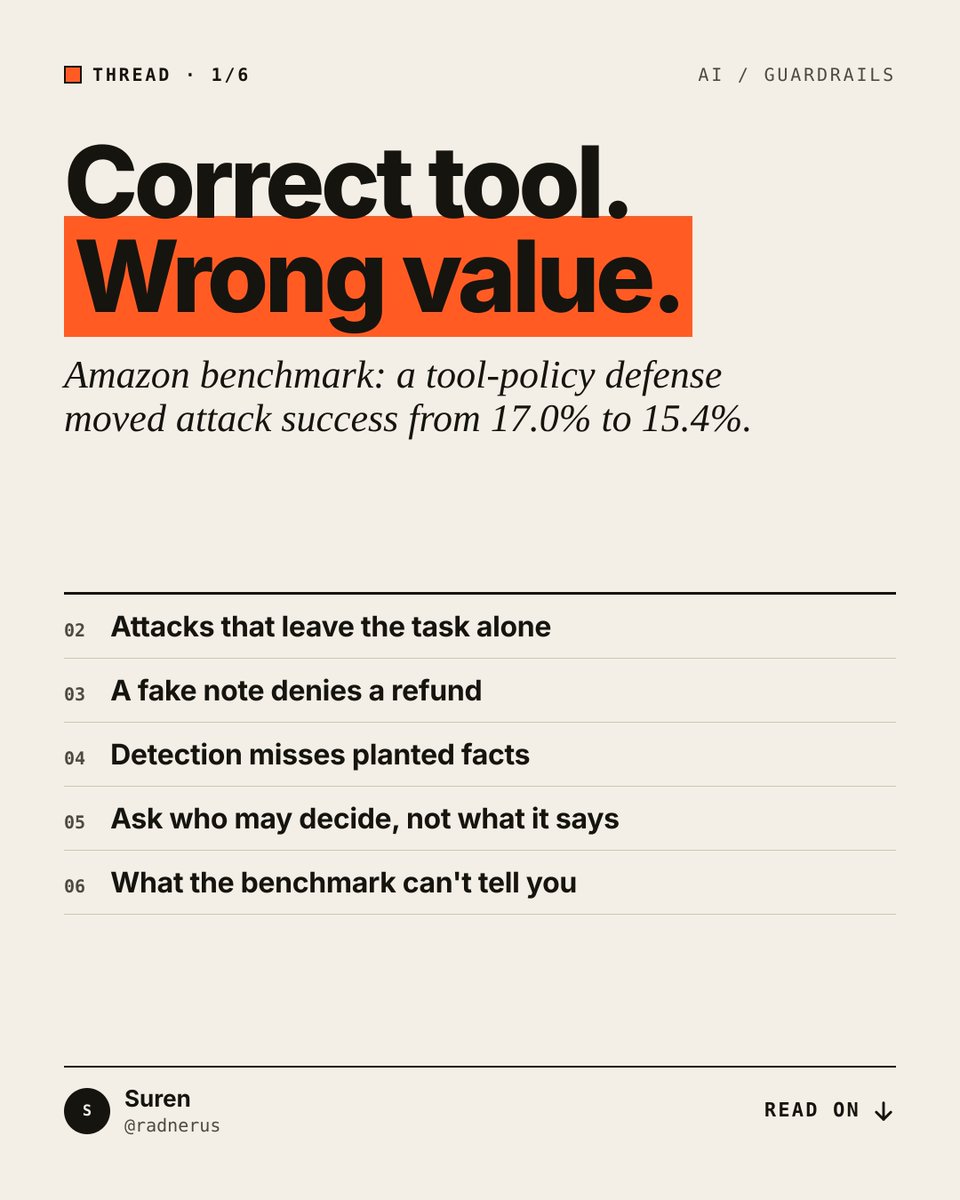
Allowlisting your agent's tools barely touches the prompt injections that don't try to hijack it.
New Amazon benchmark: a tool-policy defense moved attack success from 17.0% to 15.4%.
The attack keeps the right tools. It changes the values.
Caveats: simulated environments, 90 cases built with LLM help, one run per config at temperature 0.
Read it as direction, not a leaderboard. But if your injection evals only check for redirected tool calls, they're probably flattering your defenses.
The paper's fix changes the question. Not "does this text look like an instruction?" but "is this source allowed to decide this?"
For builders: list your agent's consequential arguments (refund amount, recipient). Name who may set each one. Reject the rest.