Working as a software engineer with an allergy to nonsense is not easy.
That's why I quit employment to work directly with clients who want to solve their problem or build something together.
If you need an engineer who sees the full picture, see my offer.
It hasn't given me any clients yet, but there are reasons I continue this experiment:
- X Ads are very cheap in Europe.
- Deciding to contact me may take time. Even if it doesn't give immediate results, it increases reach, which can lead to clients in the future. I have no data to support this, there is a large random part.
- I got one email about concrete work (and got ghosted, or they need time), and it's probably from X Ads.
You can write me an email or private message here, so I can share what else I tried with no success.
Working as a software engineer with an allergy to nonsense is not easy.
That's why I quit employment to work directly with clients who want to solve their problem or build something together.
If you need an engineer who sees the full picture, see my offer.
A lot was written about feedback. One past employer even provided us a training about the art of giving and receiving feedback.
For those like me who aim to use feedback to improve their products or themselves, it's worth being aware of its traps. I call it "junk feedback" and nobody, including dedicated training, warned me.
Here, I share some situations from my experience when we can receive junk feedback instead of real one.
Before taking action, it's important to understand the context of the feedback that was given. Then, even a junk one can provide valuable information.
- "We were impressed with your experience, but..." you were rejected. The classic one every job hunter knows. But even honest and more concrete feedback that seems real can be junk. When two recruiters gave me opposite advice, I become more careful. Both were right, both advised how to perform better on THEIR interviews.
- Most companies have some kind of evaluation process for their employers. Don't mistake "evaluation" with "feedback". When our co-worker says something about us anonymously, we don't know the context. This type of information can be more or less actionable depending on how exactly it's done.
- Public evaluation. Imagine a whole team meeting when everyone says their opinion about the current team lead and about new candidates. Everyone in the same room. Nothing but praise.
- Asking friends and family about a product we built is an obvious trap. But even feedback given by strangers can be junk. If we ask someone who is not in our target group, we can receive a bunch of ideas on how to solve their problems, which are not related to our product. This can be useful, but not for building a product to satisfy everyone.
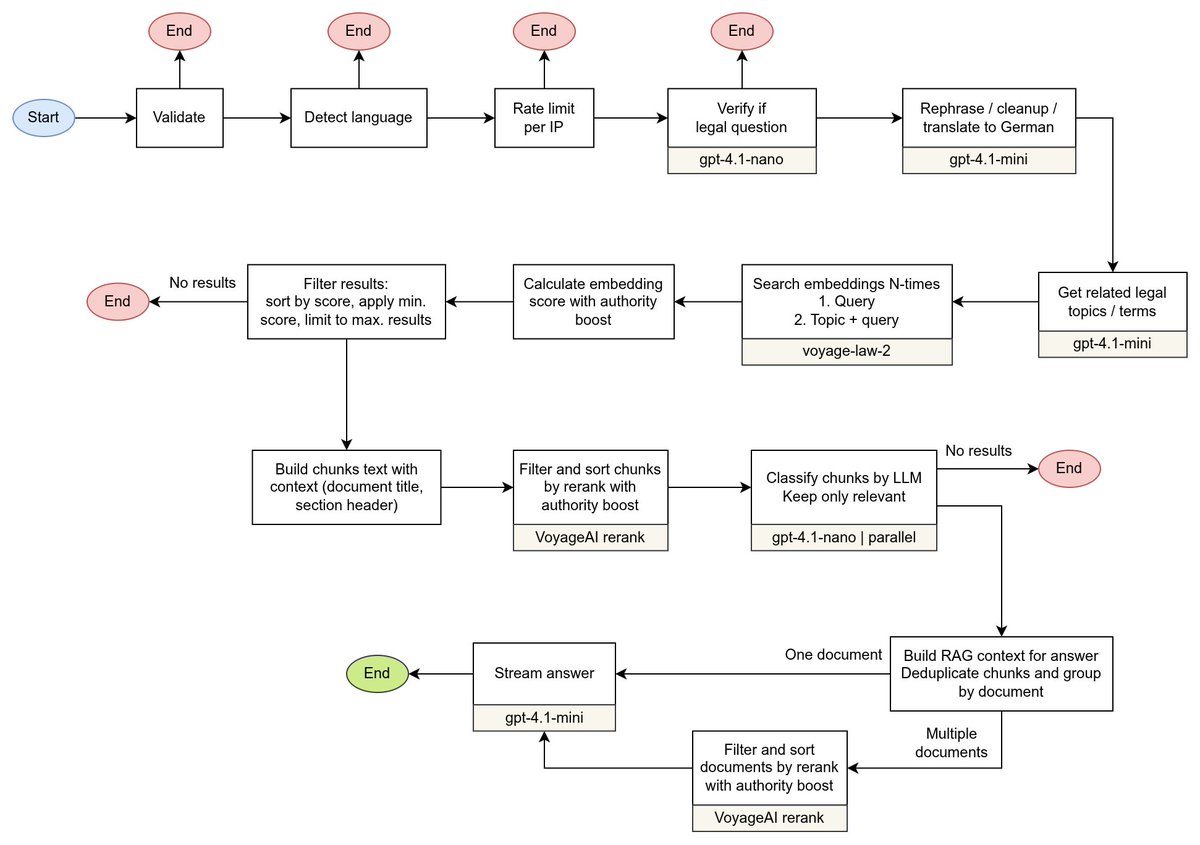
@themahis This is basically just retrieval. The final answer is only a paraphrasing of selected legal provisions in the context of the user's question. LLM is strictly instructed to not invent anything else.
Last year I wanted to prove that a cheap AI solution in the legal domain is possible.
Rechtina is a real production system using smaller, cost-efficient models to answer questions based on Austrian federal law.
One of the solutions I shared as a case study. Link in a comment.
I built a tool to scan an entire codebase for similar logic implemented in different ways.
It groups those fragments into clusters, making it easier to find refactoring opportunities that would otherwise stay hidden.
I built a tool to help review AI-generated code.
It checks Git changes against the rest of the codebase and finds cases where the same logic has already been implemented differently somewhere else.
You can reduce token usage in AI coding tools not only with clever prompts.
I built a tool that reports clusters of similar code, which agents can use directly. They don't need to spend tokens on finding them themselves or load unnecessary data into context.
I built a tool to scan an entire codebase for similar logic implemented in different ways.
It groups those fragments into clusters, making it easier to find refactoring opportunities that would otherwise stay hidden.
You can reduce token usage in AI coding tools not only with clever prompts.
I built a tool that reports clusters of similar code, which agents can use directly. They don't need to spend tokens on finding them themselves or load unnecessary data into context.
I tested it on multiple open-source projects covering all supported languages, and in my opinion, results are definitely useful and practical. But not every project benefits equally. A few examples are described here: https://t.co/g2hzx1QL4e
Since yesterday's release, it also extracts code blocks inside control-flow syntax like conditional, loop, exception handling. Details in README: https://t.co/Ihid13TF90
I built a tool to scan an entire codebase for similar logic implemented in different ways.
It groups those fragments into clusters, making it easier to find refactoring opportunities that would otherwise stay hidden.
@Heyyo_leo We are talking about using embedding models to find similar code. The coding agent receives the exact location instead of looking for this itself. RAG is the closest one.
You can reduce token usage in AI coding tools not only with clever prompts.
I built a tool that reports clusters of similar code, which agents can use directly. They don't need to spend tokens on finding them themselves or load unnecessary data into context.
@voigt_peter How does it find similar implementations that are written differently? Slopo uses embedding models. We can also compare costs. Embedding models are extremely cheap compared to LLMs.
I built Slopo and integrated it with AI coding agents.
It finds duplicated implementations that agents miss. Then agents guide a developer to help with decisions and refactoring.
Code duplication detector for the hardest-to-detect clones.
Based on embedding models for finding similar code. The models were benchmarked to get the most out of it.