clearing an entire dining table at real speed without human intervention.
physical execution in messy facilities demands vla policies that survive domain shifts, dirty plate handling, and bimanual handovers.
every few months, frontier labs take another bite out of software. first text, then code, media, biology.
the defense that "data is the moat" evaporates the moment a frontier model generalizes. in physical ai, contact dynamics and real-world compliance remain the moat.
the next 6 months in physical ai is about agentic harnessing: fast system-1 models directing smaller composable vla policies inside classical autonomy.
stop waiting for monolithic models to solve everything. ship narrow learned skills the moment they work.
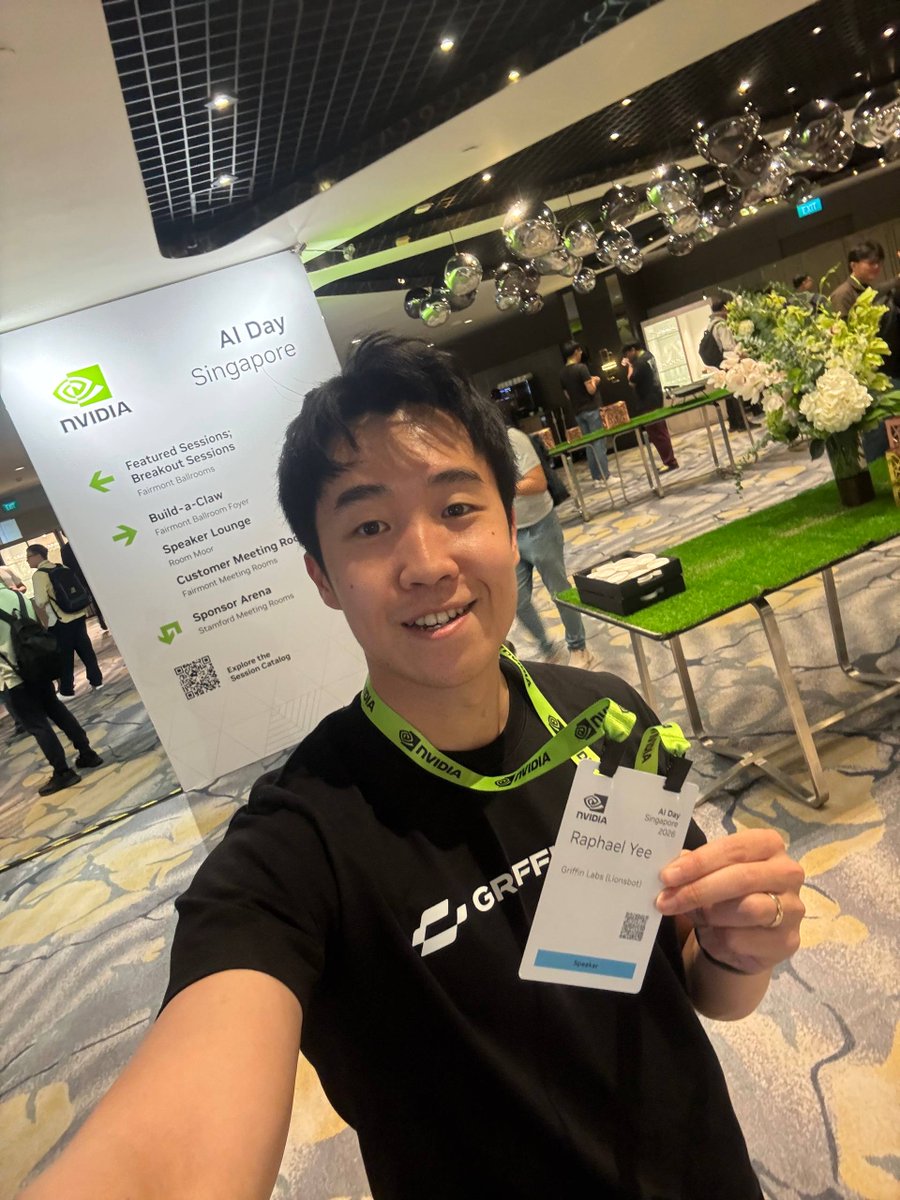
spoke on physical ai at nvidia ai day yesterday in singapore.
joined the panel on accelerating physical ai adoption from research into industry across the ecosystem.
this is insane. i genuinely don't understand why ambitious people aren't shown this lecture before their careers start consuming their entire lives.
clayton christensen spent his career studying why successful companies collapse. in his final class, he asked students to apply the theory to themselves: if you keep allocating your time the same way, what life are you actually building?
he had already seen the answer in his own harvard mba class. everyone looked successful at the fifth reunion; by the 10th, 15th, 20th, and 25th, many were unhappy, divorced, and living far from their children.
work shows you the score immediately. close a sale, ship a product, finish a presentation, earn a promotion, get paid.
an hour with your child may produce nothing you can measure today; it may take 20 years to understand what that hour built. so the next free hour goes back to work, one rational decision at a time.
this is how people build lives they never planned: through hundreds of right decisions that lead in the wrong direction, day after day.
money, titles, and headcount are easy to count. christensen believed a life should be measured by the people who became better because you were there.
he died in 2020.
one question remains: if someone saw only where your time, energy, and attention went this year, what would they think actually mattered to you?
the full 19-minute lecture is in the video below.
3. Extreme stratification.
Frontier AI companies and low P/E "IRL" businesses (e.g. F&B, facilities, logistics) are both defensible to frontier AI appetite, while the middle collapses.
Are we heading toward a world where every defensible startup has to touch atoms?
Every few months, frontier labs take another bite out of software. First text, then code, media, biology, now robotics.
The defense that "distribution is the moat" feels like cope. Frontier labs already have enterprise distribution. Vertical expansion is trivial.
2. Un-scrapeable physical feedback.
The internet was a free dataset, but the physical world has no public archive. You can't scrape contact friction or micro-slips (sim chips away over time). Models stay blind until hardware physically deploys to capture reality.
1/ Today we're open-sourcing Griffin Alpha-S 🔥 The core of Griffin Alpha, our robot foundation model. One set of weights, built for rooms it wasn't tuned in. Level with SOTA on LIBERO. Top VLA under domain shift on RoboTwin 2.0. + CleanBench, a new real-robot benchmark 🧵
1/ Today we're open-sourcing Griffin Alpha-S 🔥 The core of Griffin Alpha, our robot foundation model. One set of weights, built for rooms it wasn't tuned in. Level with SOTA on LIBERO. Top VLA under domain shift on RoboTwin 2.0. + CleanBench, a new real-robot benchmark 🧵
cleanbench vs pi0.5 under identical recipe:
20/20 clearing sink countertop
9/10 folds
10.0/15 clearing dining table
weights, code, and cleanbench scoring rules are up on hugging face.
blog:
https://t.co/eJ4uws8NAw
releasing griffin-alpha and griffin alpha-s.
griffin-alpha is a sota vla model for long-horizon and domain shift tasks in high-complexity facilities.
we're also releasing griffin alpha-s to the community: open weights, pi0.5-level.
benchmarks across simulation and physical tasks:
libero: 94.0 long-horizon suite (ahead of pi0.5 at 93.0).
robotwin 2.0: top vla on hard setting, retaining 77% score under randomized scene.
World-action models typically imagine the future in RGB – but are pixels really the right representation for robotics?
Our bet is no: RGB spends capacity on fine-grained details and variation that are often irrelevant for robot policies.
DINO features, point tracks, and depth capture more useful features like semantics, motion, and geometry.
But no single modality captures everything — how can we effectively combine them?
We introduce ✨ModAR✨, which predicts the future one modality at a time, with each prediction informing the next. We train from scratch and find that this formulation performs best.
Our 30.1M scratch-trained model even outperforms a 6B video-model-initialized model finetuned on the same data!
🧵 [1/8]
Yann LeCun has changed the game for robotics.
His team discovered that AI world models are "thinking" in twisted, curved geometry, and every RL algorithm you know has been fighting against it without anyone noticing.
For years, we’ve been trying to teach AI how to navigate the physical world.
And for years, it has stubbornly struggled with complex, fluid robotics.
Now we know exactly why.
Every standard reinforcement learning (RL) algorithm assumes the AI's internal "world map" is flat. Euclidean. Simple straight lines.
But LeCun's team looked inside the latent space of these advanced world models.
The AI wasn't building a flat map. It was building a curved, high-dimensional geometry.
Every time a robot tried to plan a movement, the traditional RL algorithm was forcing a straight line onto a twisted, non-Euclidean space.
It’s like trying to navigate the globe using a flat piece of paper.
The math breaks down. The distances get distorted. The AI gets confused.
The robot was literally fighting its own brain.
So, the researchers did something brilliant. They stopped fighting.
They rewrote the RL algorithms to operate natively in this curved geometry. They aligned the training to the exact shape of the AI's thoughts.
The results are a massive leap forward.
When you let the AI plan in the geometry it actually built for itself, training efficiency skyrockets. Planning becomes fluid.
Robots stop hallucinating impossible physics and start moving with natural, intuitive logic.
We spent billions of dollars trying to brute-force AI into understanding our physical world.
It turns out, the AI already understood it perfectly.
We were just forcing it to think flat.
@Winniechen02@ToruO_O Hardware design entirely through Astra is still not possible today. We build 000s of robots and we’re using VLM computer use but it definitely still fumbles … I’d say it’s a year out at least before it can take a whole subsystem