Madhuram-v1 is here.
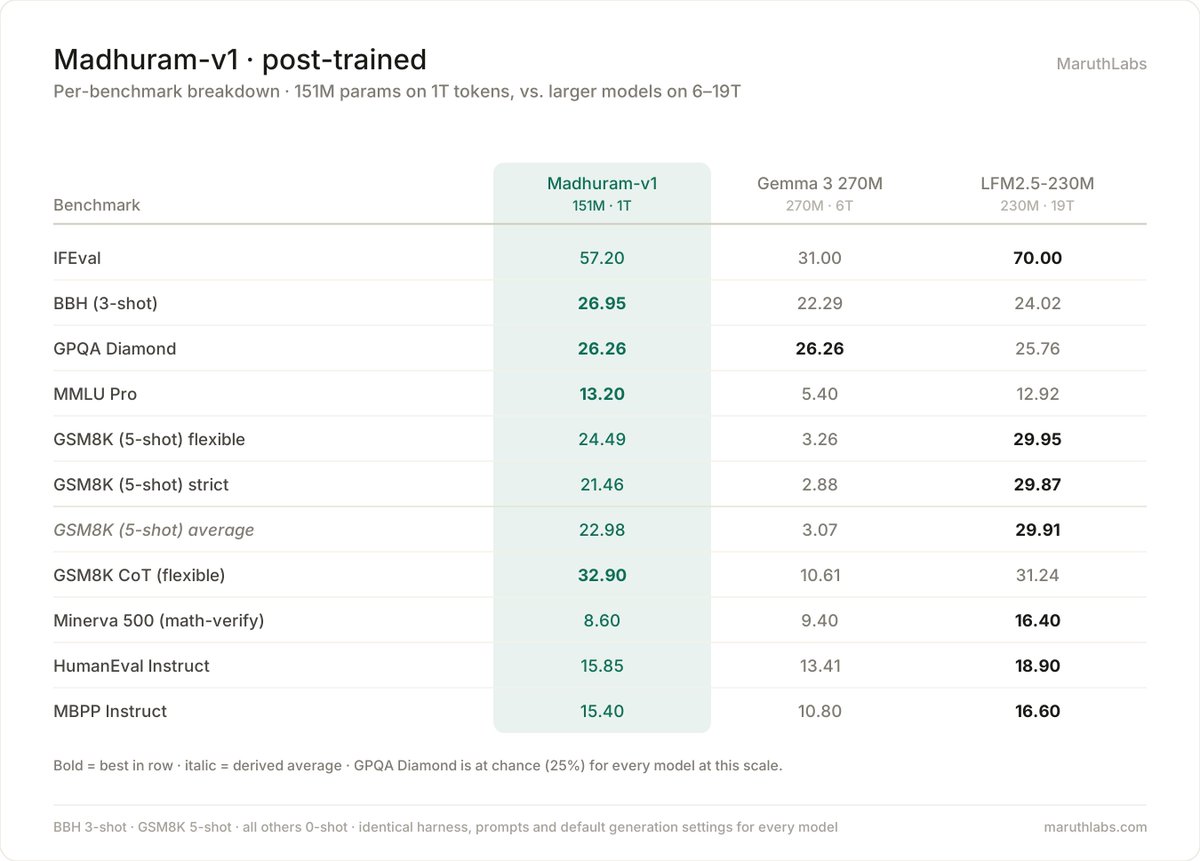
Same 151M architecture as our last release. What changed: more pretraining data, and a much stronger post-training pass on top of it.
It’s a big step up across the board. Full breakdown:
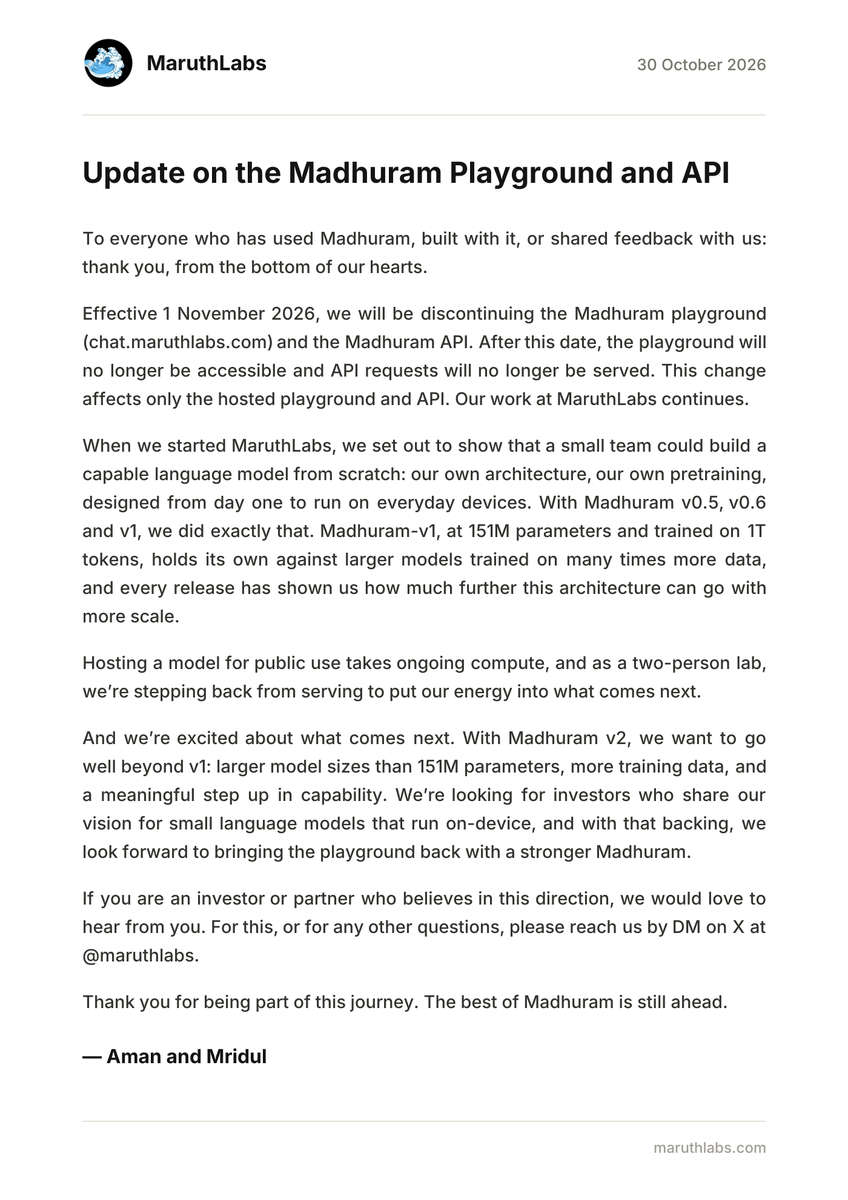
An update on the Madhuram playground and API.
From 1 November, https://t.co/h7c8a7FiAi and the Madhuram API will be discontinued. Our work on Madhuram continues, and we’re excited for what v2 will bring.
Thank you to everyone who used it and shared feedback 🙏
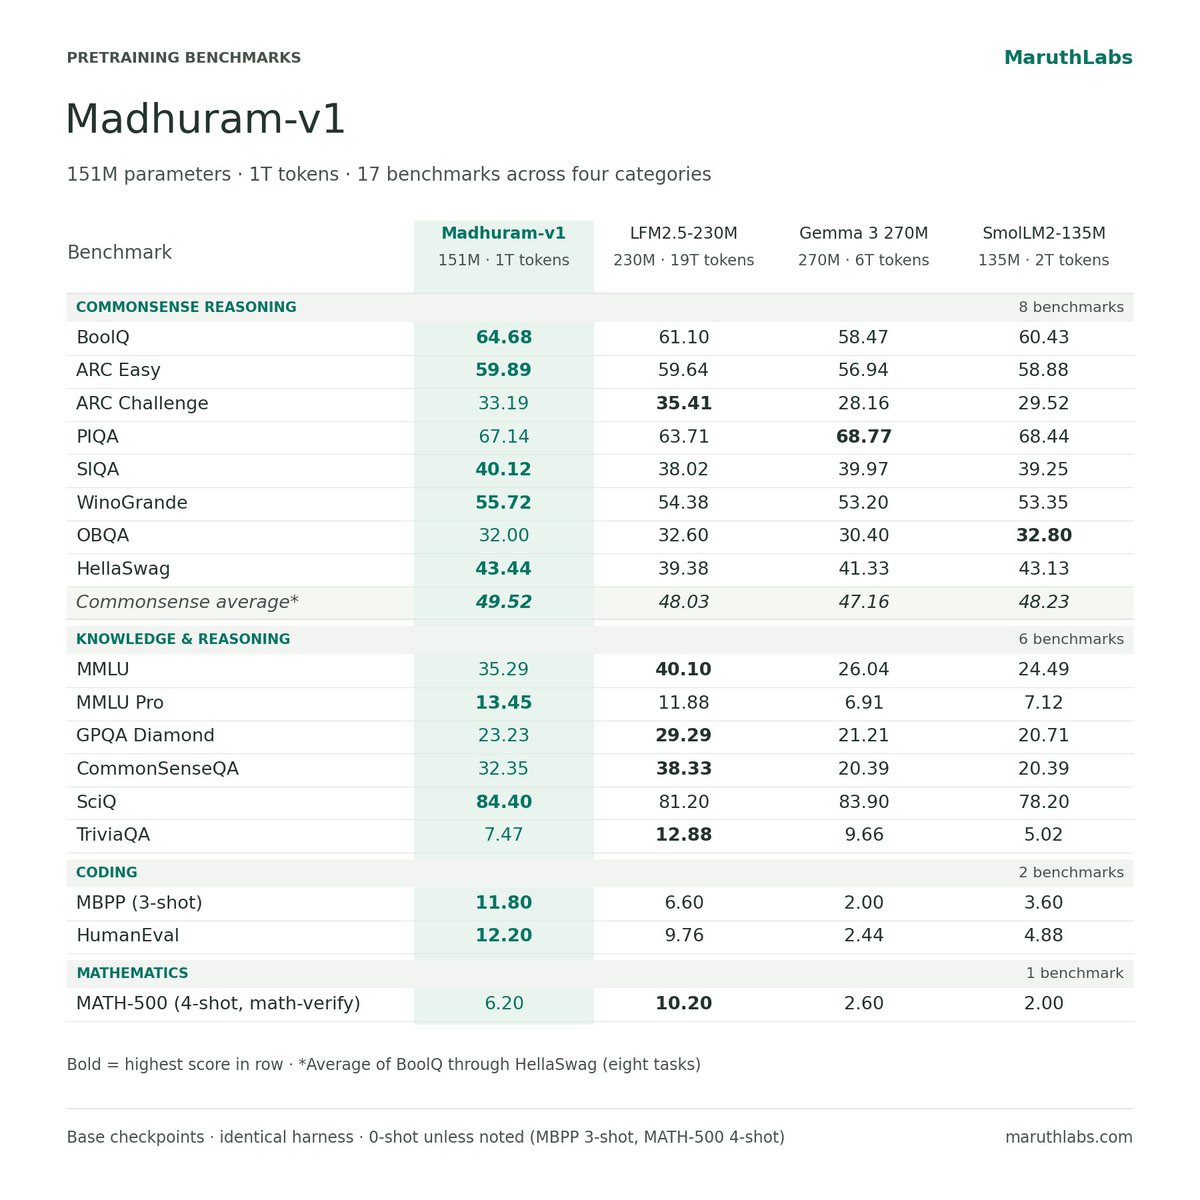
Introducing Madhuram-v1, a 151M-parameter language model trained on 1T tokens.
It leads 9 of 17 pretraining benchmarks against LFM2.5-230M, Gemma 3 270M and SmolLM2-135M, models trained on 2-19x more data.
Here's the full breakdown. 🧵
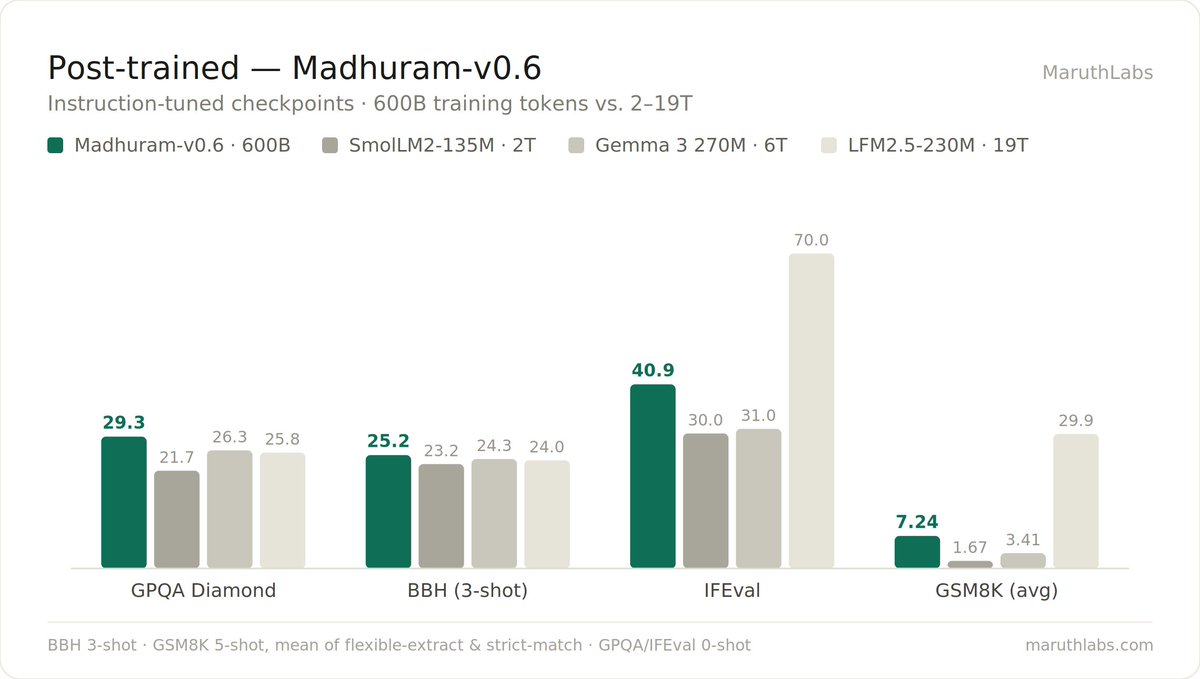
Madhuram-v0.6 is post-trained and our API is live and free.
Our 151M model leads GPQA Diamond, BBH and IFEval against SmolLM2-135M and Gemma 3 270M, both trained on far more data.
Against LFM2.5-230M (pretrained on 19T tokens, 32× ours) we split: we take GPQA and BBH, it takes IFEval and math.
Try it: https://t.co/a1h8Ab2NKH
Build using our API: https://t.co/HsYHtYnyuM
Madhuram-v0.6 is post-trained and our API is live and free.
Our 151M model leads GPQA Diamond, BBH and IFEval against SmolLM2-135M and Gemma 3 270M, both trained on far more data.
Against LFM2.5-230M (pretrained on 19T tokens, 32× ours) we split: we take GPQA and BBH, it takes IFEval and math.
Try it: https://t.co/a1h8Ab2NKH
Build using our API: https://t.co/HsYHtYnyuM
Madhuram-v0.6 running fully on-device on Nothing Phone (3a). Airplane mode on. No server, no API call - a 151M model & llama.cpp.
100 MB on disk at 4-bit. Here's how it fares against other models in its size range.
Same device, build & quantization throughout. Numbers below 👇
Introducing Madhuram-v0.6 - a 151M-parameter language model trained on just 600B tokens.
That's 3–10× less data than the models we put it up against. Here's how it stacks up on standard pretraining benchmarks 👇
Hiring: Research Intern @ MaruthLabs
We are looking for a Research Intern to join us for a 3-month internship focused on pushing the boundaries of high-performance Small Language Models (SLMs).
The Role:
• Research & Experimentation: You will be given access to 0.5x H100 GPU compute to test and iterate on your own research ideas.
• Scaling Up: Upon reaching your research milestones, you will be granted access to an 8x H100 node for a full-scale training run.
• Integration: Successful experiments and optimizations will be integrated directly into our core model training pipelines.
Requirements:
• Strong proficiency in Python and a deep understanding of Transformer architectures.
• A research-oriented mindset with an interest in SLMs, efficiency, and context-length expansion.
• Degree is not a barrier: We value proof of work, GitHub contributions, and technical curiosity over formal credentials.
Details:
• Stipend: ₹15,000 per month.
• Duration: 3 Months (Extendable).
• Location: Remote.
How to Apply:
Interested candidates should send their CV and a brief outline of a research idea they would like to explore on an H100 to [email protected].
#MaruthLabs #LLM #Research #Hiring #MachineLearning #SLM
Reaching out to all investors of X.
AI agents today route every step through frontier models, burning 10-100× more compute than necessary.
At MaruthLabs, we’re fixing this by building purpose-built small models for agent workflows.
We recently launched Madhuram, a 150M parameter model built on our patented architecture Perseus, designed to drastically reduce GPU inference cost and latency.
Our focus is on high-value verticals like Legal AI and compliance, where efficiency and reliability matter most.
We’re now raising to scale compute, expand research, and accelerate enterprise adoption.
If this space interests you, DMs are open.
Our internal chat playground is finally open to everyone!
It’s still early, so expect some rate limits and slower speeds. No fluff, just the models, the best way to see what the tech can really do.
Try it here: https://t.co/HsH7MNKJYe