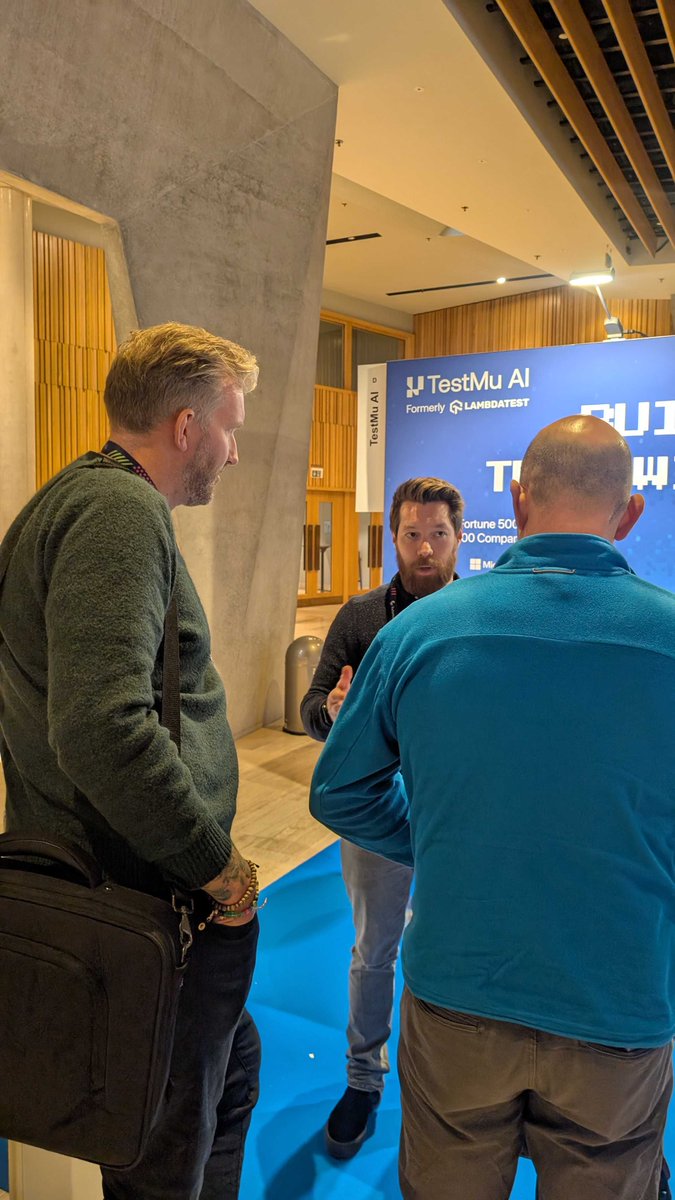
A few glimpses from Web Summit Lisbon, where the TestMu AI team has been connecting with engineers and AI leaders shaping what comes next.
From conversations around AI agents and agent testing to the energy on the show floor, it’s been exciting to see how quickly the AI ecosystem is moving and how strongly the need for quality is growing alongside it.
📸 Sharing a few moments from the summit.
Great people. Big ideas. An exciting future for AI.
#WebSummit #WebSummitLisbon #AgentTesting #QualityEngineering
Automation STAR was a great reminder of how quickly the conversation around AI and Quality Engineering is evolving. 🚀
From Arpit Verma taking the stage to a packed TestMu AI booth, we had some fantastic conversations with testers, automation engineers, and QA leaders exploring what AI means for the future of testing.
Sharing a few moments from the event and taking plenty of great ideas with us for what’s next. 👥🤝
Thank you, Antwerp, for the conversations, curiosity, and energy!
#AutomationSTAR2026 #TestAutomation #SoftwareTesting @AutomationConf
Your app passed every test.
A screen reader user still couldn't find the Pay button.
Tests check what's on screen. Screen reader users hear it. An icon with no label is read out as "Button." A product photo is read out as "IMG_0042, image."
You only catch this if someone runs the app with VoiceOver or TalkBack on, before every release.
@testmuai does that for you. Screen Reader Automation runs your Appium tests on real devices with the screen reader on, records what it says at every step, and flags spoken output that doesn't make sense.
@jasonlk on @20vcFund with @HarryStebbings : Said code review could be the most important category in software, because AI writes code fast, but getting it production-ready is still the hard part.
He’s right about the bottleneck. AI made writing code cheap. Knowing that it works is now the expensive part.
I’d just put the category one step further.
Review is a judgment about code. Verification is evidence about behavior. As AI writes more of the code, the gap between them grows.
𝗩𝗼𝗹𝘂𝗺𝗲. No team can read every diff when AI writes most of them. So review becomes AI reading AI. That’s a second opinion, not proof.
𝗕𝗹𝗶𝗻𝗱 𝘀𝗽𝗼𝘁𝘀. The failures users feel rarely live in the diff: a checkout bug that only shows up on Safari, two changes that pass alone and break together, a dependency update nobody touched.
𝗧𝗵𝗲 𝘁𝗲𝘀𝘁𝘀 𝘁𝗵𝗲𝗺𝘀𝗲𝗹𝘃𝗲𝘀. If the agent that wrote the code also writes the tests, a green build is the agent’s own account of its work.
So the category that matters isn’t review, or testing as we’ve known it. It’s independent verification: proof, from outside the agent, that the software works on the real app, for real users.
Review tells you the code looks right. Verification tells you it works.
That’s the layer we’re building at @testmuai .
AI ASSURANCE WILL BE BIGGEST CATEGORY in future.
https://t.co/EGb1WM2hk2
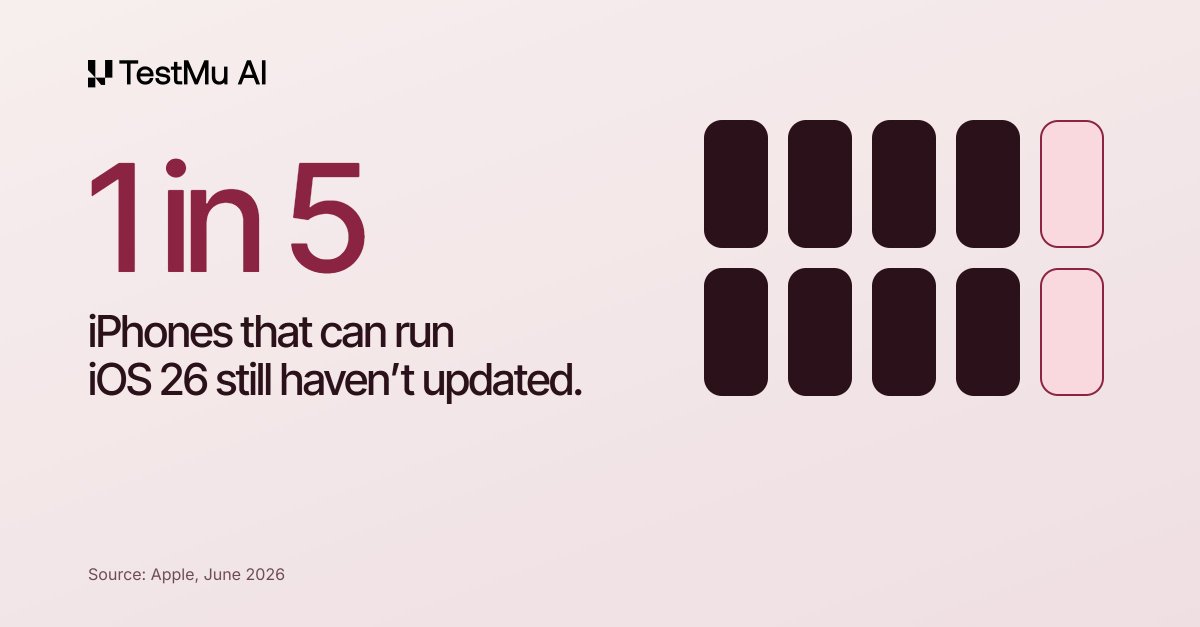
Even among iPhones that can run iOS 26, about 1 in 5 still haven’t updated. (Apple, June 2026)
Your customers are on older phones and older software, and that’s where the bugs you never saw in testing show up.
Test on the real iPhones they carry.
Coding agents now write software faster than most teams can test it. We set out to close that gap.
Two years ago, we asked: what should quality assurance look like in an agentic AI world?
Today, TestMu AI is named a 𝗟𝗲𝗮𝗱𝗲𝗿 𝗶𝗻 𝘁𝗵𝗲 𝟮𝟬𝟮𝟲 𝗚𝗮𝗿𝘁𝗻𝗲𝗿® 𝗠𝗮𝗴𝗶𝗰 𝗤𝘂𝗮𝗱𝗿𝗮𝗻𝘁𝗧𝗠 𝗳𝗼𝗿 𝗔𝗴𝗲𝗻𝘁𝗶𝗰 𝗦𝗼𝗳𝘁𝘄𝗮𝗿𝗲 𝗤𝘂𝗮𝗹𝗶𝘁𝘆 𝗔𝘀𝘀𝘂𝗿𝗮𝗻𝗰𝗲 𝗣𝗹𝗮𝘁𝗳𝗼𝗿𝗺𝘀.
I’m proudest of the team that built for this category before it had a name:
𝗞𝗮𝗻𝗲𝗔𝗜 𝗮𝗻𝗱 𝗞𝗮𝗻𝗲 𝗖𝗟𝗜: tests planned, authored, and evolved by your coding agents
𝗔𝗴𝗲𝗻𝘁 𝗧𝗲𝘀𝘁𝗶𝗻𝗴: evaluating chat, voice, IVR, and video agents
𝗔𝗴𝗲𝗻𝘁 𝗔𝘀𝘀𝘂𝗿𝗮𝗻𝗰𝗲: validating how agents behave across workflows and tools
To our customers and QE community: thank you for trusting us early, challenging us, and building this future with us.
AI can build faster. Our job is to make sure what it builds can be trusted.
Report here: https://t.co/UHBdDPP8oz
A new milestone for TestMu AI.
TestMu AI has been positioned as a Leader in the 2026 Gartner® Magic Quadrant™ for Agentic Software Quality Assurance Platforms.
As software development evolves with AI and agentic workflows, we’re focused on helping engineering teams evolve quality engineering alongside it with AI-powered test authoring, agent testing, scalable test execution, and development workflow integrations.
We believe this recognition reflects our continued focus on helping enterprises adopt a more intelligent approach to software quality.
Read the complimentary Gartner® report →
https://t.co/MZOkPfyJdj
@Gartner_inc
We’re proud to share that TestMu AI has been positioned as a Leader in the 2026 Gartner® Magic Quadrant™ for Agentic Software Quality Assurance Platforms.🚀
The Magic Quadrant evaluates vendors based on Completeness of Vision and Ability to Execute.
This recognition marks an important milestone in our journey to advance agentic quality engineering and help enterprises navigate the evolving landscape of AI-driven software development.
Stay tuned for more details and complimentary access to the Gartner® report.
While the world debates Muse vs Instinct. OpenAi vs Anthropic and everything agentic
@asad0801@testmuai have quietly built a stack to test agents esp for enterprise use cases across calibres and are owning it. I didn't know Salesforce and OpenAi test use their stack. 😲
I heard them this evening in Amsterdam at a community meet up and it was infectious.
Manish and Asad winning hearts of nerds in the room. 💙
🦸🦸🦸🦸
Dreamforce 2026 is almost here, and the TestMu AI team is heading to San Francisco. 🚀
We’ll be there for conversations around Agentic AI, AI-native testing, and the future of Quality Engineering, with a closer look at how teams can validate AI-driven systems without slowing delivery.
If you’re attending, stop by the TestMu AI booth to meet the team, exchange ideas, and see what modern testing looks like when agents become part of the software lifecycle.
Meet 🤝 Javier Bastante, Kavya Nair, Kacie Beth, Madhusudan Laxmanrao, Misbah Farooqi, Mohit Juneja, Ruehan Hamid, Sudhir Joshi, Sparsh Kesari, Todd Lemmonds, Udit Wadhwai, Wendy Zingher
📍 Booth 108
🗓️ September 15–17, 2026 | San Francisco
Come say hello and tell us what you’re building.
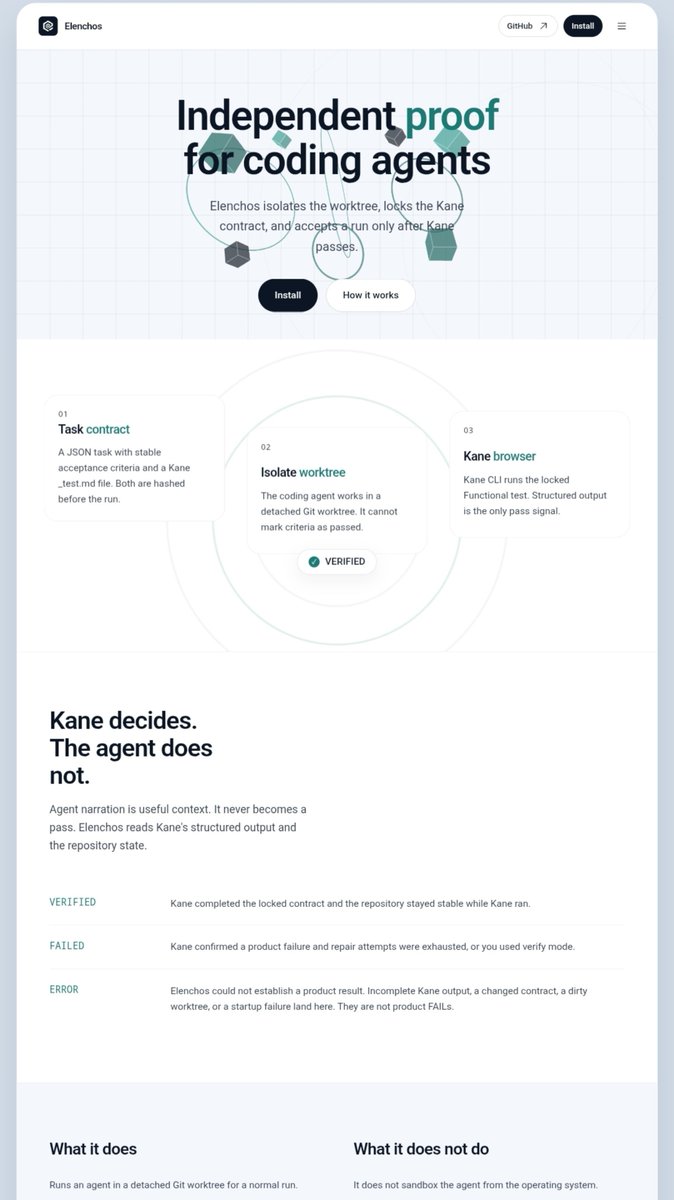
Just submitted Elenchos to the Kane CLI Online Hackathon
Elenchos is an MCP-enabled verification layer for AI coding agents, built around a simple rule: an agent saying “done” isn’t proof that the product works.
through MCP, agents can inspect verification readiness, work with task and acceptance contracts, and invoke elenchos directly from their workflow. elenchos then runs the implementation in an isolated Git worktree and hands the real user flow to Kane CLI for browser verification
the loop:
Agent builds → Kane verifies → FAIL → structured evidence returns to the agent → agent repairs → Kane reruns the unchanged contract → PASS
for the recorded run, Kane caught a real broken task flow. Elenchos sent that evidence back to Gemini, the agent fixed the implementation, and Kane passed every acceptance criterion on the second attempt
It also includes:
• MCP server + agent-facing tools
• Kane-powered test authoring
• Fixed, hashed verification contracts
• Isolated Git worktrees
• Bounded automatic repair
• Criterion-level verification
• Repository-state integrity checks
• Persistent verification evidence
• doctor for environment + Kane readiness
the goal is simple: give AI coding agents a verification loop where completion is earned by evidence
docs is live : https://t.co/51rapwMoWU
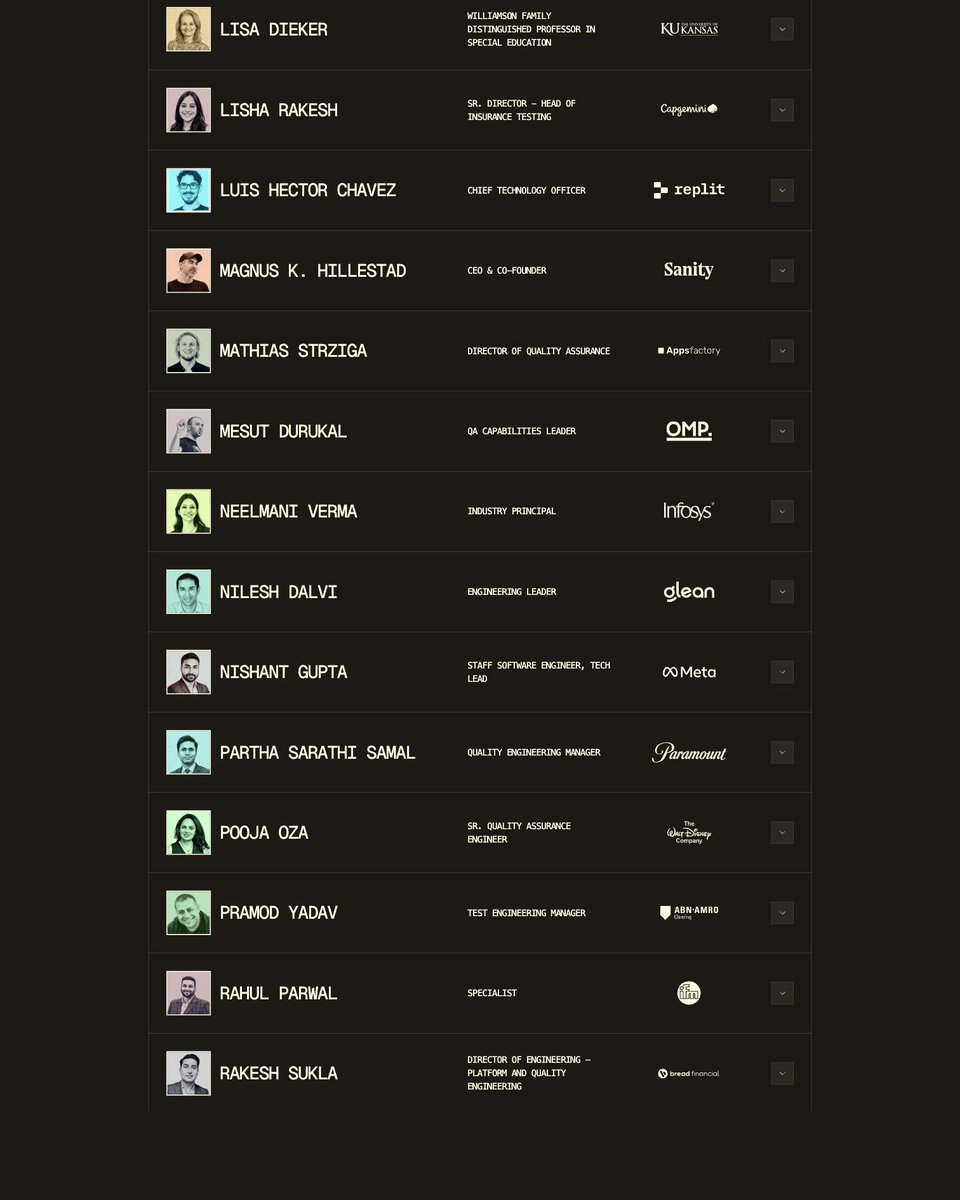
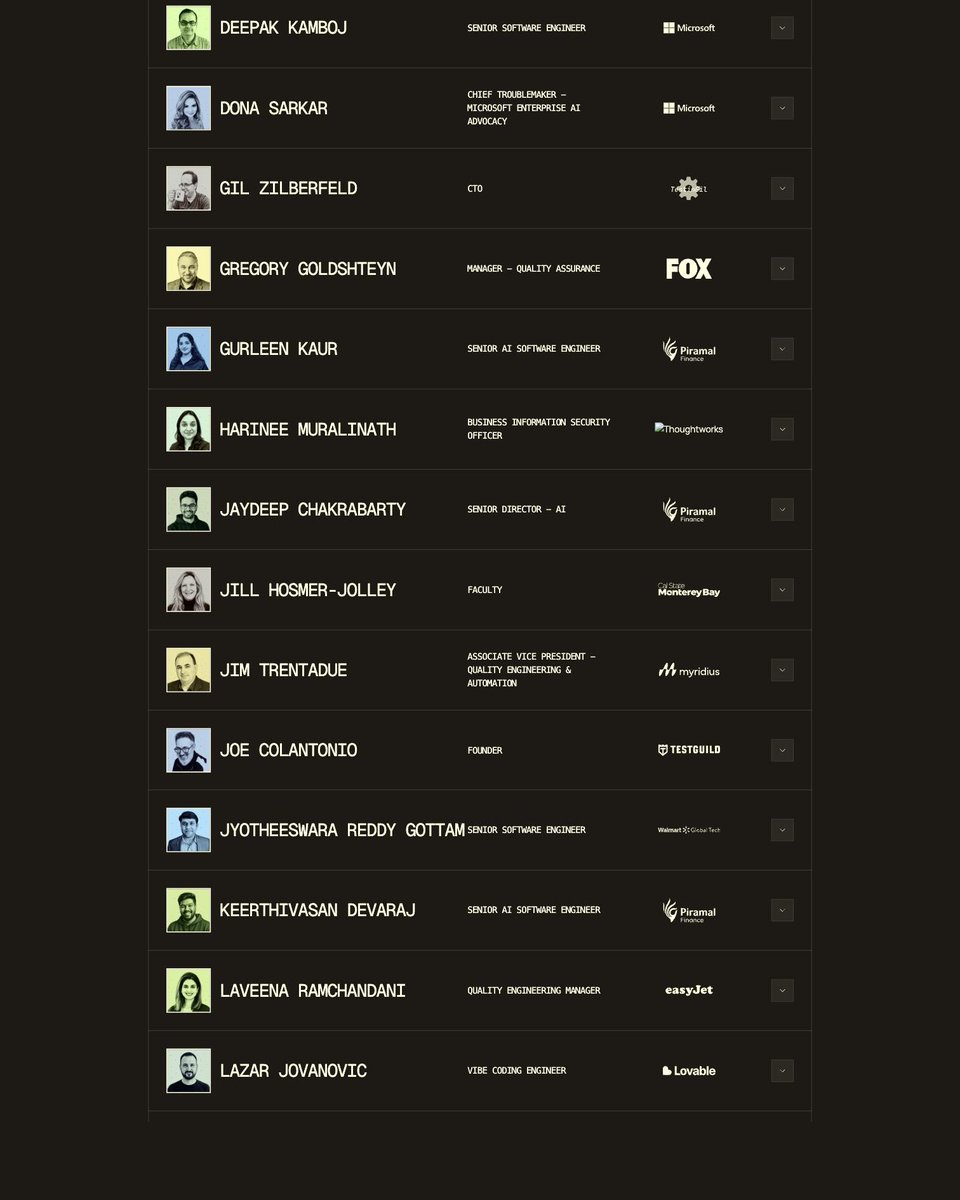
93 sessions 🤯 🤯 so much learning, so much networking. If you still haven't signed up. Please do so. It's totally free, virtual, no travel. You can barely find this lineup ever in any conference. DON'T MISS THE OPPORTUNITY.
https://t.co/RonROmx8Ti
PRIZE MONEY $$$ , FREE WORKSHOPS, FREE CERTIFICATIONS. GET READY FOR THE FUTURE.
TestMu Conf v5 ships Aug 19–21.
3 unreleased products. 80+ sessions. 100K registered. 3 days, free and online.
If you test software or fund the people who do this is the one to watch.
↓ register
Manual testing isn't dying.
It's already being outpaced by AI agents that test while you sleep. And in August, 75,000+ engineers from 120+ countries are meeting to figure out what comes next.
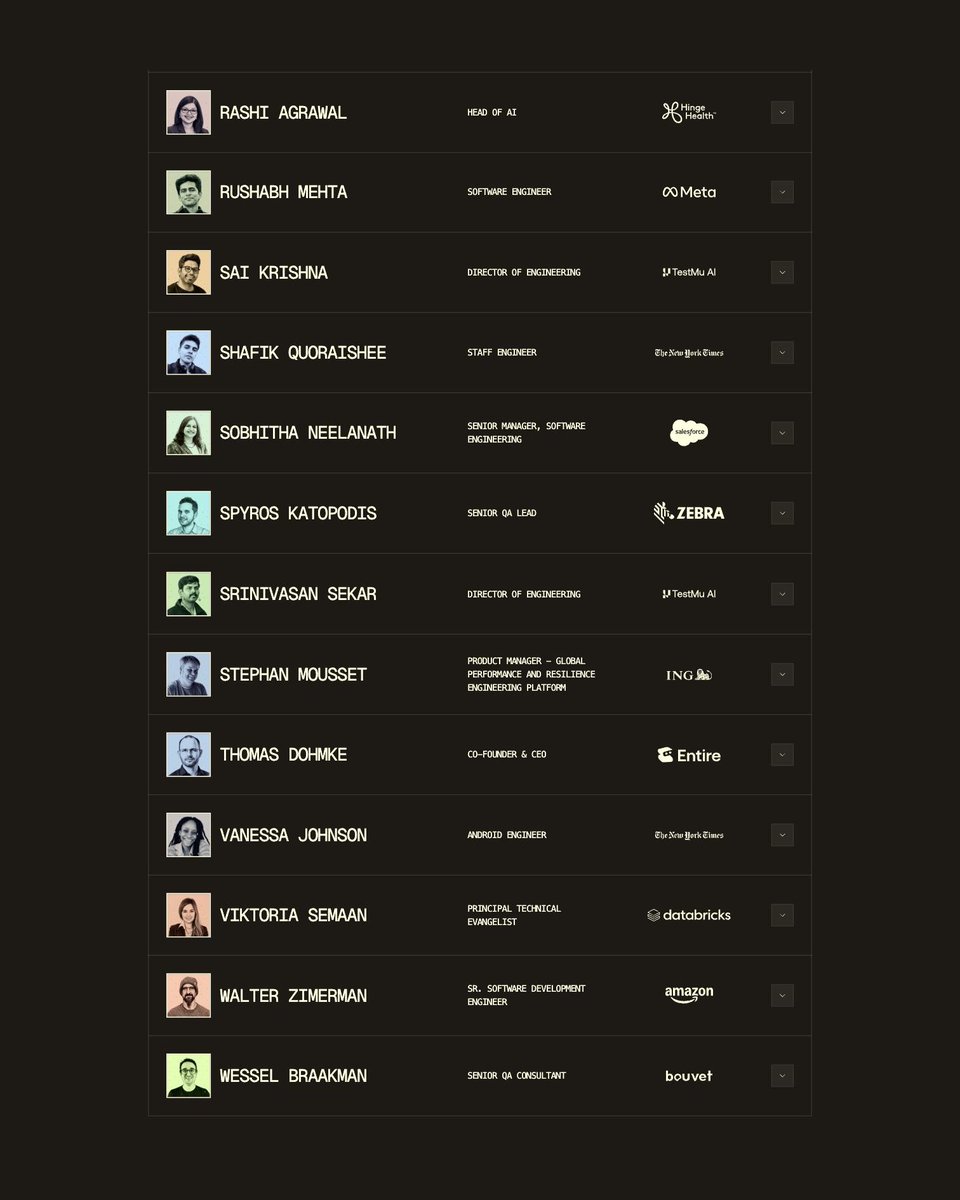
TestMu Conf 2026 (Aug 19–21, virtual, 100% FREE) 🎯
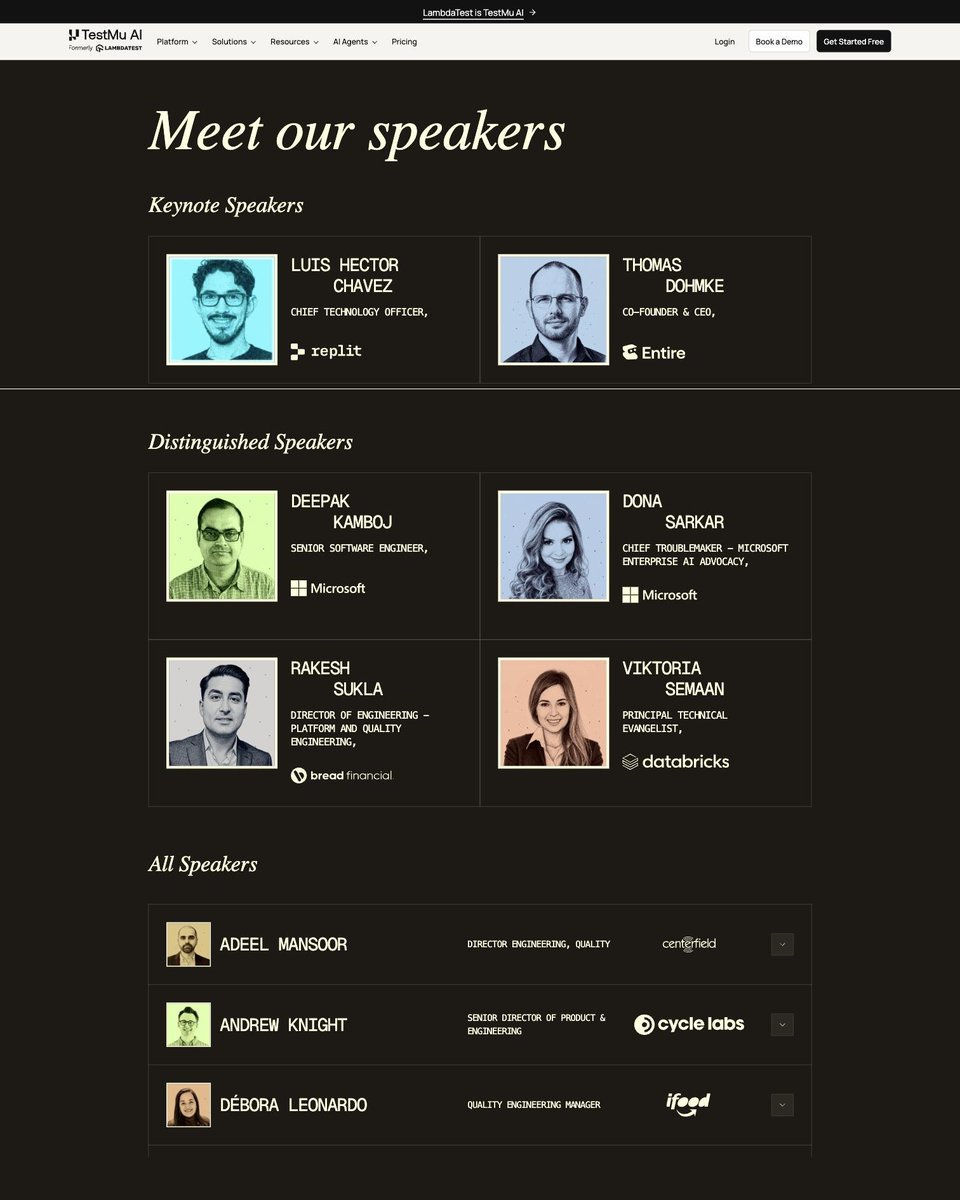
The lineup is unreal:
→ CTO of Replit @lhchavez
→ Thomas Dohmke (yes, the former GitHub CEO) @ashtom
→ Engineers from Anthropic, Meta, Microsoft & Databricks
80+ sessions on agentic engineering, autonomous QA, and AI-native testing.
Plus $15,000 in prizes.
Here's my honest take:
The engineers who thrive in 2027 won't be the ones who "learned AI."
They'll be the ones who learned to orchestrate it.
This is 3 days of exactly that. For free. From your desk.
🔗 Registration link in comments 👇
♻️ RETWEET so your QA network doesn't miss this.