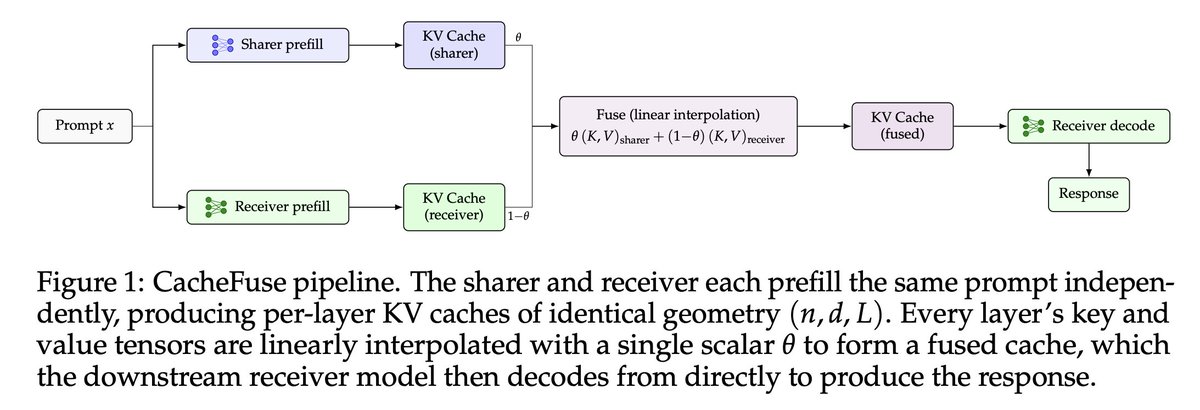
CacheFuse is an early attempt in cross-model KV cache reuse that demonstrates that linearly interpolating the KV caches of two models can outperform a standalone model’s cache alone. I’ll be presenting it tomorrow at #COLM Efficient Reasoning Workshop - stop by!
adding CacheFuse (@rishiskhare, COLM 2026 workshop) to the latent communication series, because it's the simplest version of the idea I've seen work
Qwen3-8B and Qwen3-4B have KV caches of exactly the same shape, so you can just blend them (roughly half and half) and let the 4B answer from the mix so there's no training at all
the 4B gains up to 8.6 points and beats the standalone 8B on all four benchmarks (best mix picked per benchmark, though a held-out calibration lands close)
however this trick needs siblings with matching cache shapes and a shared tokenizer, while e.g. models different by x200 is sizes and from different families have nothing to blend, which is the case we train a bridge for at @mostik_ai 🌉
@aimalysheva Thanks for sharing! Indeed a surprisingly simple and elegant finding - though I wonder if model providers will make future model family releases that have model pairs that share KV cache shapes to make adapter-free transfer possible.
adding CacheFuse (@rishiskhare, COLM 2026 workshop) to the latent communication series, because it's the simplest version of the idea I've seen work
Qwen3-8B and Qwen3-4B have KV caches of exactly the same shape, so you can just blend them (roughly half and half) and let the 4B answer from the mix so there's no training at all
the 4B gains up to 8.6 points and beats the standalone 8B on all four benchmarks (best mix picked per benchmark, though a held-out calibration lands close)
however this trick needs siblings with matching cache shapes and a shared tokenizer, while e.g. models different by x200 is sizes and from different families have nothing to blend, which is the case we train a bridge for at @mostik_ai 🌉
@mitchellh@poojabnf What’s your workflow for fable 5 -> gpt 5.5 -> fable 5? How do you orchestrate them - do you use the skill to use Codex with Claude Code?
I'm surprised by this - does it really perform as good as Opus when you use it within the Claude Code harness? For these long-horizon planning and agentic coding tasks, nothing has come close to Opus on CC for me. I contributed to this repo: https://t.co/687ubI6S2S and I still come back to Opus
@ZackKorman Which data sources are your agents able to pull from and in your experience, which data source has been the most valuable in this triage process?
@ZackKorman Idk, I interviewed with the team last fall, so pre-openclaw (article seems to be before then as well). Most of the industry work on this seems to be proprietary and closed-source, but this triage project is OSS on GitHub