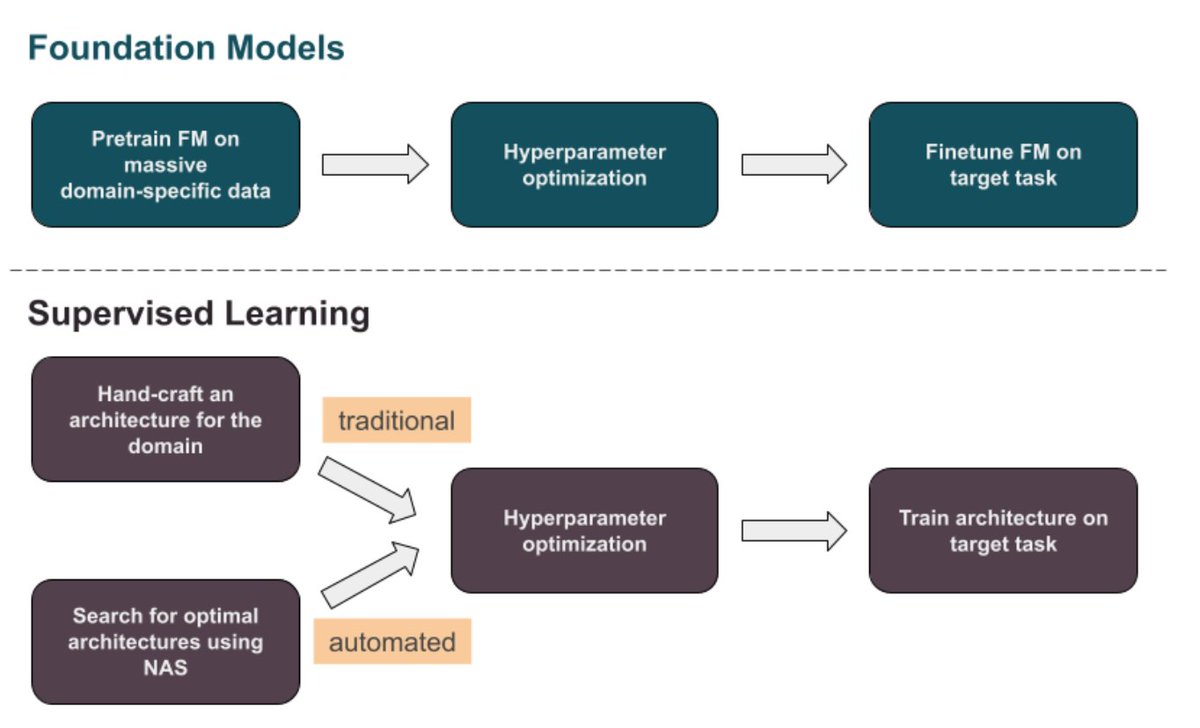
Check out some really interesting results from our study! Despite the wave of FMs in specialized domains such as genomics, satellite imaging, and time series, most of these specialized FMs are often no better--and sometimes even worse--than simple supervised baselines.
🧵 on surprising revelations from our study of specialized foundation models (FMs beyond vision/text): after evaluating dozens of scientific & time series FMs we found that most weren’t even competitive with simple supervised models, some with as little as 513 parameters.
1/n
SOV-Transcribe-1 is now on the @huggingface Open ASR Leaderboard, ranking as the #1 US developed open-weights model! 🚀
Give it a try: https://t.co/daTLjkXQNg
Thanks to @EricBezzam for adding it to the leaderboard!
SOV-Transcribe-1, the latest ASR model from @salesforce , is #2 on Voice Code Bench, and #1 among open-source models.
Voice Code Bench tests how well a model performs in transcribing alphanumeric entities like phone numbers and emails rather than looking at general word error rate, critical for voice agent applications.
SOV-Transcribe-1 is a real solid choice for anyone building voice agents on open-source stack! Check out their blog at https://t.co/JcystpgUq5.
Congratulations @salesforce & team! See the complete leaderboard at https://t.co/WNrfznWiJG
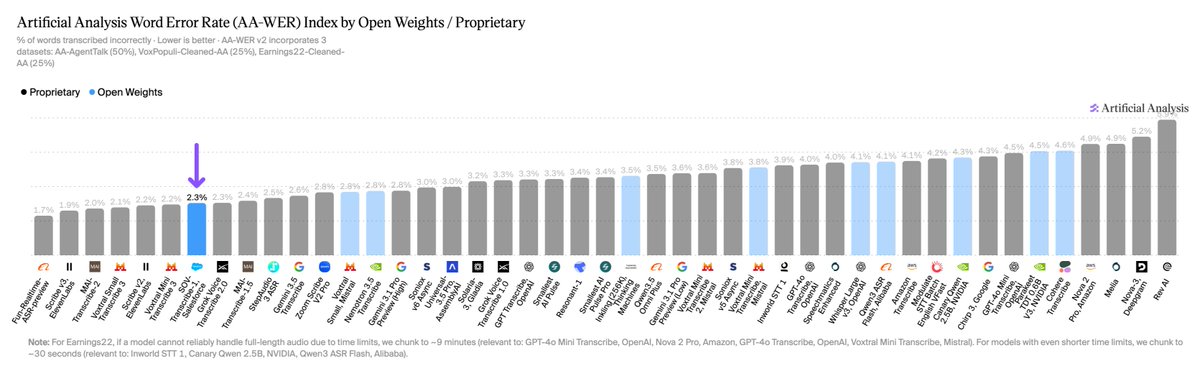
SOV-Transcribe-1 is the new #1 open weights Speech to Text model, scoring 2.3% on the AA-WER Index with 4.6B active parameters. It ranks #7 of 44 models overall, including proprietary models.
Congratulations to @salesforce and the Missionforce Sovereign AI team on the release! 🧵
Introducing SOV-Transcribe-1: our new open-weight speech-augmented language model from @salesforce, built for transcription.
It ranks #1 among open-weight models on @ArtificialAnlys (#7 overall), @besimple_ai VoiceCodeBench (#2 overall), and many other benchmarks!
[1/4] Are models getting better at cross-lingual transfer?
We answer this question in our latest study where we validate 20 LLMs on 3 multilingual benchmarks with a redefined transfer metric.
🔗Paper: https://t.co/KT0v4MAoGm
Excited about our NeurIPS'25 tutorial
Data Privacy, Memorization & Copyright in GenAI
with Cooper (co-founder, GenLaw) & Joe (represents OpenAI, Stability in all US copyright litigations)
We bring together ML researchers, with those who understand its legal implications. Pls RT
Happy to see a time series workshop @ NeurIPS 2025 motivated in part by our search for BERT moments in specialized foundation models (🧵here: https://t.co/d3f676TK0z)
🧵 on surprising revelations from our study of specialized foundation models (FMs beyond vision/text): after evaluating dozens of scientific & time series FMs we found that most weren’t even competitive with simple supervised models, some with as little as 513 parameters.
1/n
I have some news to share!
@datadoghq is forming a new AI research lab, and I'm excited to announce that I've joined as Chief Scientist to lead this effort. Datadog has a great work culture, lots of data and compute, and is committed to open science and open sourcing.
Our team is working on ambitious research areas grounded in real-world challenges in cloud observability and security, with three current areas of focus:
1. Observability Foundation Models for forecasting, anomaly detection, and multi-modal telemetry analysis (logs, metrics, traces, etc.).
2. Site Reliability Engineering (SRE) Agents to detect, diagnose, and resolve production incidents.
3. Production Code Repair Agents that leverage code, logs, and runtime data to identify and fix performance issues.
On a personal note, I'm thrilled to work with Oli and Alexis again (we worked together in the early aughts before they co-founded Datadog). I’m also excited that Datadog, as part of its expansion in AI, is partnering with CMU (note: I will continue to work part-time at CMU and maintain my research activities).
Datadog is actively hiring out of our NYC office!
🧵1/ Introducing ScribeAgent 🤖! Using extensive 𝗿𝗲𝗮𝗹-𝘄𝗼𝗿𝗹𝗱 𝘄𝗲𝗯 𝘄𝗼𝗿𝗸𝗳𝗹𝗼𝘄 𝗱𝗮𝘁𝗮, we at @mldcmu and @ScribeHow have adapted 𝗴𝗲𝗻𝗲𝗿𝗮𝗹-𝗽𝘂𝗿𝗽𝗼𝘀𝗲 𝗼𝗽𝗲𝗻-𝘀𝗼𝘂𝗿𝗰𝗲 𝗟𝗟𝗠𝘀 into 𝘀𝗽𝗲𝗰𝗶𝗮𝗹𝗶𝘇𝗲𝗱 𝘄𝗲𝗯 𝗮𝗴𝗲𝗻𝘁𝘀, outperforming traditional agents that rely on proprietary models like GPT-4 and o1-preview.
Learn more about our breakthroughs and findings👇
Turns out that strong baselines still matter in 2024! While there have been a TON of specialized FMs introduced recently, we show that leading FMs in genomics, satellite imaging, and time series are generally no better (and often worse than) much simpler supervised baselines!
Which model is best for coding? @CopilotArena leaderboard is out!
Our code completions leaderboard contains data collected over the last month, with >100K completions served and >10K votes!
Let’s discuss our findings so far🧵
Specialized Foundation Models Struggle to Beat Traditional Supervised Learning Baselines
1. This study provides a rigorous comparison between specialized foundation models (FMs) and traditional supervised learning approaches, revealing that well-tuned CNNs and simple autoregressive models often outperform large-scale FMs across genomics, satellite imaging, and time series domains.
2. Through extensive benchmarking on over 30 tasks, including the Nucleotide Transformer benchmark and satellite imagery datasets, the researchers found that traditional models like Wide ResNet and UNet consistently match or surpass the performance of specialized FMs, despite the FMs’ extensive pretraining on massive datasets.
3. Key finding: In genomics tasks, DASHA, an optimized CNN workflow with architecture search, outperformed FMs on histone modification tasks, challenging the assumption that transformer-based FMs are universally superior.
4. The study introduces an open-source automated tuning workflow, DASHA, which efficiently combines neural architecture search and hyperparameter optimization, demonstrating that resource-intensive FMs are not always necessary for peak performance in specialized domains.
5. Results also show that a simple autoregressive model, with minimal computational demands, matched or outperformed large FMs on time series forecasting tasks. This underscores the importance of strong, well-tuned baselines in FM evaluations.
@atalwalkar@JunhongShen1@WenduoC@ritvikgupta199
📜Paper: https://t.co/InjpiecCzY
#FoundationModels #MachineLearning #Bioinformatics #CNN #TimeSeries #SatelliteImaging
📉Time Series FMs hold promise, but still struggle to outperform well-tuned statistical baselines👇
We need better evals, and more research to unlock their full potential🧠. Let's makes today's TSFMs the dumbest we'll every have!📈
(1/6) Recommender systems shape our digital experiences, filtering much of what we see online. But how should we measure their influence? We provide a unified causal framework to think through this question and develop metrics to audit recommender systems.
https://t.co/Yq9XvLSO2g
Want to scale RL with your shiny new GPU? 🚀
In our ICML24 Oral we find that RL algorithms hit a barrier when data is scaled up. Our new algorithm, SAPG, proposes a simple fix. It scales to 25k envs and solves hard tasks where PPO makes no progress.
https://t.co/qKUJDChpNx
1/n