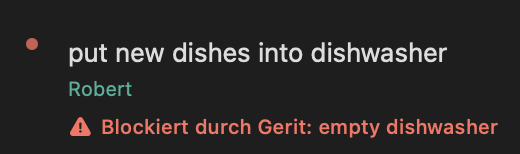
@iamvishal16_ios If a task is blocked by someone else and isn’t currently visible in my view, I see this notice. It tells me which task is blocking it and who’s responsible for that task.
DuetFlow is my native task app for households. I added nested projects so a parent task could run its children in sequence or in parallel. That also meant sorting out who owns a subtask, why my task is blocked when another person's task is hidden by a filter, and how the outline holds together after a reload. The app still felt clunky.
Profiling found unchanged lists being rebuilt over and over, plus a selection/layout loop that pinned the Mac at 99% CPU. Fixing those didn't fix dragging: one gesture could select several tasks, the same gap could point to two different drop destinations, and scrolling stalled when I held a task at the edge. I had to measure each cause separately, use isolated test apps, and try the full held gesture by hand. The verified fixes are merged and installed on my Mac; an intermittent row-height issue is still unexplained.
I've built web apps without this much work for a project outline. Some of it comes from the nested, shared tasks I chose. I still don't know how much comes from SwiftUI and AppKit.
The weekly https://t.co/3HTKWKwg6W automation compares complete weeks across Search Console, Cloudflare, origin logs, and consented product analytics. It found ranking pages receiving Google impressions without the clicks I would hope for. The safest cities page, for example, had 758 impressions and five clicks in one measured week.
I then inspected the queries, their landing pages, and the actual search result. The copy was accurate but too technical. It led with police statistics, measurement years, and rates before explaining why someone should open the page.
I rewrote the titles and descriptions for all 16 rankings and created consistent snippets for all 400 region profiles. Each result now states the page's value directly while keeping Top 25 comparisons and necessary caveats honest. Sources, years, and methodology remain on the page, where they can be explained properly.
The texts are consistent across HTML metadata, Open Graph, and structured data, and I checked every ranking and region name. The automation now has a clear next job: watch what Google displays and whether the clicks improve.
I added Bing Webmaster Tools to https://t.co/3HTKWKwg6W expecting a minor checkbox next to Google.
Google remains the reach channel. Bing matters for another reason, especially while Wohinziehen is early: there are not enough visits or purchases yet to learn from the funnel alone.
Bing’s AI report shows the grounding query, cited URL, citation count, intent, topic, and citation share in Copilot and partner answers. It showed that our cheap-rents ranking is already being used as a source:
https://t.co/kGkfMhmXTt
Google’s generative-AI report showed a different pattern, with air quality as the most-visible page. The reports measure different things, and citations are not traffic.
Bing is worth setting up early. It gives a small product another way to see which pages already answer a real question well enough to become sources before its own funnel has enough data.
Codex doesn't pick up local tasks it interrupted when I quit the Mac app. I wanted to reopen it and have only the tasks that were actually running continue in the same conversation. I built that locally: four running tasks resumed after a real restart, while manual stops and tasks waiting for me stayed put. @thsottiaux, I'd love this in Codex.
To set up the same thing on your Mac, paste this into Codex: "Build and install auto-resume for local Codex desktop tasks. Inspect this Codex install, its hooks, local task status store and any existing sidebar coordinator first; preserve existing hooks. Run an independent macOS LaunchAgent with a native process-exit watcher that atomically records Codex app exits and survives Codex closing. In an app-owned helper, record app epoch, task and turn IDs, and active/waiting/stopped state using UserPromptSubmit, Stop, Interrupt and SessionEnd hooks plus 15-second status checks. On relaunch, use the external exit time to tell shutdown interrupts from manual stops. Resume only tasks active in the previous app run whose same turn is still interrupted; skip input waits, archived or remote tasks, and subagents. Send one continuation through Codex's own send_message_to_thread, keeping the task's model settings. Save a send marker before dispatch; if the result is unclear, compare current turn IDs and never blindly retry. Have the continuation inspect existing work, avoid duplicate actions and honor approvals. Add atomic state, backups, a PAUSED switch and tests. Verify with a real quit and relaunch of several active tasks, then show me which resumed."
It’s hard to name the first thing on my to-do list because I’m working on several features across multiple products. I use my own products every day, so when I run into a problem, I tend to fix it. Focusing on one product might be wiser, but that’s how I’ve been working so far.
I’m happy with how the products work now. Marketing needs more attention, though. I’m experimenting with ChatGPT ads, but OpenAI isn’t displaying them for some reason. I hope that gets resolved soon.
In my day job, I’m used to reaching out to customers directly. That’s harder with Wohinziehen and Kiwi because I’m still figuring out where to find the right people. I’ve spent a lot of time on SEO and other ways to help people discover the products, but I’m starting to think I need to reach out more actively.
So, to answer your question about how I decide what’s worth doing: I look at where people get stuck in the funnel and work through those points one at a time. Going forward, I also want to find and contact potential customers directly.
https://t.co/9rV9QzVCjJ has profiles for all 400 German districts and independent cities. They were built as SEO destinations for people searching for a specific place, but each page also has to earn the click, help someone understand the region, and lead naturally into the product comparison.
When I reviewed the Dingolfing-Landau profile as a first-time visitor, the page tried to cover all of those jobs by showing more. Verdicts, fit advice, warnings, scores, alternatives, methodology, and several calls to action repeated similar ideas. The amount of information obscured the value.
I redesigned that profile around its three jobs, then applied the model to all 400 pages. Each now starts with understandable strengths and weaknesses, explains five visible categories, separates a score from the rank within the federal state, and shows what else can be explored. Neighboring districts create useful internal paths, while the product preview opens with the current region already selected.
I rendered and checked every profile for its data, rankings, visible and locked categories, links, and preview handoff. An SEO page has to attract the right visit, deliver enough value to earn it, and make the next useful step obvious.
Thank you, I’m pretty happy with it. I don’t have much experience with this yet, but I’d give it at least a month, probably two.
In this case, the timing doesn’t matter much. The new snippets are clearly better, so I’m keeping them. I may improve them further down the line, but I have several other areas to work on first.
My weekly Kiwi review found a gap: impressions and downloads were arriving, but few new users appeared to make their first free request.
Kiwi has an unusual activation path. Setup happens on the iPhone, where people learn Ask, Translate, and Memory, grant the permissions they want, and start the free preview. The main experience often happens later, in a different place and interface: connect to the car, open Kiwi on the CarPlay display, then use an on-screen control or press the steering-wheel voice button and speak through Siri. Some voice paths only work when Kiwi is already visible in CarPlay. Every handoff is another place to lose someone.
I simplified the onboarding around that exact journey. It now explains what each feature does, shows how to use it from the car display or through voice control, handles permissions clearly, and ends with one focused action. I also added consent-based telemetry for the path from onboarding and permission outcomes to the first action, successful response, and repeat use.
Now the weekly review can show whether reach becomes setup, setup becomes a first request, and a first request becomes real use. Physical CarPlay and purchase flows still need separate validation.
I've learned that putting a product online and hoping someone finds and buys it doesn't work. Shipping starts a marathon. Once something is live, I need to know who finds it, which channel and search term brought them in, what they click, where they leave the funnel, and whether the tracking is reliable enough to trust any of it.
So I built weekly, read-only reviews for Kiwi Car AI, https://t.co/3HTKWKvIho, and my other products. Kiwi combines Search Console, Cloudflare and live site checks, App Store discovery and downloads, release and subscription state, plus aggregated backend activation and usage. Wohinziehen connects Search Console with Cloudflare, origin logs, and consented journey analytics from landing page through preview, region, paywall, checkout, and purchase.
The setup is reusable: choose one source for discovery, one for product behavior, and one for technical health. Run them on the same schedule, compare complete periods, keep metrics with different meanings separate, label facts and hypotheses, and carry unresolved questions into the next run.
Each review ends with what changed, what is probably noise, where the funnel is weak, whether to act or keep watching, and at most three next steps. The result is a continuous loop of shipping, observing, understanding, and improving.
I lowered the price of 12-month access to https://t.co/3HTKWKwg6W from €59.90 to €29.90. The 30-day option stays at €14.90.
Someone planning a move needs the product now, so 30 days already fits the job. A year may be cheaper per month, but €59.90 meant paying four times as much upfront without an obvious reason to need the product for twelve months. That made the annual option close to pointless.
Keeping access open for a year costs me almost nothing, so €29.90 is a better interim offer. The pricing still isn't final.
A stronger package should feel more useful than the cheapest one. Making the same product available for longer doesn't achieve that yet.
https://t.co/9rV9QzVCjJ helps people compare German districts using a map, filters, and dozens of indicators. That gives people control over a complex decision, but it also makes the product hard to understand the first time they open it.
My first solution was to explain everything directly in the interface. Instructions surrounded the map, filters, and results so people could always see what each part meant. The same screen was trying to teach the product and be the product. It became crowded, and new users still had to explore everything on their own.
I replaced those permanent instructions with a guided onboarding built with Driver.js. It introduces the product, walks through the important steps, then gets out of the way. The workspace stays clean, and people can replay individual chapters later.
Building the tour forced me to decide what a first-time user should understand and see after every step. That exposed a much larger product question.
Maybe people don't want to learn a map and a set of filters. They may want to say that low crime and affordable housing matter, press a button, and receive three districts with an explanation. Most of the tool would disappear, and the product would simply give them an answer.
That version would be easier to use. It would also make many choices for the customer and could remove the product's biggest strength: letting people combine their own priorities, inspect trade-offs, and understand why a place ranks well.
The onboarding improves the product I have today. I now need to test whether people want help using the tool or want the product to do more of the thinking for them.
I asked Astra to improve six ad landing pages for https://t.co/3HTKWKwg6W. They looked polished, but the marketing logic kept failing in obvious ways.
It compared two places using the same rent, showed exact scores without explaining why they mattered to someone's move, invented objections no real visitor had raised, and forgot what the person had clicked the ad to decide.
After correcting the same kind of mistake across several pages, I put my review process into a Marketing Journey skill.
Before Astra writes, it now has to answer four questions: What situation is this person in? What are they trying to decide? What do they already know? What do they still need to understand?
It then chooses a comparison that answers what the person still needs to understand and explains how the numbers affect real life, such as money, time, effort, or an everyday situation. It also checks whether the ad, landing page, and first product screen keep helping with the same decision. Someone who clicks an ad about moving closer to family should not end up in a generic regional dashboard.
Astra didn't do this reliably on its own. The skill gives it a repeatable process and gives me a clear standard for reviewing the result.
If an AI keeps making the same strategic mistake, write down the questions behind your corrections and make it apply them before it starts writing. You stop repeating the same feedback and get a much more consistent starting point.
I normally build products with MVP logic: ship an imperfect first version, watch what people do, and improve it. When I started preparing paid ads for https://t.co/3HTKWKwg6W, I realized that applying the same approach unchanged would be expensive.
If the ad, image, landing page, product preview, or price doesn't fit together, every click costs money before I learn anything useful. A weak result tells me very little. Did people reject the product? Did I reach the wrong person? Did the landing page lose them? Or did the product become confusing after the click?
So before spending, I walked through the complete path for six different moving situations. I defined what each person was trying to decide, what they knew when they saw the ad, why they would click, what they expected next, and which result the product had to show. Then I built a matching ad, landing page, and preview for each path. I also changed the onboarding and pricing when they no longer fit.
I still can't know which message will perform best or how many people will buy. The campaign's job is to scale a coherent offer and measure how it performs. The audience, message, funnel, and product need to make sense before I pay to amplify them.
So I remove every inconsistency I can see before spending. If performance is weak after that, the data means something. Otherwise, I pay to learn that an unfinished funnel performs badly.
More frequent resets make the current token limits easier to live with. They also partly hide how much token burn has gone up.
With GPT-5.4, the weekly budget felt close to unlimited for my workload. GPT-5.5 was the first version that made me change my prompts and setup to avoid hitting limits. GPT-5.6 got worse again before it settled closer to 5.5. With Astra, even Light can burn through the allowance of a $200 subscription in a day.
The resets are useful, but they are also needed: they make the higher burn easier to absorb. Without them, the cost increase would be much harder to ignore.
I don't share the "Astra is AGI" take.
I recently asked Astra to revise ad landing pages. I gave it the funnel and clear instructions more than once. The pages still missed the point, and I had to keep reworking them.
A landing page needs to move a new visitor's understanding step by step. That means tracking what they already understand, what the last section changed, and what they need to see next.
With coding, I can often describe the outcome and let the model execute. I can hand it the same kind of brief for marketing, but I still have to hold the reader's mental model myself.
Thanks for posting this. It’s a great summary and offers a helpful view of what may be happening behind the scenes. I wish someone from one of the major AI labs had explained it this clearly sooner for those of us on the outside.
I’ve never found the regulatory capture argument particularly convincing. At the same time, the accelerationist view of simply continuing to scale while assuming that nothing serious will go wrong seems reckless.
Your explanation closely matches how I’ve been thinking about the subject. The central question for me has always been: How long can scaling continue? It seems inevitable that it will eventually reach some limit. Compute, energy, data, infrastructure, and cost cannot scale indefinitely.
I’ve generally placed considerable trust in what researchers from the labs say publicly on X because their arguments have often seemed coherent. Still, I’ve always wondered whether they might be overlooking an eventual wall. At some point, training runs could become too large, too expensive, or too resource-intensive to produce worthwhile gains.
You mentioned the existence of new scaling laws. I don’t know how much internal evidence you have for them, and this remains the biggest unanswered question for me. Your post suggests that people inside the labs are fairly confident that further scaling laws exist and that the available evidence points in that direction.
As an outside observer, however, I find it difficult to judge how firmly established this is. Are these new scaling laws already supported by strong experimental evidence, or are they still informed hypotheses based on early results? If you can share more, I’d be especially interested in what evidence supports them, how reliable that evidence is, and what their likely limits are.
It still seems possible that progress could slow substantially if no further scaling laws emerge. Even if additional ones do exist, there presumably cannot be an unlimited number of them. Scaling must eventually encounter some kind of limit.
The key question, then, is when that happens. Based on your post, your view appears to be that it will not happen anytime soon. If that assessment is accurate, it also helps explain why several labs have recently sounded more concerned and spoken publicly about the risks.
The most important part of your post may have been the final caveat: models tend to perform poorly in areas where they have not been trained sufficiently. I’ve been reluctant to call Astra AGI because its capabilities are still uneven. If you use it long enough, you eventually find clear gaps. Those failures make the AGI label difficult to accept, even though Astra is highly capable and may already be superhuman in some areas.
Your point suggests that these gaps may reflect training coverage rather than a fundamental limitation. That is unsettling because it implies that a model could become superhuman in almost any domain if it receives enough suitable training in that area.
This could eventually produce a system that most people would call AGI. If Astra were as capable across a broad range of domains as it is in coding and mathematics, the remaining objections to that label would become much weaker. Continued training targeted at its weaker areas could gradually close those gaps.
The remaining question is whether models can actually be trained effectively across every relevant domain. Mathematics and programming are comparatively straightforward because outputs can often be verified automatically. Training is much harder in fields such as marketing, where quality is contextual, subjective, delayed, and difficult to measure reliably.
I’d therefore be interested in your view on two specific questions: Can these uneven capabilities be resolved mainly through additional targeted training, and do we have reliable ways to train and evaluate models in domains without clear, verifiable answers?
Thanks again for the insight. I learned a lot from the post.
Codex can now see how much of my account-wide token allowance is left. That gives the model a real operating constraint instead of an arbitrary number of minutes.
When a weekly reset is close and I still have budget, I can tell it to keep working on a task I already have in mind. If I don't, I can ask it to look through existing projects and work on something useful.
In both cases it watches for the reset and stops when it happens, so it doesn't use next week's budget. I can also give it a budget target: "You have X% left. Finish this before we reach Y%."
When I give Astra a broad UI task such as "make this production-ready," it doesn't stop after the obvious fixes. It keeps working through the little things until it considers the job done.
That makes it unusually useful. I can trust it to carry the whole thing across the line. It also makes planning harder: an assignment that sounds small can take much longer when completeness is part of the work.
If you hand an agent a broad quality task, put the definition of done, a time or budget limit, and a stop condition in the same assignment.