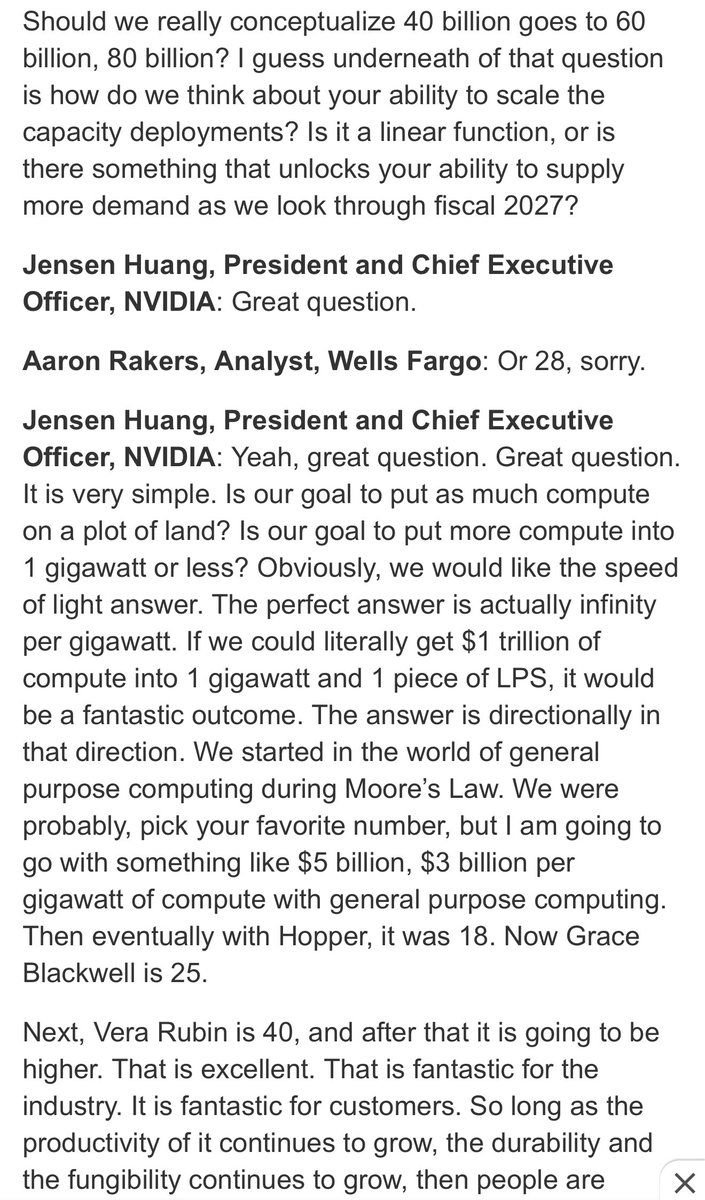
Jensen wants to put as much compute as possible on a plot of land. $NVDA
Jensen said;
"Is our goal to put as much compute on a plot of land? Is our goal to put more compute into 1 gigawatt or less? Obviously, we would like the speed-of-light answer. The perfect answer is actually infinity per gigawatt. If we could literally get $1 trillion of compute into 1 gigawatt and 1 piece of LPS."
Guess how it will be possible?
Only with major developments in memory and good progress in optics. $LITE $AAOI $MRVL
The whole scale-up has been possible only because memory capacity went from 8GB to 16GB to 32GB to 64GB to 128GB to 256GB to 512GB and so on.
If memory makers could provide 8TB or 16TB of HBM, NVDA would have paid any amount to buy it.
The only and most important bottleneck is memory.
I remember using an Android phone with 128MB of RAM. In the last decade we have progressed to 12–16–24GB of RAM.
That has been the single most important factor making electronic devices as fast as they are today.
$NVDA is compromising it's high-70s margins down to the low 70s just to keep up with memory.
In the past Jensen said any bottleneck doesn't last more than 3 years, but yesterday he said he underestimated memory demand and it will go higher in price next year and so on.
Memory still being traded as a cyclical industry just blows my mind.
$NVDA $MU $SKHY $DRAM $SNDK
Lmao!
Now the only reason left for Wall Street is that memory giants are already in the best possible situation, things can’t get any better than that!
Sometimes it sucks to be too good!
But if it keeps going, $MU will be able to buy back their whole company in a few more quarters with free cash flow, lol!
$DRAM $SNDK $SKHY
https://t.co/TdcWBx9gRA
Most dominant company, literally $NVDA said they will compromise their margins in low 70s from high 70s just beacuse of memory constraints and market still taking $MU down.
This has to be a joke!
$DRAM $SNDK
Most dominant company, literally $NVDA said they will compromise their margins in low 70s from high 70s just beacuse of memory constraints and market still taking $MU down.
This has to be a joke!
$DRAM $SNDK
I never even thought Korea has a Fed as well😭🤣🤣
Now we know why Korean memory stocks are trading at the same price they were before $NVDA earnings.
But these companies have so much cash on their balance sheets, higher interest rates might actually be better for them!
$MU $SKHY $DRAM
https://t.co/LkiDlfKqcn
$NVDA CFO on memory, supply and margins:
“We are experiencing extreme pricing conditions in memory. The magnitude of the price increase has exceeded our prior expectations and is headed even higher into next year.”
Nvidia expects supply to remain a bottleneck through at least the end of FY28.
Gross margins:
Q3: 74% ±50 bps
Q4: bottom at 71%-72%
FY28: settle around 72%-73% (Est. 74%)
“As executed price increases take effect in Q1.”
“Memory scarcity today is being driven in large part by the AI buildout itself... tighter memory supply is a symptom of the same demand surge that’s driving our own growth.”
$NVDA CFO on memory, supply and margins:
“We are experiencing extreme pricing conditions in memory. The magnitude of the price increase has exceeded our prior expectations and is headed even higher into next year.”
Nvidia expects supply to remain a bottleneck through at least the end of FY28.
Gross margins:
Q3: 74% ±50 bps
Q4: bottom at 71%-72%
FY28: settle around 72%-73% (Est. 74%)
“As executed price increases take effect in Q1.”
“Memory scarcity today is being driven in large part by the AI buildout itself... tighter memory supply is a symptom of the same demand surge that’s driving our own growth.”
Last quarter, Samsung had the most net income in the world after $NVDA.
Eventually, they will surpass that with guidance of accelerating even further ahead!
They are the backbone for memory foundry, Apple, and every major company in the world!
$SKHY $MU $INTC $TSM
https://t.co/XomKZ9czxD
I still don't get why Samsung is still so undervalued.
If OpenAI can come up with such a good chip with $AVGO using their latest LLM model, just imagine what Anthropic and Samsung could be cooking together!
There were reports that @AnthropicAI is partnering with Samsung to build its own inference chip.
Samsung is so ignored despite its incredible fundamentals.
Last quarter they had more net income than any other company in the world except $NVDA.
It still blows my mind.
@jukan05@zephyr_z9
$MU $SKHY $SNDK $TSM $INTC
They literally are the vertically integrated final boss!!!!!
https://t.co/f5TadTHP8f
I still don't get why Samsung is still so undervalued.
If OpenAI can come up with such a good chip with $AVGO using their latest LLM model, just imagine what Anthropic and Samsung could be cooking together!
There were reports that @AnthropicAI is partnering with Samsung to build its own inference chip.
Samsung is so ignored despite its incredible fundamentals.
Last quarter they had more net income than any other company in the world except $NVDA.
It still blows my mind.
@jukan05@zephyr_z9
$MU $SKHY $SNDK $TSM $INTC
They literally are the vertically integrated final boss!!!!!
https://t.co/f5TadTHP8f
What Jalapeño made me realize is just how much lower the barrier to chip design is going to become.
Ultimately, manufacturing will be where the real moat remains—at least until we have robots capable enough to change that.
Design and engineering outside of manufacturing will gradually lose their moat. Even when it comes to the semiconductors that form the foundation of AI.
That’s the feeling I keep coming back to.
BANK OF MEMORY controls everything and decides the fate of every entity
From 2022 to 2025, Nvidia was the center of the AI supply chain
Now, Nvidia has lost its perf/$ and perf/W crown, and memory bois are eating all the CAPEX
BANK OF MEMORY controls everything and decides the fate of every entity
From 2022 to 2025, Nvidia was the center of the AI supply chain
Now, Nvidia has lost its perf/$ and perf/W crown, and memory bois are eating all the CAPEX
Bro this fucking post is so fucking bullish memory!!!!!!!!!!
This fucking means bullish fucking $AVGO
And short fucking $CRWV & $NBIS
Every fucking chip maker is fighting for fkn memory allocation!
Even if the memory makers don't want that high margin they will just tell them all we only have this much memory and you all can decide who's willing to pay highest!!!!
What the actual fuck!!!!
$MU $SNDK $SKHY
More details on OpenAI’s Jalapeño chip from SemiAnalysis:
SemiAnalysis says Jalapeño is not narrowly optimized for OpenAI models.
It is a general-purpose inference ASIC, and in the workloads they tested it outperformed $NVDA, $AMD and Google accelerators on several inference efficiency metrics.
The chip was designed from scratch for LLM inference and went from initial team buildout to tape-out in roughly 16 months.
Performance:
• DeepSeek R1 exceeded 700 tokens/sec/user at concurrency 1
• Kimi K2.5 and GPT-OSS reached roughly 1,400 tokens/sec/user in selected tests
• Jalapeño achieved these results using single-token prediction, without speculative decoding or prefill/decode disaggregation
• SemiAnalysis says its output-token throughput per MW already exceeds the published July Vera Rubin results, despite Rubin using multi-token prediction
• On performance per total cost, Jalapeño and Vera Rubin are currently roughly comparable based on available results
These are still early benchmarks.
SemiAnalysis tested 8k/1k workloads and has not yet run its more demanding AgentX benchmark, which stresses long-context, multi-turn agentic workloads. Rubin is also already beginning to ship, while Jalapeño remains at the engineering-sample stage.
Hardware:
• Built on TSMC N3P
• 700W TDP
• HBM4 with 15.4TB/s of memory bandwidth
• SemiAnalysis says that is currently the highest memory bandwidth per package among shipping/near-shipping accelerators
• A0 silicon produced the current benchmark results
• B0 is already in the fab and is expected to improve perf/W by roughly 25%
• B0 delivers 13.4 PFLOPs of MXFP4 versus 17.5 PFLOPs of dense NVFP4 for a similarly sized Rubin compute die, but at lower power
Scale:
• 128 Jalapeño ASICs per rack
• Up to 2,048 XPUs can be connected across a 16-rack scale-up domain
• A complete host + ASIC rack pair consumes roughly 160kW
• OpenAI’s next deployment target is around 100MW
OpenAI is also using Codex heavily in the chip’s development. SemiAnalysis says AI-assisted design reduced SIMD area by 8% and matrix-engine area by 10%, while Codex has been used to write and optimize kernels for new models.
Production is expected to ramp gradually through 2027, with most output currently planned for Q4 2027.
Michael Burry will look so smart if he closes his Micron short and keeps the $CRWV and $NBIS shorts.
He will gain so much respect from thousands of people!
He will have so many good arguments. Seriously, who are neoclouds competing with? Hyperscalers, and that too with debt!
Long AI infrastructure bottleneck layer and short $CRWV & $NBIS
Best best risk to reward trade with ultimate hedge!
If we really don't need any of chips and memory and optics and energy providers then coreweave and nebius is definitely going to 0.
I can't think of a single scenario in which Nvidia $NVDA will get a positive reaction after earnings?
If they don't beat, the stock will tank badly, which obviously isn't happening.
If they beat and raise moderately, the stock will tank for not meeting crazy expectations.
If they beat and raise massively, the stock will pump and then tank on the thoughts that this kind of growth is just not sustainable at all.
What are they even supposed to do, idc about it, thing is it will take the whole market down with it!
$NVDA
Summary of CPO/NPO Market Update
🚀 NVIDIA CPO: Spectrum-X CPO switches for Scale-out are officially in mass production. Our forecasts: 15k units (2026E) & 100k units (2027E).
*Supply Chain: To support the CPO Scale-Out ramp, TSMC has expanded CPO inspection equipment capacity (notably adding Insertion 2/3 capacity), alongside strong progress from key suppliers in FAU, shuffle boxes, and system assembly.
* Scale-Up Architecture: Rubin Ultra is now expected to adopt a 9-18-9 tray design. While mechanical challenges from the 0.75U height could potentially lead to a reversion to a 10-9-8. This shift will have no impact on optical engine (OE).
📈 OE Shipments: NVIDIA platform optical engine (OE) shipments expected at 6m (2027E) & 19m (2028E). Total industry-wide OE hitting 11m & 40m.
☁️ Amazon Trainium 4: AWS projected to consume 5m (2H27E) & 12m (2028E) OE units, primarily 6.4T specs.
* Trainium 4 will likely have 3 configurations, with two expected to adopt NPO.
💡 Key Plays: LITE/COHR (CW laser upside), Browave (10k+ shuffle box per quarter in 4Q26E, followed by acceleration in 1H27E.), SMTC/MRVL (TIA/Driver), TSEM (NPO PIC exposure).
#NVDA #LITE #MRVL #SMTC #TSEM #Browave #CPO #NPO