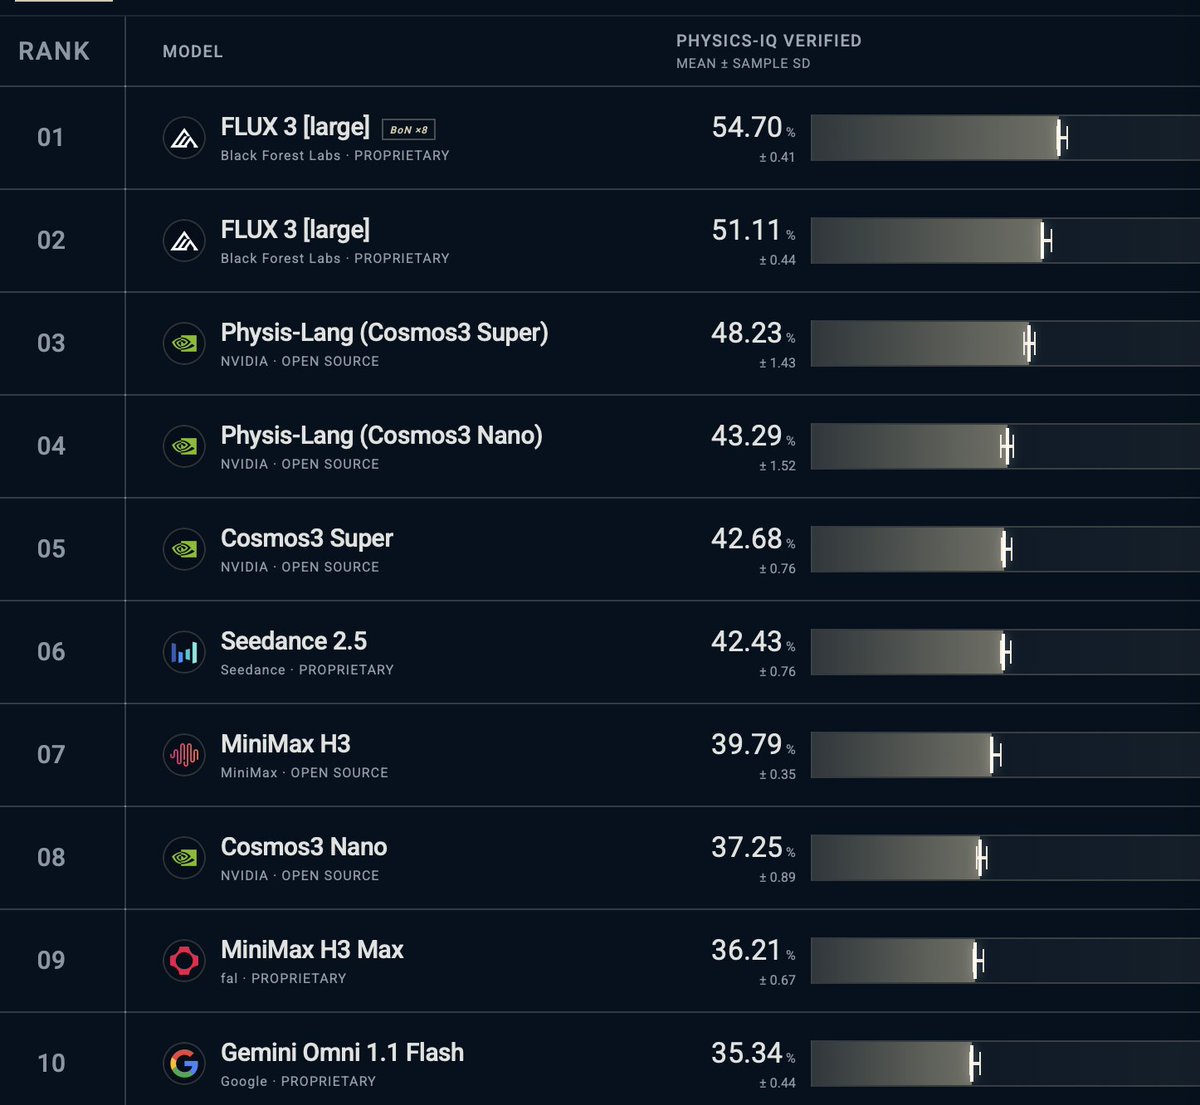
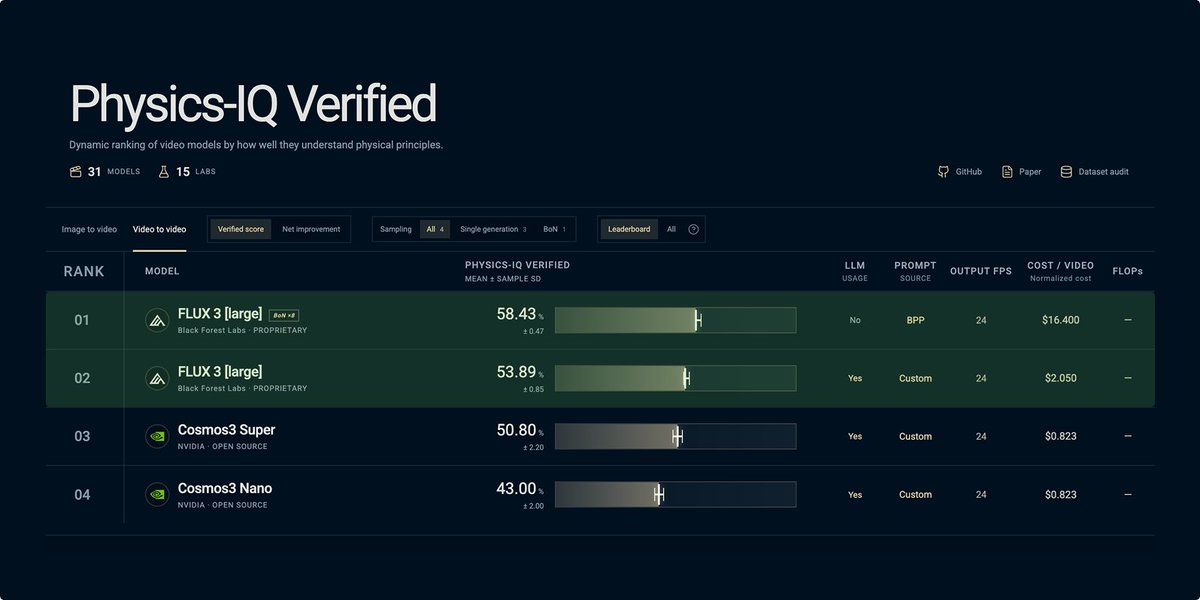
FLUX 3 is #1 on Physics-IQ, @GoogleDeepMind's benchmark for physical world understanding in video models.
How Physics-IQ works: given the start of a real filmed experiment, can a model predict what physically happens next? Tests span fluid dynamics, optics, solid mechanics, magnetism and thermodynamics, covering how liquids flow, light behaves and objects interact.
In most cases, we substantially outperform all other frontier models, Seedance 2.5, MiniMax H3, Gemini Omni 1.1 Flash, Veo 3.1 and Sora 2, Cosmos3.
The FLUX 3 base model outperforms all other foundation models, while FLUX 3 paired with a physics verification layer scores even higher.
The FLUX 3 backbone, with its strong physics understanding, gives FLUX 3 Action it’s strong action prediction for robotics, while also giving FLUX 3 Video physically accurate motion when you’re creating content, making ads, films and product shots.
"shocking" capability jumps in robotics always happen when someone aligns a robotics skill to another quasi-identical skill that existing frontier models already massively pretrain on
for llm-as-robot (astra), it's visual computer use
for real time dexterity (VAM/WAM), it's video pretraining
This new video model from @fal x @bfl_ai is remarkable.
All of these clips were text-to-video, generated in <10 seconds (22x faster than Seedance 2.5 🤯).
AI video no longer needs to be painfully slow and expensive. We're entering a new era!
Introducing FLUX 3 Max.
Fastest in the west. Fast enough to try anything. And everything.
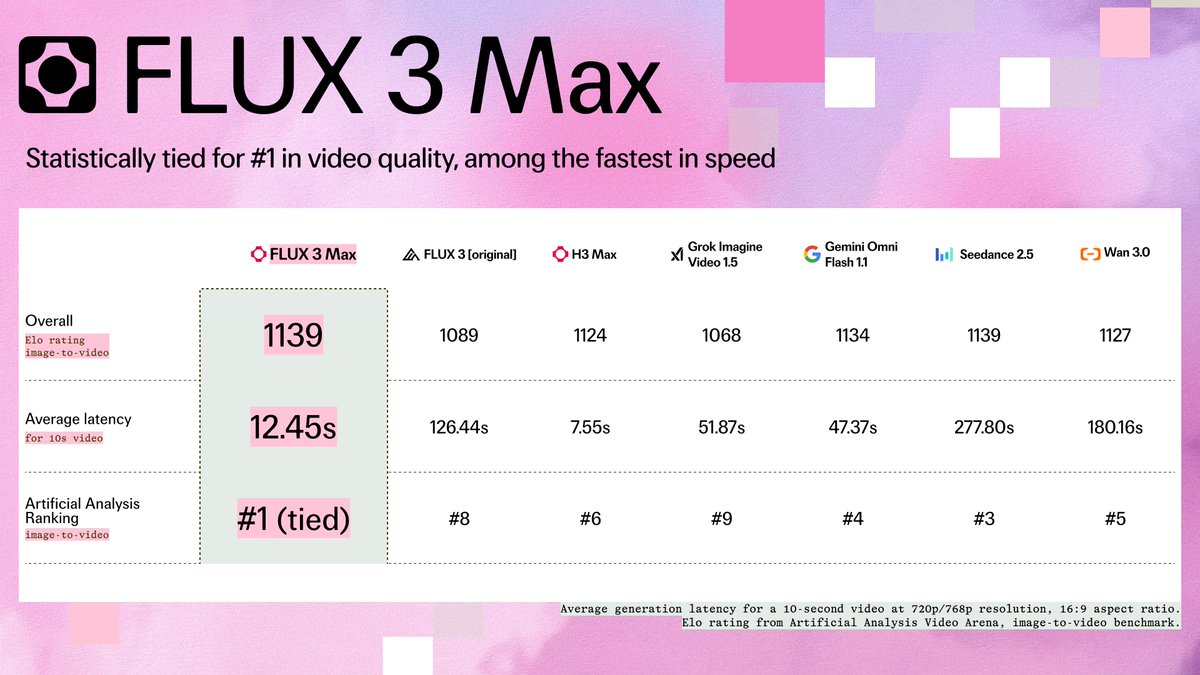
Generate a 10-second video in 12 seconds.
Tied for #1 in image-to-video. 22× faster than Seedance 2.5 at the same quality.
FLUX 3 is a model designed for customization. @fal adapted and optimized it to create FLUX 3 Max.
Introducing FLUX 3 Max, the latest post-trained video model from fal Research in partnership with @bfl_ai.
FLUX 3 Max is tied for #1 in image-to-video quality on independent third-party benchmarks, generating a 10-second, 720/768p video in ~12 seconds.
For the next three weeks, FLUX 3 Max is 75% off, making it the most affordable frontier video model at its quality level.
The most built-upon model on the Hugging Face Hub isn’t Llama or Qwen.
It’s FLUX.1-dev from Black Forest Labs, a German lab: 43k derivative models.
Europe trained ~8% of the open-model compute on the Hub, but ~18% of what people build on top of it is European.
Build or surrender? Build, and build open. See you at GTC Berlin this week
Should Europe leave frontier AI to the Americans and the Chinese?
The idea has gained ground in Europe. It is a fundamental mistake.
Build or surrender: for now, the choice is still ours.
Full article below. https://t.co/v1biuiXoYe