We’re thrilled to announce that Wispr Flow raised another $25M round after 10x'ing our revenue in just 5 months.
Our Series A2 was led by @hanstung at @notablecap (who was an early investor in five companies that made it to $100B valuation like Slack, Tiktok, and Airbnb). we also brought on @StevenBartlett as an investor and partner.
But here's what matters more than the money:
We cracked voice input. Not transcription - actual understanding. Our users hit "send" in under 0.5 seconds without checking. They trust it blindly. That's never existed before.
In a recent benchmark, Wispr came out as 3-4x more accurate than OpenAI, ElevenLabs, and Siri.
Voice input was step one. Now, we’re building the assistant that actually gets things done.
The keyboard had a good 150-year run.
Time to build what comes next.
PS: like, retweet, and bookmark to get wispr flow for free for 3 months ❤️
— Written with @WisprFlow
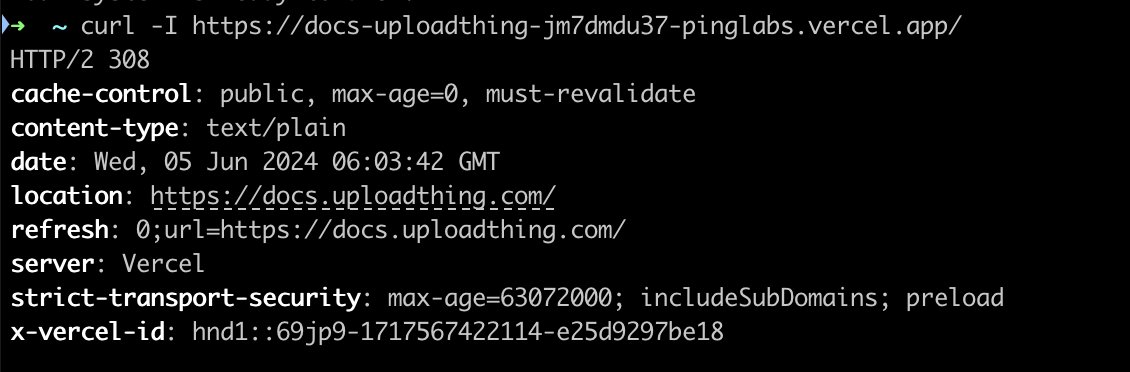
@t3dotgg Looks like you don't have a robots.txt, so you can ignore that. Adding the x-robots header to the response should solve this: https://t.co/Q6i5jl5FMp
@t3dotgg Some other posts come close:
1. set a noindex x-robots in the http response header.
2. Allow these routes to be crawled by Bings bots in your robots.txt
2b. IMPORTANT: don’t block the bots in the future again when this fixes the indexing problem (it’ll come back)
@chasewnelson@TaipeiCity What is up with people using jackhammers to redecorate their apartments? I don’t understand what they can possibly be using such noisy equipment for weeks and weeks. I’ve had this in every place I’ve lived here 😩
@MikeBlazerX You’re better off not blocking the Google bot in robots.txt. Instead serve the pages with either a noindex http response header or meta head tag.
This will ensure the page is not shown in search while allowing Google to read the content of the page and realise the links are BS
@MikeBlazerX Why are you blocking Google bot from reading those pages with robots.txt?
If there are external links to those pages they can still end up in Google’s results.
Google can’t read your content, so Google has to assume the content is related to the malicious links.
@jonoalderson Agreed. The tide is shifting (slowly) with JS frameworks that default to compiling html and css only (no JS by default) like https://t.co/htsfXa8hhR
And HTMX moving logic back to the server and sending html over the wire rather than json (who would have thought lol)