START THOSE ENGINES, JAPAN AWAITS 🌸🏎️
To celebrate the upcoming release of Forza Horizon 6, we're giving away 6 Premium Edition digital codes of the game. For your chance to win, follow @XboxUK AND:
💚 Comment for an Xbox Code
🔁 Repost for a Steam Code
Winners will be chosen on Friday the 15th of May
She dumped me last night.
Not because I don't listen.
Not because I'm always on my phone.
Not even because I forgot our anniversary (twice).
But because,
in her exact words:
"You only pay attention to the parts of what I say that you think are important."
I stared at her for a moment and realized...
She just perfectly described the attention mechanism in transformers.
Turns out I wasn't being a bad boyfriend. I was being mathematically optimal.
See, in conversations (and transformers), you don't give equal weight to every word. Some words matter more for understanding context. Attention figures out exactly HOW important each word should be.
Here's the beautiful math:
Attention(Q, K, V) = softmax(QK^T / √d_k)V
Breaking it down:
Q (Query): "What am I looking for?"
K (Key): "What info is available?"
V (Value): "What is that info?"
d_k: Key dimension (for scaling)
Think library analogy:
You have a question (Query). Books have titles (Keys) and content (Values). Attention finds which books are most relevant.
Step-by-step with "The cat sat on the mat":
Step 1: Create Q, K, VEach word → three vectors via learned matrices W_Q, W_K, W_V
For "cat":
Query: "What should I attend to when processing 'cat'?"
Key: "I am 'cat'"
Value: "Here's cat info"
Step 2: Calculate scoresQK^T = how much each word should attend to others
Processing "sat"? High similarity with "cat" (cats sit) and "mat" (where sitting happens).
Step 3: Scale by √d_kPrevents dot products from getting too large, keeps softmax balanced.
Step 4: SoftmaxConverts scores to probabilities:
"cat": 0.4 (subject)
"sat": 0.3 (action)
"mat": 0.2 (location)
"on": 0.1 (preposition)
"the": 0.1 (article)
Step 5: Weight valuesMultiply each word's value by attention weight, sum up. Now "sat" knows it's most related to "cat" and "mat".
Multi-Head Magic:Transformers do this multiple times in parallel:
Head 1: Subject-verb relationships
Head 2: Spatial ("on", "in", "under")
Head 3: Temporal ("before", "after")
Head 4: Semantic similarity
Each head learns different relationship types.
Why This Changed Everything:
Before: RNNs = reading with flashlight (one word at a time, forget the beginning)
After: Attention = floodlights on entire sentence with dimmer switches
This is why ChatGPT can:
Remember 50 messages ago
Know "it" refers to something specific
Understand "bank" = money vs river based on context
The Kicker:Models learn these patterns from data alone. Nobody programmed grammar rules. It figured out language structure just by predicting next words.
Attention is how AI learned to read between the lines.
Just like my therapist helped me understand my focus patterns, maybe understanding transformers helps us see how we decide what matters.
Now if only I could implement multi-head attention in dating...
Still waiting for "scaled dot-product listening" to be invented.
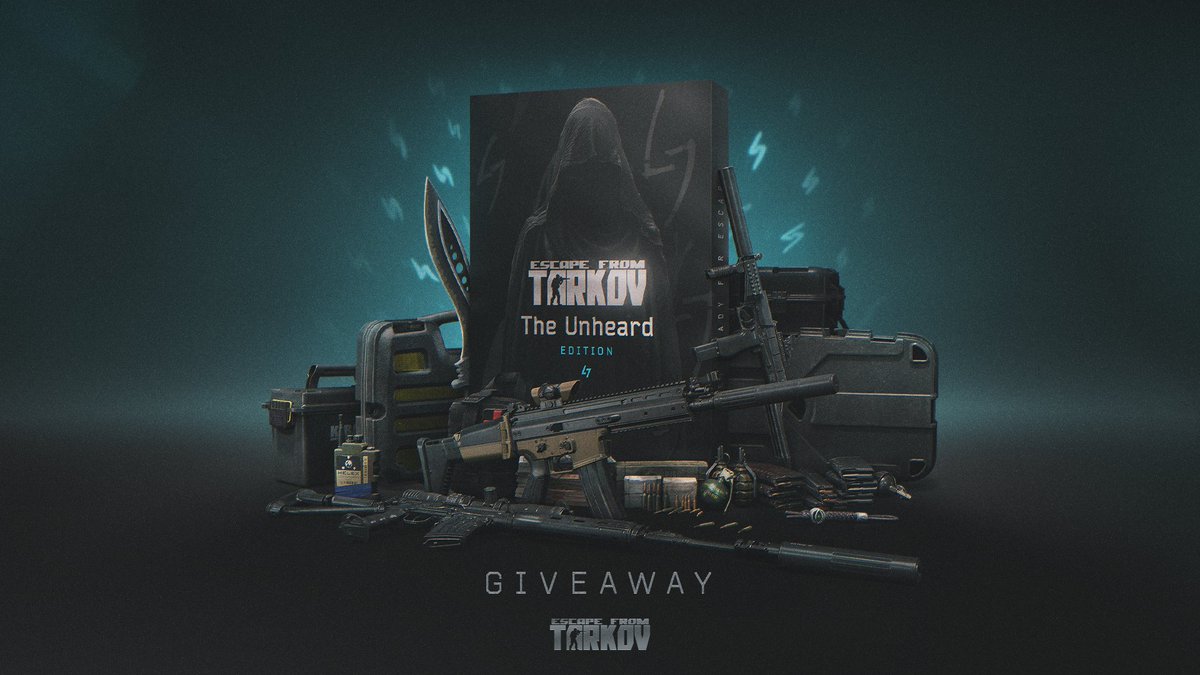
With almost one month since the release of #EscapefromTarkov we are doing the giveaway of 50 The Unheard Edition (EU edition) copies.
To participate in the giveaway follow conditions:
● Follow @tarkov account
● Retweet this post
● Share your most memorable Tarkov moment in the replies
Winners will be announced December 15