there is no replacing a founder like Jensen.
There never has been, and there can never be, a true succession for a founder like him. Nvidia ends today, and is replaced with a thing cosplaying nvidia. It will be run by custodians trying and failing to preserve the flame he ignited
We’re spending up to 100B tokens across 26,040 agent runs to answer one question: when you switch models, should you switch harnesses too?
Our v1.0 FrontierHarness leaderboard ranked harnesses on a single model.
V1.1 expands it to 21 harnesses × 5 models × 62 tasks × 4 attempts, 72x the size of v1.0.
Results are coming in live. Link below🧵
I've been blown away by the energy, optimism, and hard work that has created the China I've seen on this trip. It had been seven years since I was last here, and it might as well have been forty. Invigorating to see what's possible. The West has no excuse for its managed decline.
🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 https://t.co/JGAik1kgk0
1/4
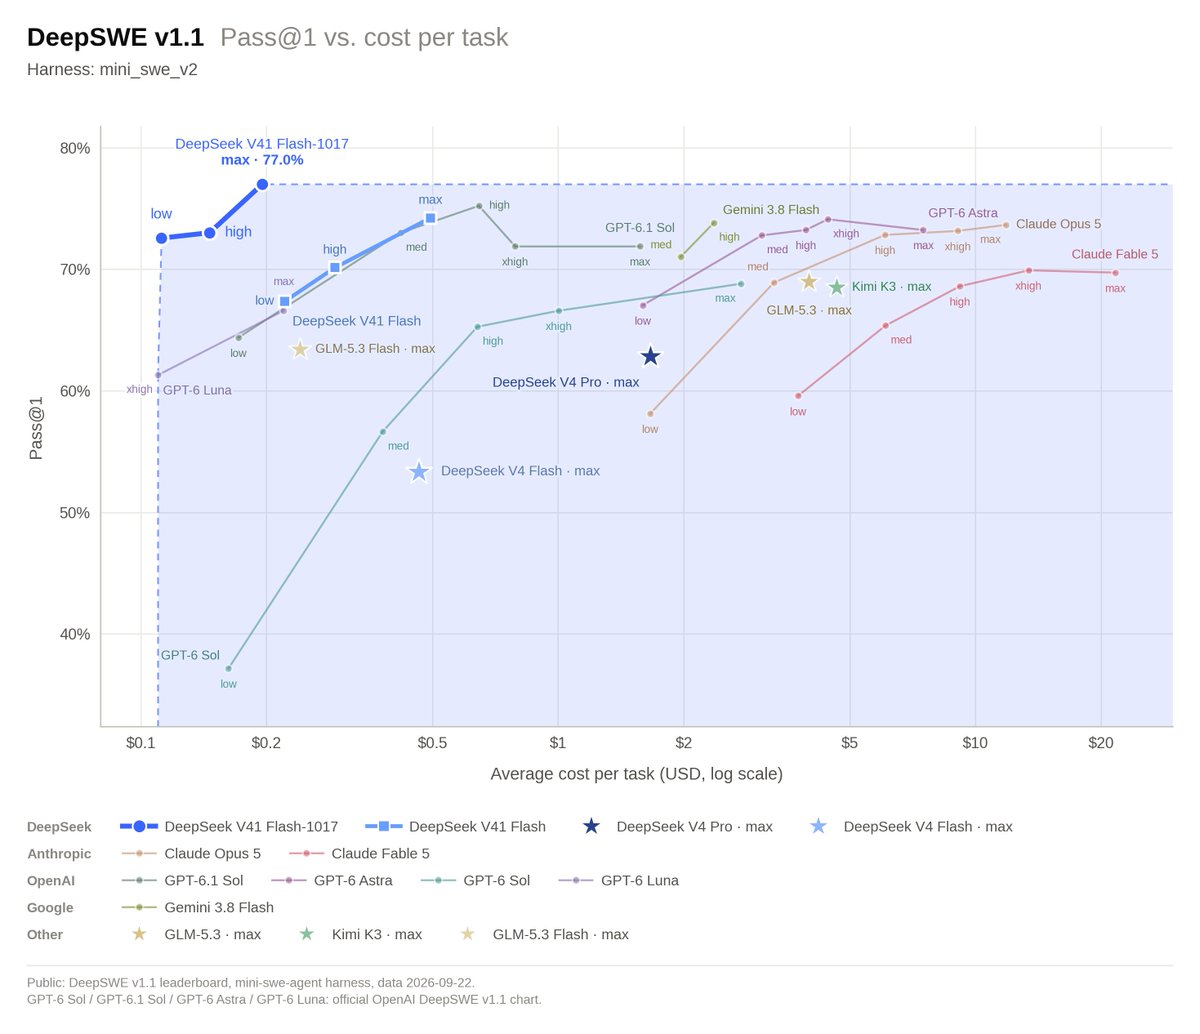
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
The official IDA MCP Server is here. It's free, open source, and works with any LLM.
Your agent writes IDAPython, uses ~20% fewer tokens, and can share an IDB with you in real time.
𝚞𝚟𝚡 𝚒𝚍𝚊-𝚑𝚌𝚕𝚒 𝚖𝚌𝚙 𝚒𝚗𝚜𝚝𝚊𝚕𝚕
https://t.co/jXPiF6Wyvk
(copy-paste: uvx ida-hcli mcp install)
🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient.
🔹 Introducing the smallest model in our new architecture family, with native visual understanding.
🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models.
1/6