@superalesha when I made the video; i had not tried the engine.
I used it overnight and it worked great for me, matching your 3090 numbers on my 3090 Ti
Inkling is very verbose and very strong
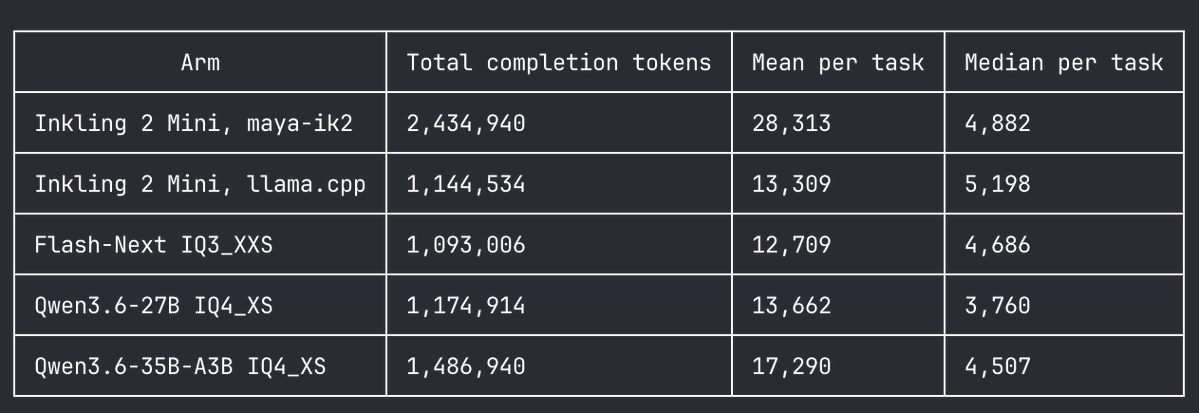
INCREDIBLY VERBOSE. 26k average per task on medium reasoning vs. 12k for QFN
re-ran overnite with engine by @superalesha getting 110-130 tokens/second
2x timeouts;2x token gen limit (65k).
it matched QFN (at huge time cost). INSANE
@RandomU24441@superalesha put it this way. if you have 100GB of combined RAM/VRAM.
You can choose to use QFN and be done in like 4 hours, or Inkling 2 Mini, in 7 hours
but yeah maybe other reasoning settings can be more sensible.
I only ran it on my 86-task C/C++/Python/JS/bash bench
yeah so, if you let this thing cook for hours and hours and hours, it's actually very very smart
Also use Alexey's engine/Maya fork i had great results on an overnight run with it
Inkling 2 Mini is about the strength of 35b-a3b. But much slower, with poor day-1 support on llama.cpp.
Maybe @superalesha 's custom engine could help. https://t.co/SS7QJl0JFb
Review is on YouTube or my website because twitter limits me https://t.co/JjE0QTDfCS
I built a custom engine for Inkling 2 Mini and pushed a SINGLE RTX 3090 to 129.5 tok/s with 344K context.
2.3x faster decode and 3.7x faster prefill than llama.cpp with ZERO quality loss.
With 48 looped layer passes and native NVFP4 weights, llama.cpp crawled at 57 tok/s and fired ~7,350 kernel launches per token. Over half the decode time went to tiny 1 to 2 us glue ops.
So I built maya-ik2 on @PeasantSmith Project Maya with all 3,072 experts resident in VRAM, cutting 7,350 launches down to 781 in 1 CUDA graph. Then I wrote custom Tensor Core kernels for both FP8 KV attention (776 GB/s) and NVFP4 experts. RTX 3090 has no FP4 hardware at all, so the expert kernel unpacks 4-bit weights to FP16 in registers on the fly and feeds FP16 Tensor Cores at 745 GB/s.
Moving BF16 vision to CPU (4.5s new image, 0.5s cached) freed 1.3 GB VRAM for 344K context, and I wired up a working thinking-off toggle too.
1x RTX 3090 (300W, Unsloth UD-Q4_K_XL, FP8 KV):
Short: 128.7 tok/s decode (129.5 HTTP) vs 57.0 in llama.cpp
4K: 124.2 tok/s decode, 2,742 prefill (vs 1,052)
64K: 105.6 tok/s decode, 2,361 prefill (vs 42.7 / 630)
128K: 90.6 tok/s decode, 2,079 prefill
340K: 62.3 tok/s decode, 1,473 prefill (23.57 GiB peak VRAM)
Didn't lose quality either: 74/96 on GSM8K vs 73/96 on the scalar path (5.7e-5 KL). Cleaning up the commits for GitHub now, and there's still room to push this quant to ~135 tok/s.
https://t.co/PZIJP7WSjy
In short it looks like my first run severely penalized it for being verbose, AND slow. BBW Alpha is designed to do this, it has strict limits on task wall clock time.
Need new evals to judge this model
not switching to it yet, but its peak intelligence is remarkable
This is not a sensible spot on the pareto curve yet. We need to find one for it, probably with a much lower reasoning setting.
It's possible that if you are severely restricted in GPU resources, this is the best choice if you ask it your task and walk away for a day.
from my agent: "The longest was 40,907 tokens, on the first call of patmatch-rules: 113,016 characters of reasoning followed by one tool call, taking 303 s at 135 tok/s. That task scored 10/10."
local doing 40k in one generation is an antipattern. or so i thought.
now this graph isn't "fair" because I gave Inkling every advantage under the sun to see what it's capable of, and I'm glad I did.
This nearly 10x'd the amount of tokens it could generate on a single turn, through throughput and limits and time. Inkling used it.
token usages:
the other 4 dots are BBW Alpha, strictly:
* 86 tasks
* 4090
* 15 min or 30 min per task
* pi 0.85.1
* same system prompt
so in order for Inkling to shine it needed three advantages (token gen limit increase, optimized engine, increased timeouts)
@shawshank_rat my benchmark is quite saturated; with like 70% of the tasks being easy for both 35b and QFN. this makes the relative differences small.
the remainder of difficult tasks are sensitive in my experience.
this is a valid criticism tho