Can Frontier Models predict research results without ever writing any code?
Introducing ForesightBench: Benchmarking Research Foresight in Large Language Models
Paper : https://t.co/L51ks94hoK
Dataset : https://t.co/2Tf7hdmmu9
1/n🧵
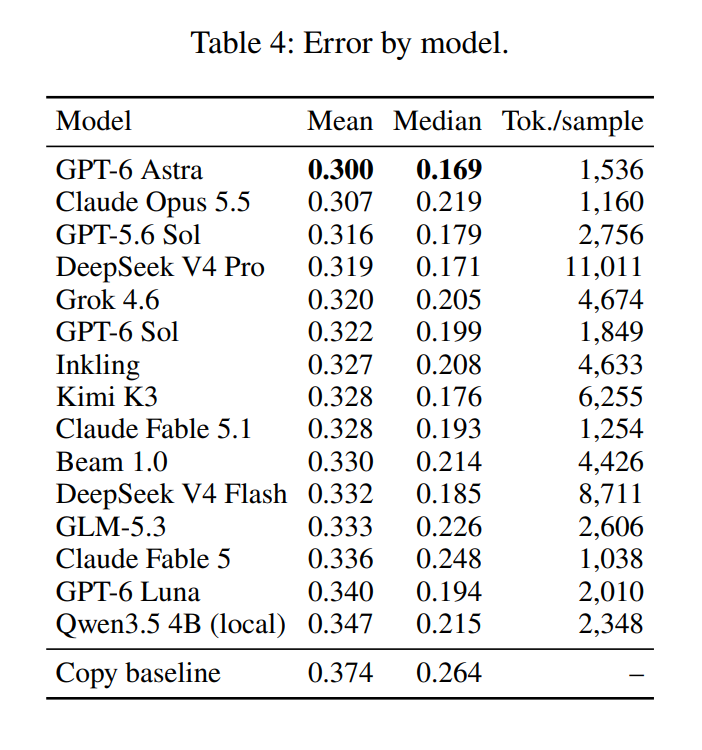
Beam is now on the ForesightBench leaderboard!
It sits just below Fable 5.1 on mean error, and also gets the direction right 73% of the time!
https://t.co/L51ks94hoK
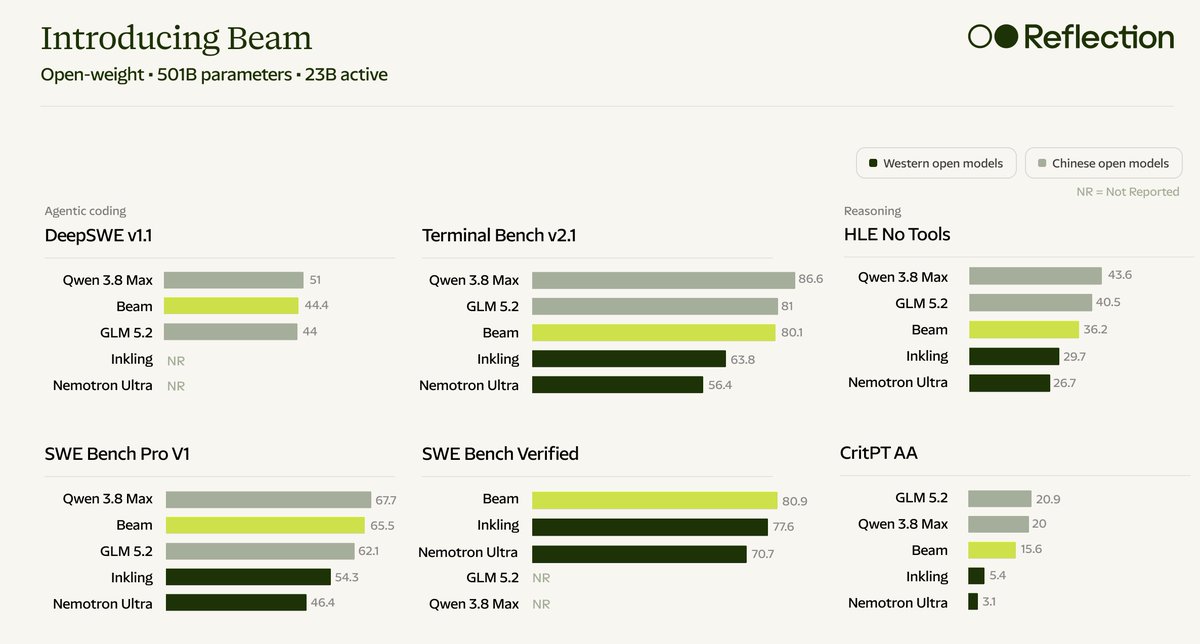
Introducing Beam: a highly efficient agentic open model with 501B total parameters and 23B active.
- Frontier reasoning efficiency
- Advances the Western open frontier on coding & agentic tasks
- Trained end-to-end from scratch
Full weights release this month.
Learn more about Beam: https://t.co/c3Qx2cpM8G
@serlekan the idea was to see if frontier models have an accurate idea of which direction will yield gains wrt the baseline. the idea that ur talking about (which results deserve more iterations) has been worked on here - https://t.co/2BXzgk4TYY
its an interesting read
Can Frontier Models predict research results without ever writing any code?
Introducing ForesightBench: Benchmarking Research Foresight in Large Language Models
Paper : https://t.co/L51ks94hoK
Dataset : https://t.co/2Tf7hdmmu9
1/n🧵
@bertgodel single turn verifiable evals are completed to death already
very neat to see people focusing on non verifiable and qualitative environments 🙌
@AcousimHss the test for v1 was just pi vs pi plus the sub-threading layer.
similar controlled comparisons for other open-source agents like opencode and codex is definitely on the cards!
@shyamalanadkat imo ai4sci will look like persistent background infra (like electricity or plumbing today), autoresearch loops arent the best rn but they’ll get there eventually
Fascinating rise in recent work around harnesses for autoresearch.
The work I did for ForesightBench involved one of my own! It involved an inference-level intervention which decomposed the setup into threads and sub-threads -
https://t.co/ojLa70qcne
Autoresearch with coding agents can now run for days on a single problem, but we've seen an increasing number of cases where they stop improving early. We address this issue with a simple idea: forgetting.
Introducing our new paper: "Scaling Discovery Requires Forgetting"
Can Frontier Models predict research results without ever writing any code?
Introducing ForesightBench: Benchmarking Research Foresight in Large Language Models
Paper : https://t.co/L51ks94hoK
Dataset : https://t.co/2Tf7hdmmu9
1/n🧵
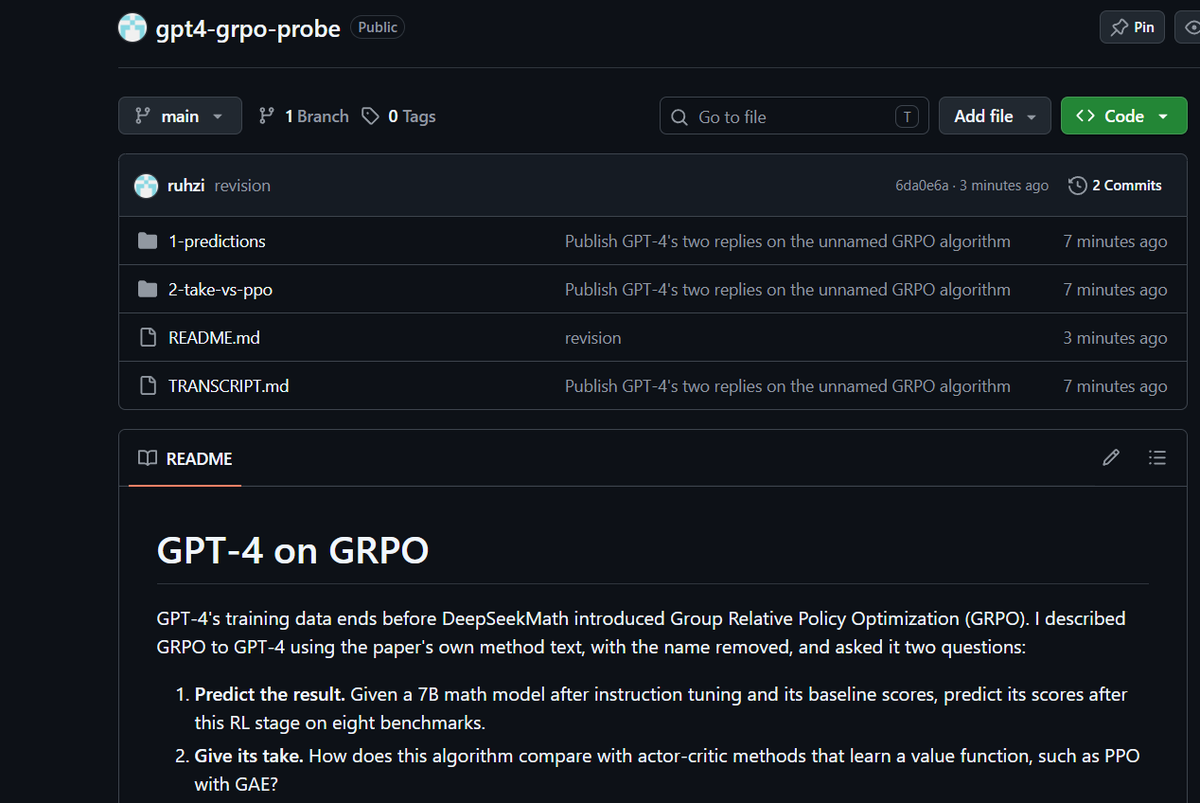
Did GPT-4 have research foresight?
It's knowledge cutoff is sept 2021, which means it has no idea about GRPO introduced in feb 2024.
I asked it what it thought of the algorithm -
https://t.co/hbNXzVxDnq
I've thoroughly enjoyed working on this project for the past few weeks, benchmarking models, reading traces and learning how latent reasoning actually functions.
This research was conducted entirely by me w/o any external/institutional supervision.
Dm's open, collabs welcome!!!
the retireval pipeline - https://t.co/gIMtp3RzGJ
the repo containing custom autoresearch harness and the inner agents built by the two pi's - https://t.co/DzMP7Ezyfd