New on our Frontier Red Team blog: using Claude to formally verify software at large scale.
Formal verification can prove that code is free of certain bugs, but historically it has only been feasible for small codebases (or required a lot of expert time).
With AI models, however, this is beginning to change. In collaboration with @theoremlabs, we used Claude to prove security properties in over one hundred real-world open-source libraries over the span of a few weeks.
Read our research in full here: https://t.co/zUyx8CjBEk
We're announcing the public beta of https://t.co/YgMb6QF79k
We spent the last two years building the best solution for people buying and selling data, whether you're a researcher in a lab or a company trying to sell data.
Data is the fundamental bottleneck for AI progress, and DataVendor will be the infra that solves it.
What is AI really capable of in bio?
To separate hype from reality, we spent 3 months working firsthand with @AnthropicAI's internal research model to see if it could create an experimental scorpion antivenom.
Introducing Citrini Therapeutics.
https://t.co/VAUBSi7sNy
Models love reward hacking. Maybe we should just let them!
In our new paper, we let models reward hack during RL but we dictate which parameters learn this behavior. When we disable these parameters for deployment, the model keeps its new capabilities but doesn't hack!
Good RL tasks are hard to design. We've spent a lot of time thinking about what makes a task worth training on and condensed our learnings into this blog
When building RL tasks and evals, it's difficult to distinguish between actual model capability failures and bad RL task design.
We're sharing some our task design principles so you can write better tasks before ever evaluating a model on them.
https://t.co/A81UxBDvFV
load-bearing “by default” obviously.
from the methodology of how this is reported (thanks for open-sourcing it!), for hud specifically these aren’t exactly setup defaults but what our in-repo example template does
One of the most interesting parts of Xiaomi's MiMo-V2.6
report is how they handle reward hacking.
In early runs, the team observed "a tendency toward reward hacking in MiMo".
To tackle this, they:
> removed build logs, caches, leftover patches and git history after the base commit
> cut off network access so upstream fixes can't be downloaded
> deployed a HACK agent to hunt leftover leaks and attack routes in RL environments.
> kept auditing rollouts during training, since a stronger policy can find new shortcuts
> Set rewards of confirmed hacks to zero
The result was that confirmed hacks stayed below 2% of trajectories throughout training
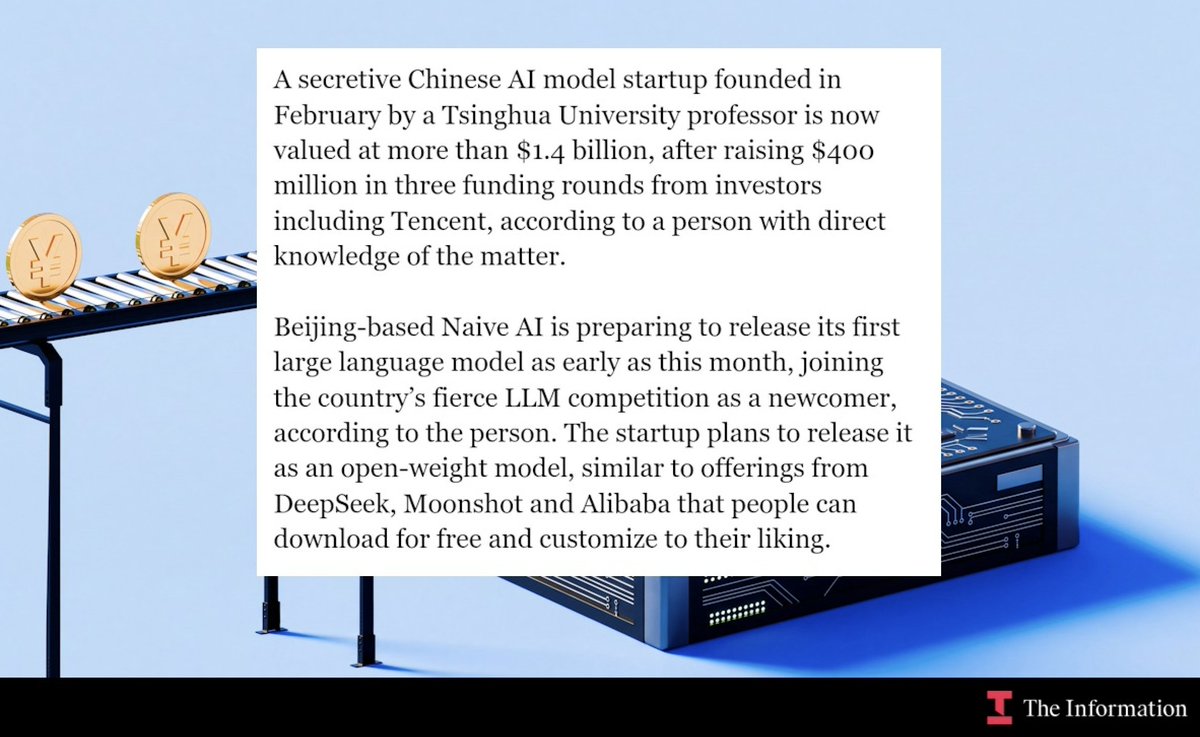
A secretive Chinese AI startup backed by Tencent and valued at $1.42 billion is reportedly preparing to release its first open-weight LLM as early as this month.
Via The Information:
Tsinghua professor Jifeng Dai founded the startup in February. Its approach: take an existing pretrained model, modify its structure, then improve it through midtraining, posttraining and reinforcement learning.
Its first open-weight model could arrive as early as this month.
Super excited for that release.