@investwithpaul AI is solving problems around Navier–Stokes, generating production code and reasoning across entire systems and some interviews still obsess over syntax on a notepad. The world moved on. Test architecture, debugging, tradeoffs and judgment, not who memorized systax.
@investwithpaul This is crap. I work professionally as an AI engineer, solved 200 LeetCode problems in python, yet I can’t write an API from scratch. My latest project is TypeScript—I barely know variable syntax, but shipped 25K LOC to prod with no tester found bugs. System design > syntax shit.
@uday_devops - your coding agent
ask it to run curl commands (fastest way).
add instructions to Agents.md or CLAUDE.md “when running curl, save the command and response to an md file; when the same command runs again, update the existing response”.
@TheodRRRe It happens because contamination of existing context and sometimes new chat can help to tackle at first place.
Tbh I hate Claude models most people hype them, I always use GPT they are good at instruction following.
@praneethreddy33 1.Use lm studio it exposes openai compatible api end point and point to codex with .codex/config.toml
2. Easy setup
> ollama pull < model >
> ollama launch codex-app
This opens a new codex window and allows you to select open models which are located in your machine.
@shinichikudou48 @Varun_369 Yeah they are first introduced reasoning for text generation with O1 model which a big breakthrough followed by deep seek R1 and also first one to introduce reasoning for Image Gen as well.
@Varun_369 @shinichikudou48 Yeah , web-search helps a lot here while generation, but not sure they do web search for image generation like they do for text generation.
Unlike other image generation models GPT image generation models do reasoning before generation.
@Varun_369 @shinichikudou48 LLMS don’t remember facts they learn patterns and store as parameters,
Models don’t know the next scene, it predict next scene, you might not get same results again.
If I’m not wrong the reasoning behind it will be knowing the actor and background and predict what asked user for
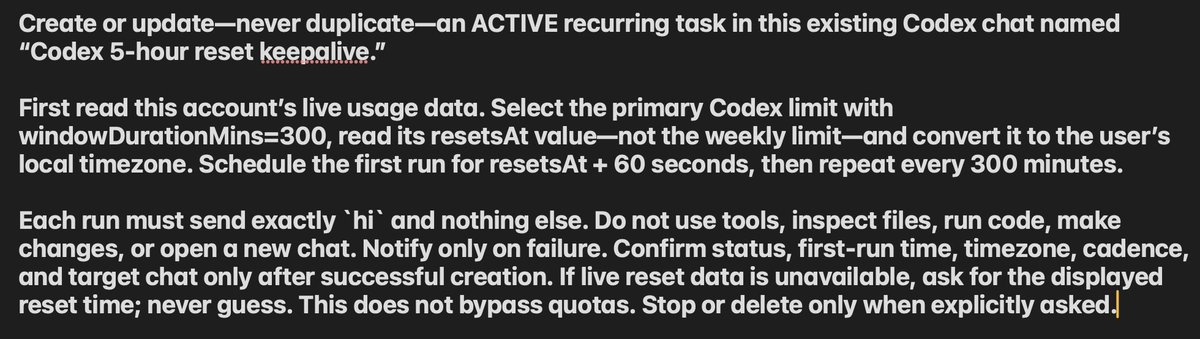
Problem: Codex’s rolling 5-hour limit is easy to miss when the reset happens while you’re away.
Solution: Paste the prompt in the image into ChatGPT Work. It checks your live reset, then sends hi in the same chat after each reset, every 5 hours.
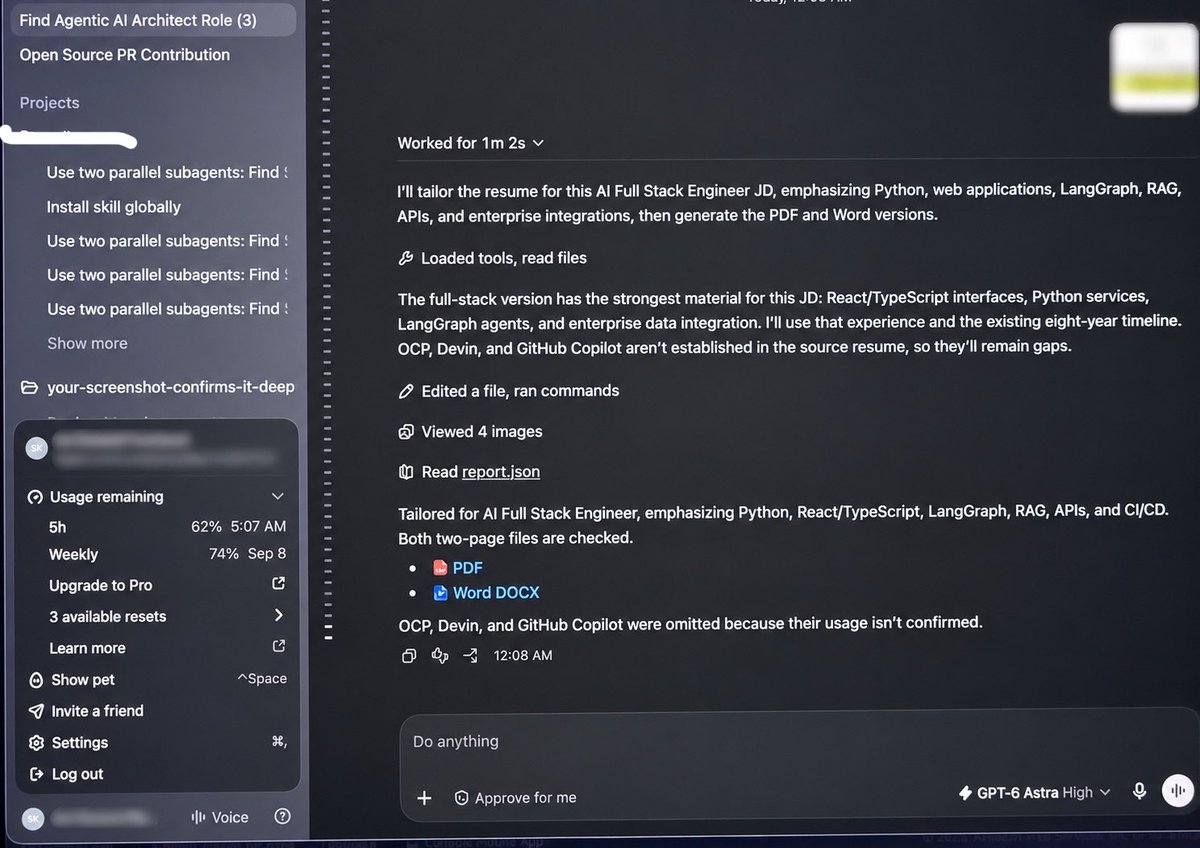
Sharing my astra experience
For 1 tailored resume
Luna (max) consumes less than 1 % in fast mode
Astra (high) consumed 38 % in fast mode
Luna took 5-7 minutes
Astra took 1 minute.
Astra is crazy fast at completing task but at expensive if you are in 20 dollar plan
@SD__Tweetz0 Why our telugu people are so obsessed with this tweet, all this can be done with previous generations models as well but this has better harness and OpenAI hyped more about it
@amitiitbhu Problem: Follow-up breaks
Solution: Rewrite the latest query using the last 3 turns to preserve intent and context. Exclude recent answers from rewrite.
Problem: Irrelevant chunks
Solution: Use similarity-score gaps between chunks and drop chunks below the relevance threshold.
@thsottiaux
Temporary Chats are great for thinking out loud. The problem is some evolve into projects worth saving. Give us a “Save as Chat” button that turns a Temporary Chat into a persistent conversation without losing context.
Want this so badly.
Ordered a double protein @ChipotleTweets and didn’t even get a proper scoop for either serving. Paying extra for double protein shouldn’t mean getting less. Do better.
@thsottiaux
Temporary Chats are great for thinking out loud. The problem is some evolve into projects worth saving. Give us a “Save as Chat” button that turns a Temporary Chat into a persistent conversation without losing context.
Want this so badly.