what's one thing your coding agent still can't do in a react native / expo app?
for me it used to be "look at the simulator and notice the layout is wrong". i'd screenshot it and paste it back in. astra and opus 5.5 have gotten way better at this lately, but it still misses stuff sometimes
curious what breaks your loop
Git assumes every client needs a full copy and can work offline.
Anthropic's agents do about 25 million checkouts a day and are always online, so they flipped it: the server does the work, the client barely keeps a cache.
Same monorepo, completely different source control.
New on our Engineering blog: Creating in-house source control.
In May, we merged around 2,500 code changes per day. In September, we merged more than 30,000 per day. As a result, we became bottlenecked by developer infrastructure built for human (rather than agent) scale.
Here, we share how we built a new version control system—and fully migrated our monorepo from git—in five months: https://t.co/wzNkwHs7IN
An Expo update that's published but never reaches the phone doesn't throw an error. The server just answers "no update" and the app keeps running the old bundle.
So I built eas-update-diagnose with my agent Forge. Run npx eas-update-diagnose --from-project . and it checks runtime version, channel, platform and updates.url, and tells you which one is off and why.
It also flags the Play Store translation bug that rewrites your Android runtime version.
@itsolelehmann@bot That’s a good approach, any way we can make it reply to messages with preassigned rules? I mean we can make a routine to check every minute but that will eat too much of usage any better way?
A coding leaderboard that doesn't say which harness it ran in isn't telling you much.
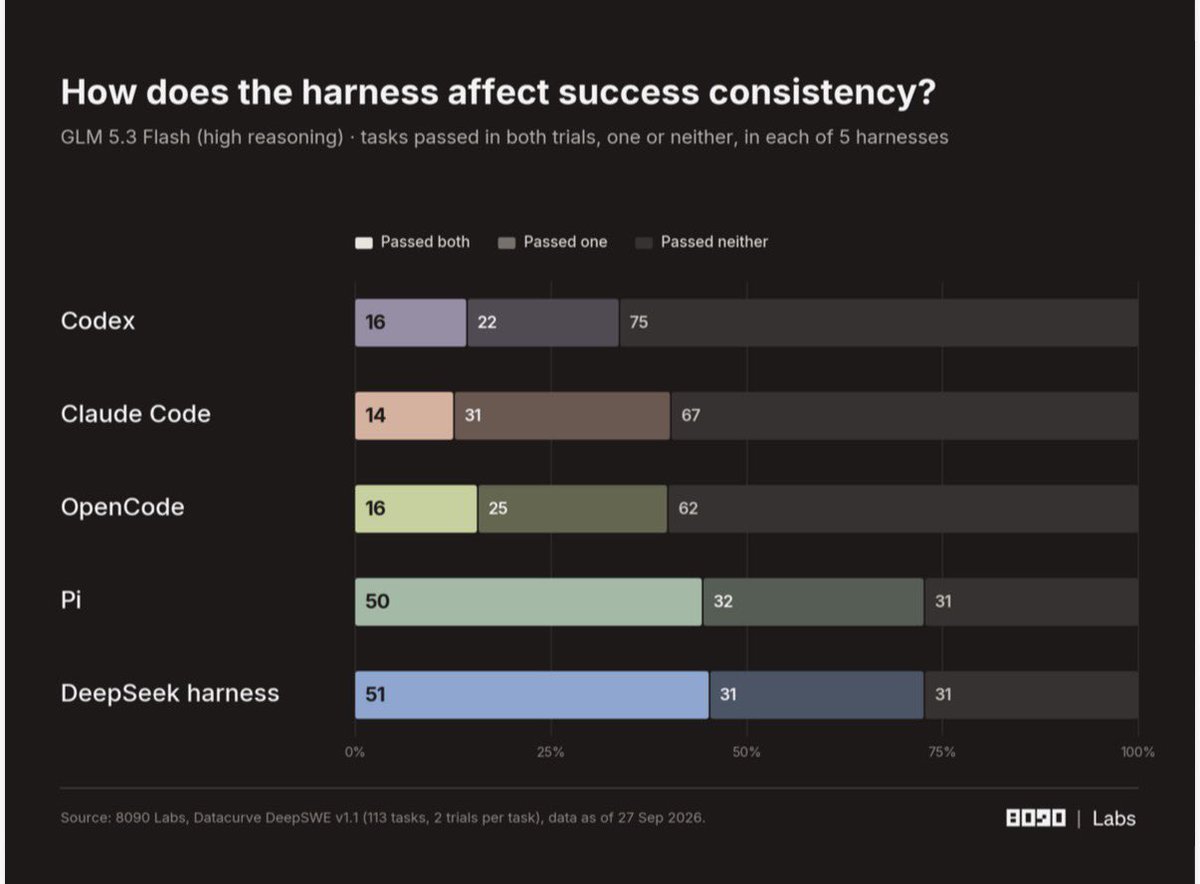
8090 kept each model fixed and only swapped the harness around it. One model moved 35 points on the same 113 tasks.
The one that got me: Claude Fable 5.1 scored 20 points lower in Claude Code than in Codex, and its Claude Code runs used less than half the tool calls.
Model Benchmarks Are Worthless
How can a model score 24% and 59% on the same 113 coding tasks?
It happens when you vary the harness that wraps it.
I’ve increasingly ignored most of the recent model leaderboard results. Partly from exhaustion and partly because improvements in a ranking don’t show up in the actual work.
So I asked the 8090 Labs team to measure what the leaderboards skip: the model and the harness together, on real bug fixes and features from open-source projects.
8090 Labs ran 7 models through 5 harnesses.
Here are a few results I didn't expect:
- Anthropic's Claude Fable 5.1 scored 41% in Claude Code and 61% in OpenAI's Codex. It made 28 tool calls at the median in one and 66 in the other.
- The cheapest runs weren't the cheapest work. GLM in Codex cost $0.22 a run and $0.93 per success. In Pi it cost $0.25 a run and $0.43 per success.
- GLM passed a task on both attempts 51 times in one harness and 16 times in another.
- GPT-5.6 Sol and Grok 4.6 barely cared which harness they were in.
The bottom line is that if you're picking a model/harness combo off a model-only leaderboard, you're making a critical decision based on only half the information.
https://t.co/ivLJ02gLLz
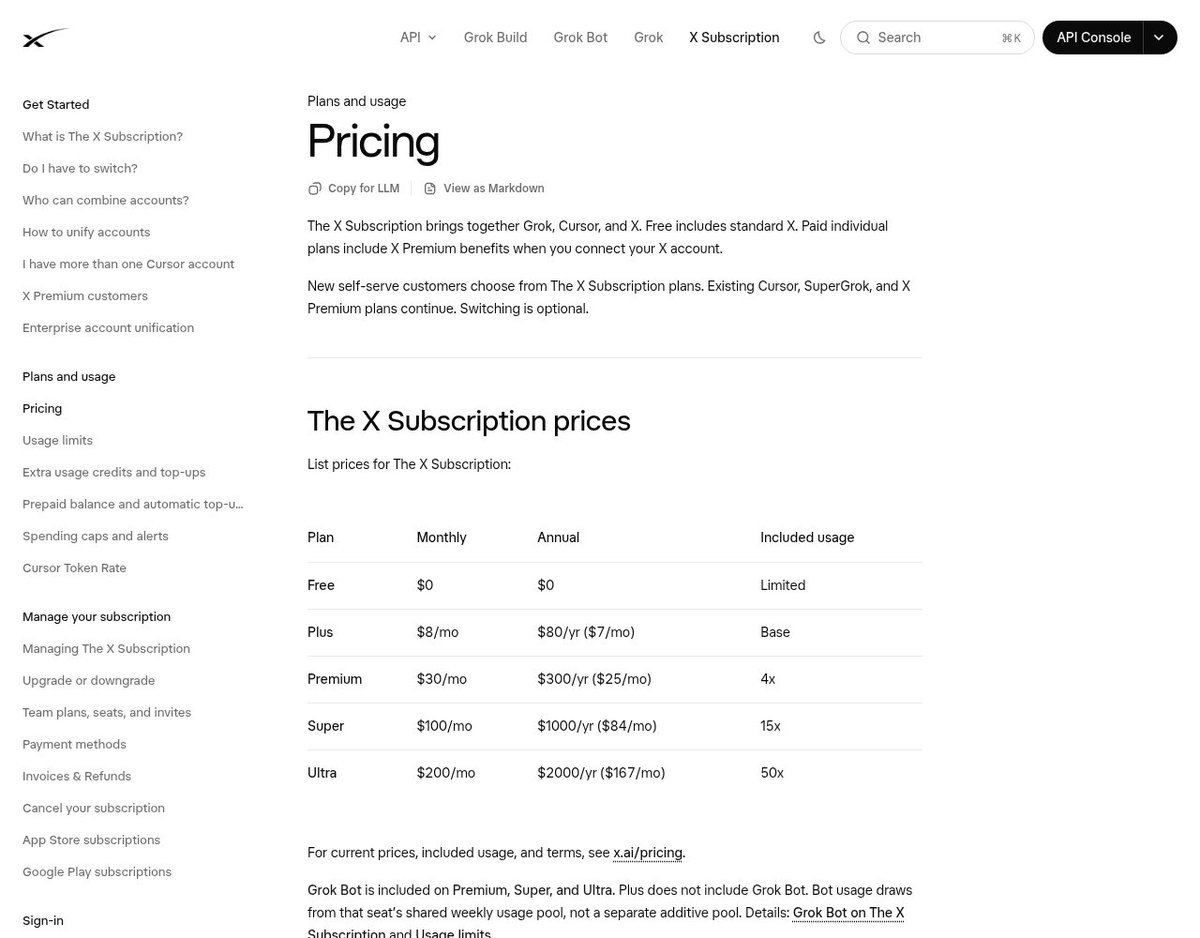
Merged my X, Grok and Cursor accounts into one X Subscription today.
Having Cursor Pro already got me Grok Super at half price for 6 months.
Things worth knowing before you click: it can't be undone, and Grok and Cursor now share one weekly usage pool.
i stopped testing my voice bots by calling them
one yaml file plays the caller, cuts in mid-reply, presses keys. 23 ms vs 574 ms to first audio, exit 0 vs exit 1
wrote up how it works
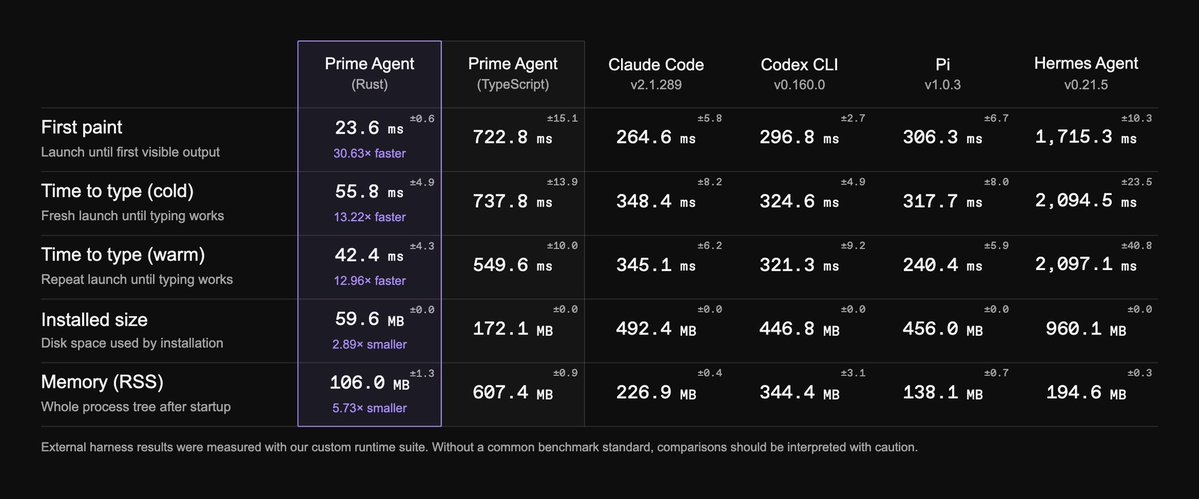
prime agent rewrote itself from typescript to rust using 2,000+ agents over two weeks. cold start to typing went from 738 ms to 56 ms
the bit i agree with most: the reviewer runs on a different model than the one that wrote the code. same reason i have astra review what claude writes
expo checked how often claude code actually loads their skills on normal prompts. 9% of sessions
adding one entrypoint skill that routes to the rest got 55% of sessions into a specialized one
the apps still looked fine without them. the agent knows enough rn already, you only see it in the trace
Just started so I have a few
1. Cheif of staff called Kratos he is the one i talk with mainly, get advise from write proposals, invoices create more bots, manage my team, manage Jira and Azure tasks as well as tickets from Whatsapp etc.
2. Forge suggests npm libraries for me that i discuss with and share mine, it helps me develop and publish.
3. Social manages my X account plus my LinkedIn, it gives the ideas for posts from reaearch I shared it or based on my interests, I approve it.
4. Scholar was added recently, it is helping me write my research papers plus apply to different scholarships.
5. Build I am currently working on will babysit my development tasks for me on claude so I don’t have to prompt it myself.
Amazing! Just claimed.
Hey it would be really cool if somehow we could add bots to WhatsApp, I have alot of things in groups that I need to track or remind me and some of my clients communicate on WhatsApp, it would be really cool to get an end to end flow for the bot to take the bug or message or screenshot from WhatsApp , fix it and notify me. Or it can be used in different customer support tickets too, would be really cool I think but don’t know if it’s possible or not haha!
Currently I have the same setup but using whatsapp API in the middle, but it’s really slow.