@cdomingoenrich@randall_balestr In the embedding geometry, scaling the text encoder improves uniformity but worsens image-text alignment. Modality-specific weight decay recovers alignment while preserving uniformity.
📄 https://t.co/ubQ4ycaTdp
💻 https://t.co/p4hOS7XSa0
🤗 https://t.co/sEj2iQdF5W
Bigger CLIP isn't always better. 🧵
The vision↔text split is usually an unexamined design choice. We trained 30 CLIP models, scaling each encoder independently, and evaluated downstream performance on 40 datasets.
with @cdomingoenrich and @randall_balestr
@cdomingoenrich@randall_balestr We trace the degradation to modality-specific overfitting: past a point, growing the text encoder lowers training loss but hurts zero-shot. The fix: modality-specific weight decay. More decay on the text than the vision recovers every degraded config; the reverse hurts.
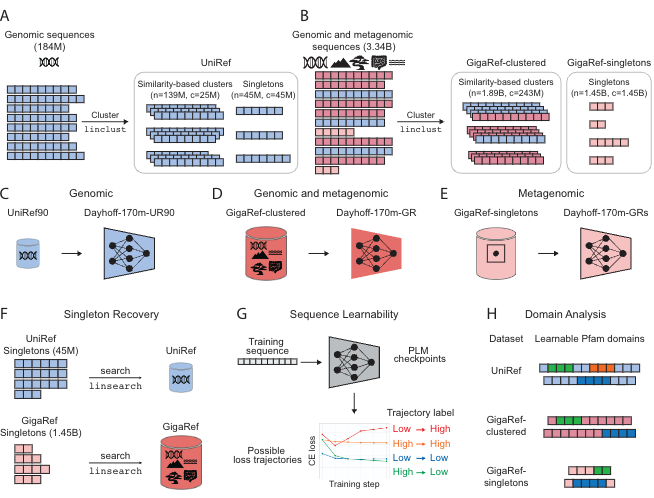
When training protein language models, people usually discard metagenomic proteins that don't cluster with at least 1 other protein (singletons).
With @riavinod_@Samir_char@avapamini@lorin_crawford , we show that this is probably not the right strategy.
@mckaywrigley Even if the next models "solve" software, does anyone know how users and companies will support all the massive inference cost required for a new and sustainable paradigm? Would profits be enough to dedicate full data centers to LLMs instead of other use cases (e.g., cloud, ads)?
You have until Dec 1 to apply to the bioml PhD research internship!
This is where you apply to work with me, @alexijielu@avapamini@lorin_crawford or Kristen Severson!
(new) link and some instructions below
At Chicago Booth to speak about our recent JEPA research! We need more researchers from all fields to join our efforts and to keep pushing for better JEPAs, LeJEPA is only the V0.
single-cell models tend to learn from the many - and miss the rare
we introduce an Adaptive Resampling approach to help models learn from underrepresented cells, improving generalization & discovery
https://t.co/CIpAW1RwWA
https://t.co/xfCc13dMe5
great work by @NavidiZeinab!
Are you a PhD student interested in machine learning and biology or health? Come do an internship with me, @avapamini, @alexijielu, @lorin_crawford, or Kristen Severson at @msrne!
Applications are due Dec 1: make sure you include a research statement!
https://t.co/HfyZshDtof
The last few months have been devastating for LLM dreams:
• Apple reasoning paper and the ASU mirage paper and many others confirmed that LLMs still can’t solve distribution shift.
• GPT-5 came late and fell short.
• Turing Award winner Rich Sutton thanked me for my critiques of LLMs and agreed.
• Karpathy just said agents aren’t anywhere close, and that AGI is a decade away.
• And Hassabis just blew up some wildly overhyped claims from OpenAI about math.
Game over, man.
LLMs have their place, but anyone expecting the current paradigm to be close to AGI is delusional.
@karpathy@karpathy It would be amazing to learn how you manage the learning vs shpping tradeoff. How you balance coding from scratch and without looking at other code vs just borrowing implementions from others. It will help others create great repos like yours!