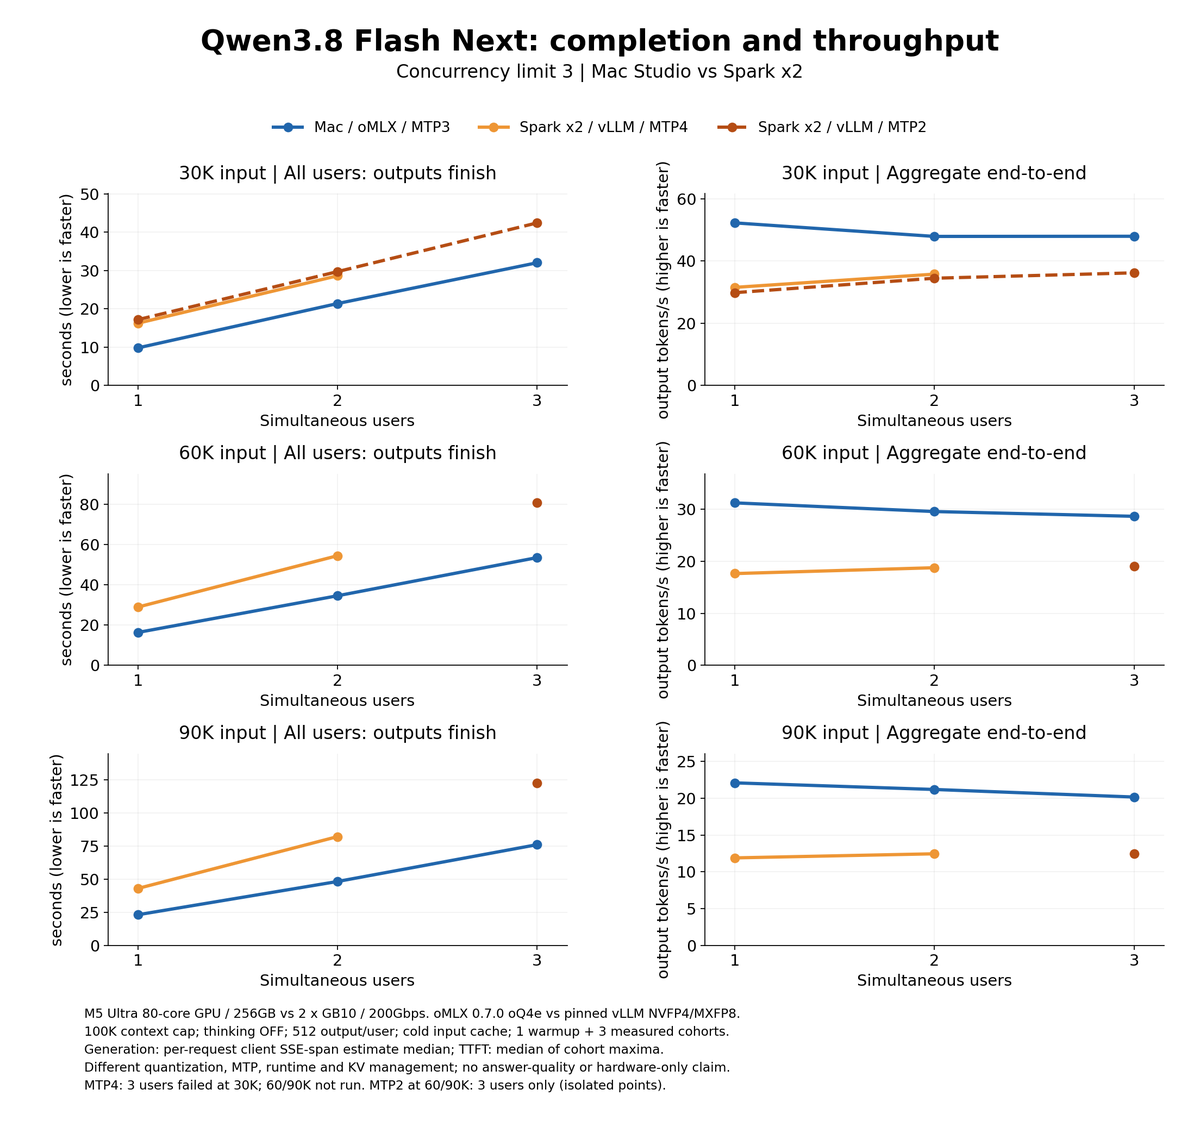
You asked about concurrency, so here we go! 😅🔬
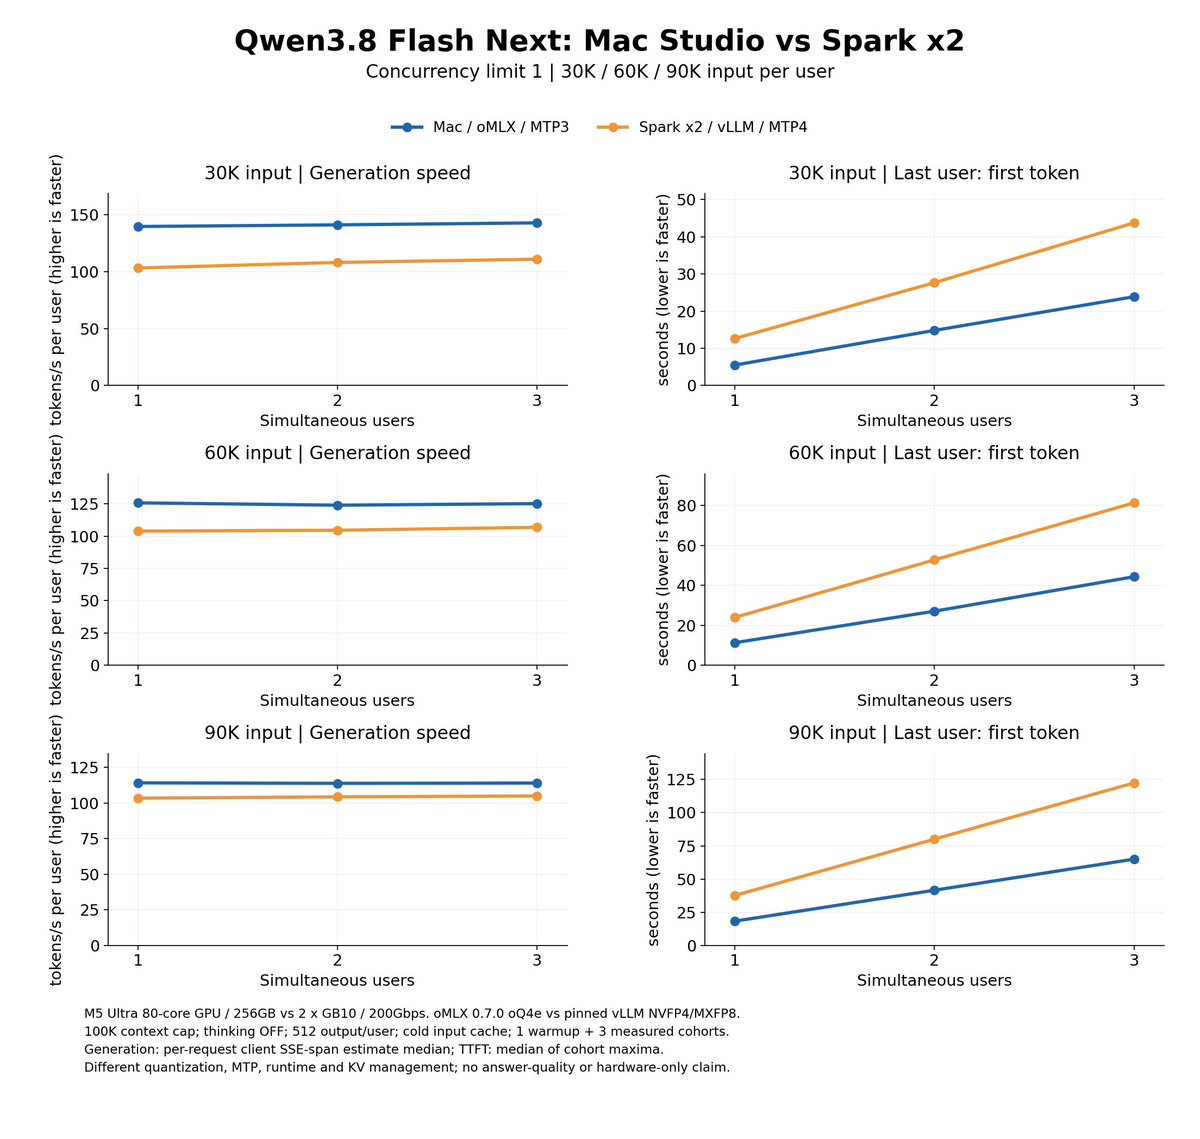
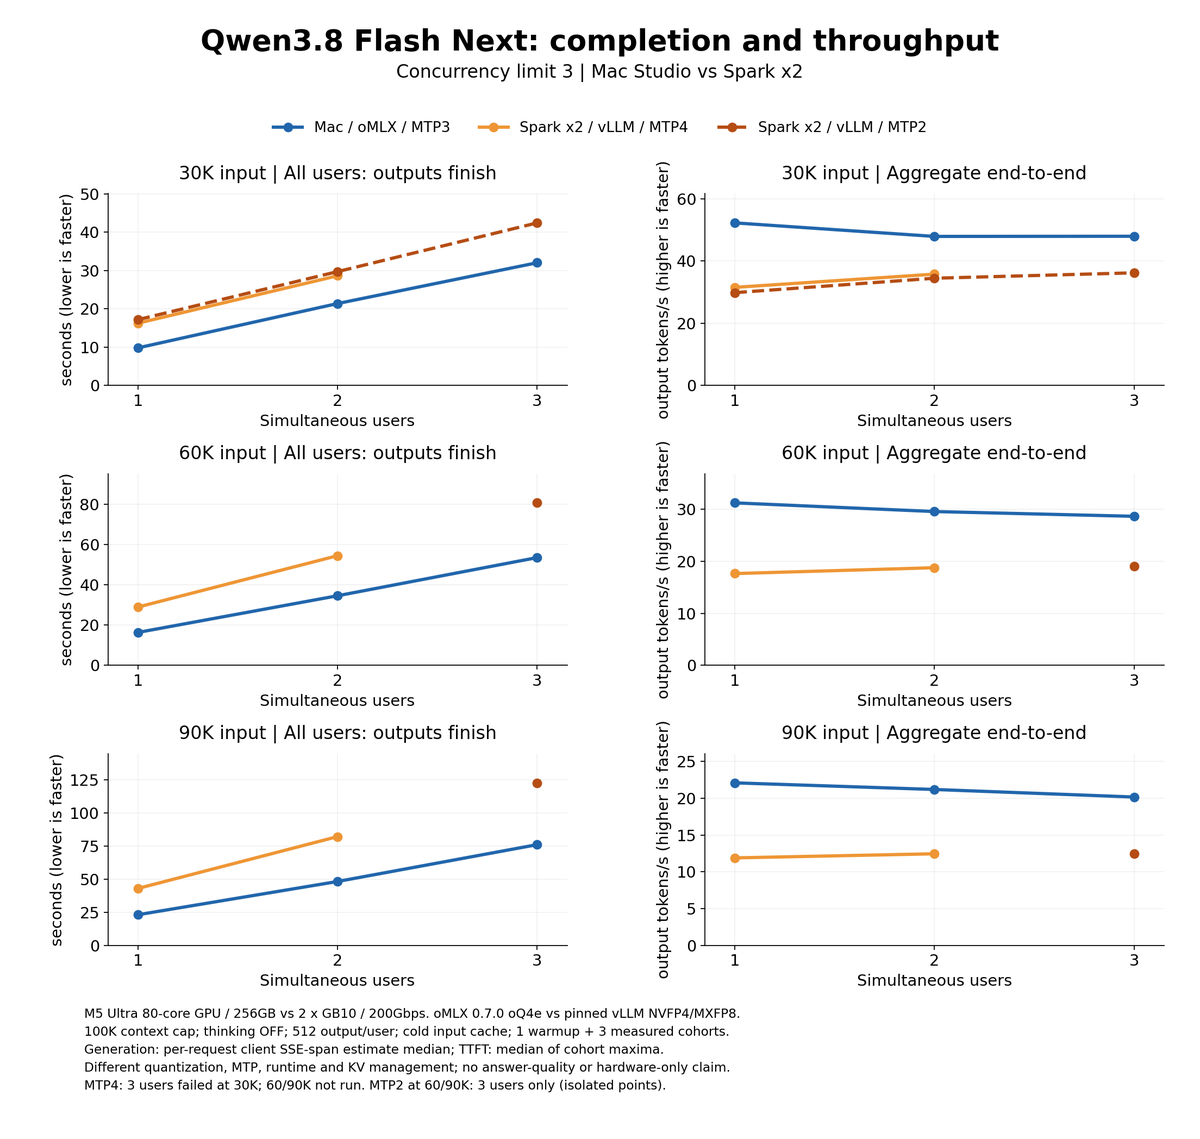
Qwen3.8 Flash Next on Mac Studio M5 Ultra vs dual DGX Sparks.
First, concurrency limit = 1.
With 1–3 users, per-user decode speed stays steady. But requests queue up, so the last user waits longer.
Fast generation, long queues!
@ivanfioravanti Interesting hypothesis!
We pushed the Mac Studio to 6 users, but haven’t tested the dual Sparks beyond 3 yet.
We’ll probably revisit higher concurrency when our Spark cluster expands to 4 units.
For now, I think the GPUs deserve a little break! 😅
@SabatinoMasala Thanks for the heads-up! 😊
I checked NVIDIA’s guidelines, and apparently they recommend a whopping 40 cm of clearance behind the Sparks! 😳
There’s more space than it looks in the photo, but I’ll definitely keep an eye on thermals.
Really appreciate the advice!
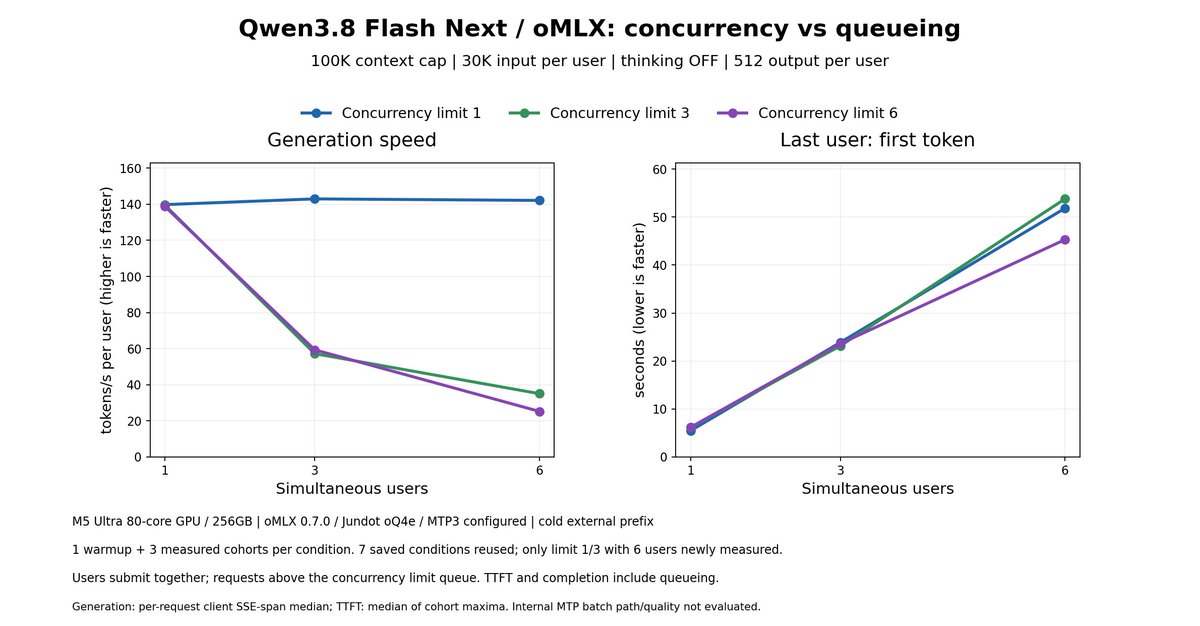
You asked for higher concurrency… so we tested 6 users! 😅
Qwen Flash / oMLX on M5 Ultra (30K input each).
At 6 users, c=6 gets the last user's first token sooner than c=1 (45s vs 52s).
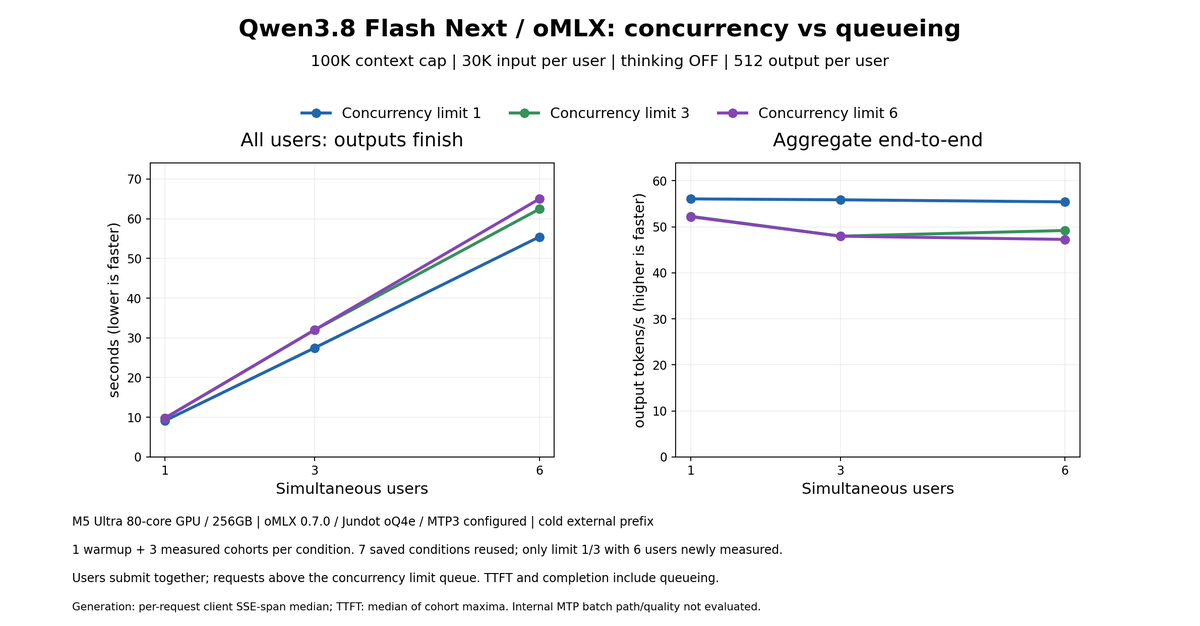
But completing all 6 requests takes LONGER (65s vs 55s)!
More concurrency ≠ faster overall!
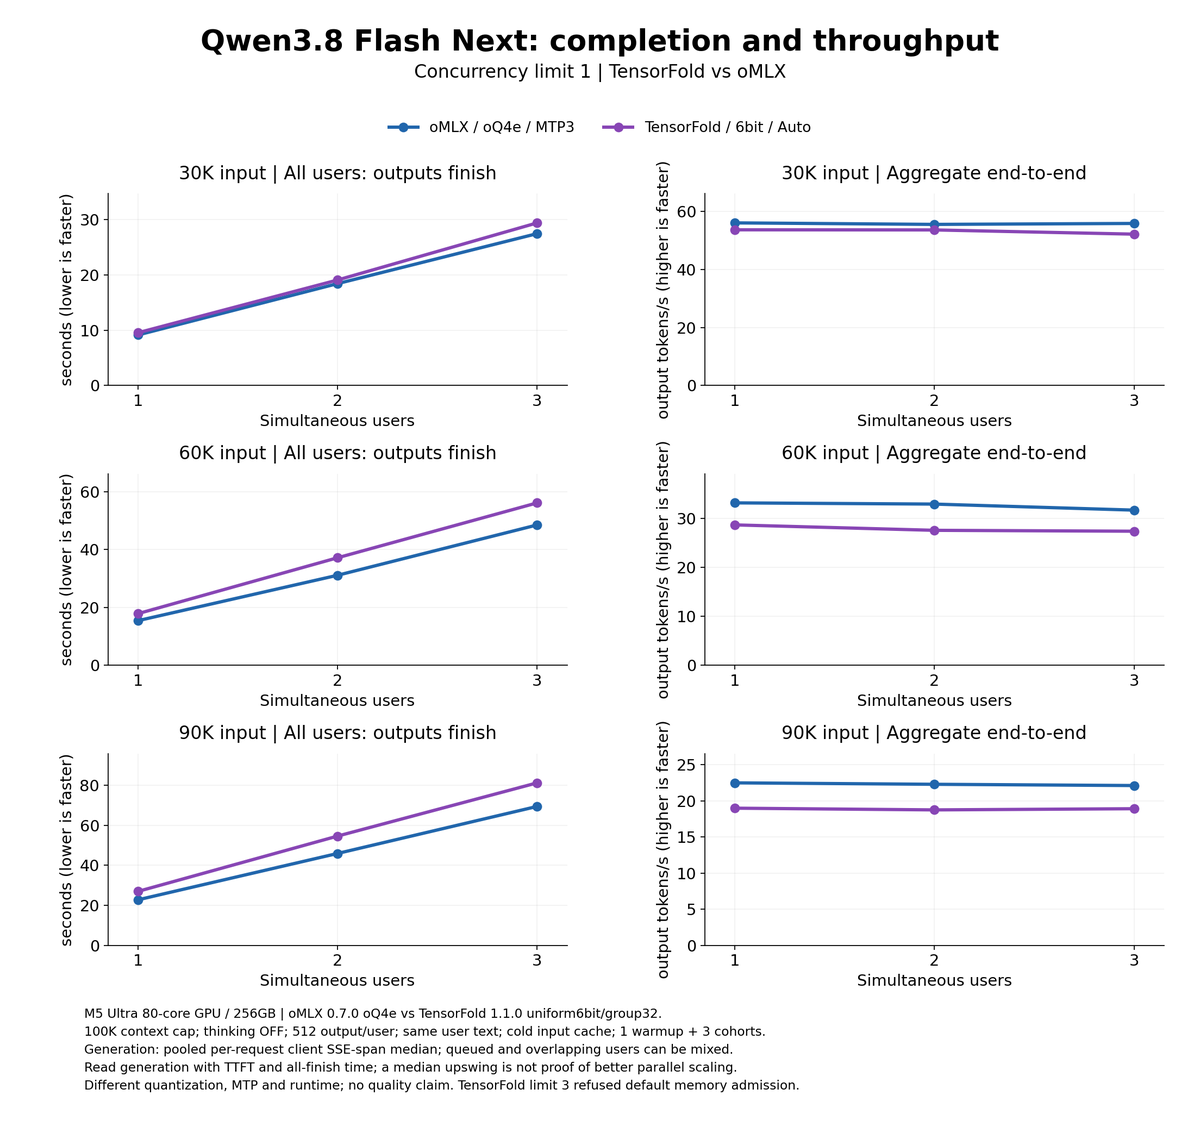
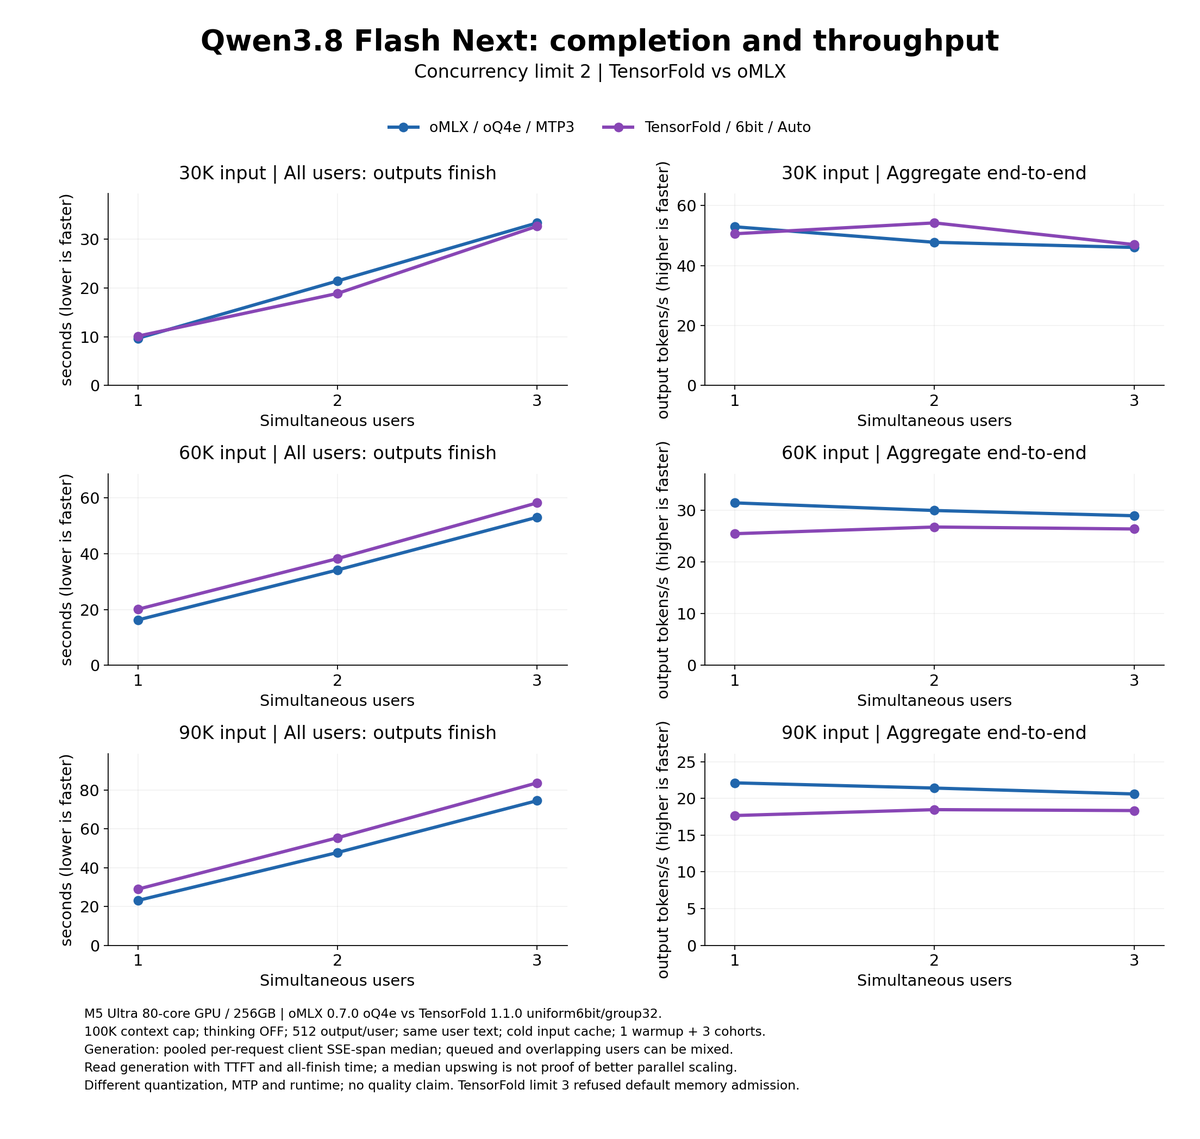
One more detail for the benchmark nerds! With concurrency limited to 1, TF decodes faster than oMLX. But at 90K input, oMLX gets the first token sooner and finishes all 3 queued requests faster!Faster decoding≠faster end-to-end.Different quantization and MTP settings, as always.
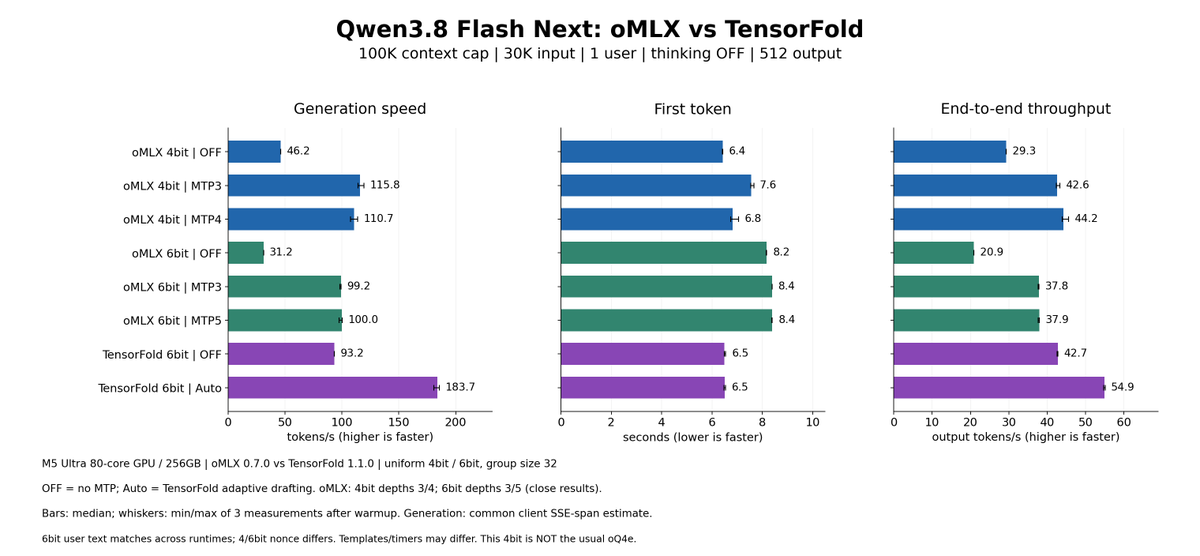
Someone mentioned TensorFold, so of course we had to try it!
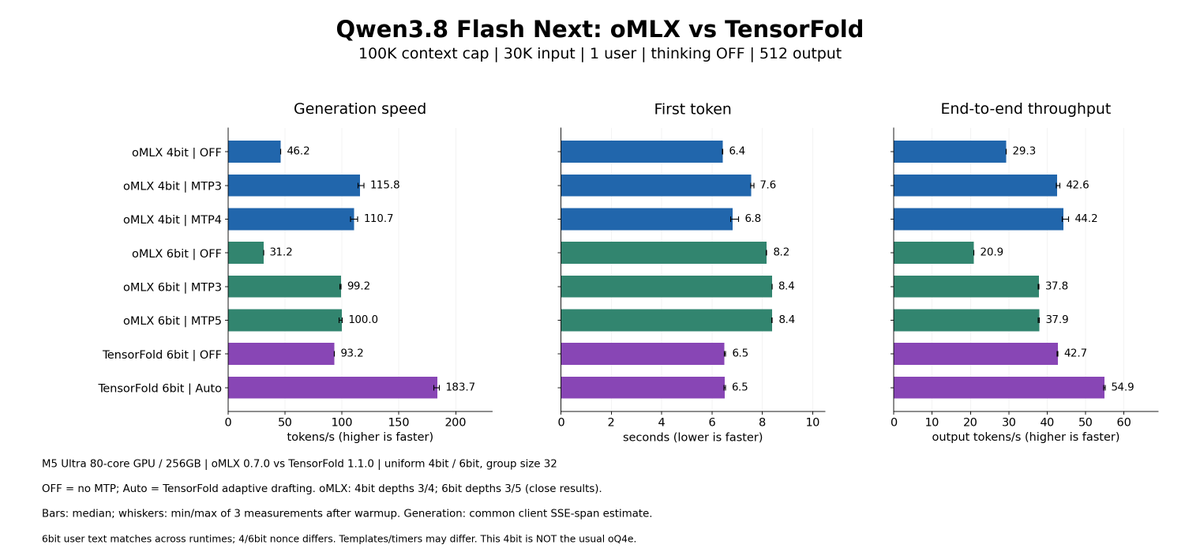
Qwen3.8 Flash Next on our M5 Ultra, 30K input:
TensorFold 6-bit Auto: 183.7 tok/s
oMLX 6-bit MTP: 100.0 tok/s
End-to-end: 54.9 vs 37.9 output tok/s.
TensorFold is seriously fast! 🚀
And here's the real question: how fast does the whole job finish?
Despite TF's impressive single-user speed, end-to-end throughput is often similar to oMLX.
With longer inputs, oMLX actually comes out ahead!
Peak generation speed isn't everything.
The full workload matters!
The final question: does more concurrency mean more total throughput?
Not necessarily!
On the Mac, with 30K input, aggregate end-to-end throughput stays around 48–52 output tok/s from 1 to 3 users.
More users, but not 3× the speed!
The best setup really depends on your workload.
The final question: does more concurrency mean more total throughput?
Not necessarily!
On the Mac, with 30K input, aggregate end-to-end throughput stays around 48–52 output tok/s from 1 to 3 users.
More users, but not 3× the speed!
The best setup really depends on your workload.