Build, don’t just watch.
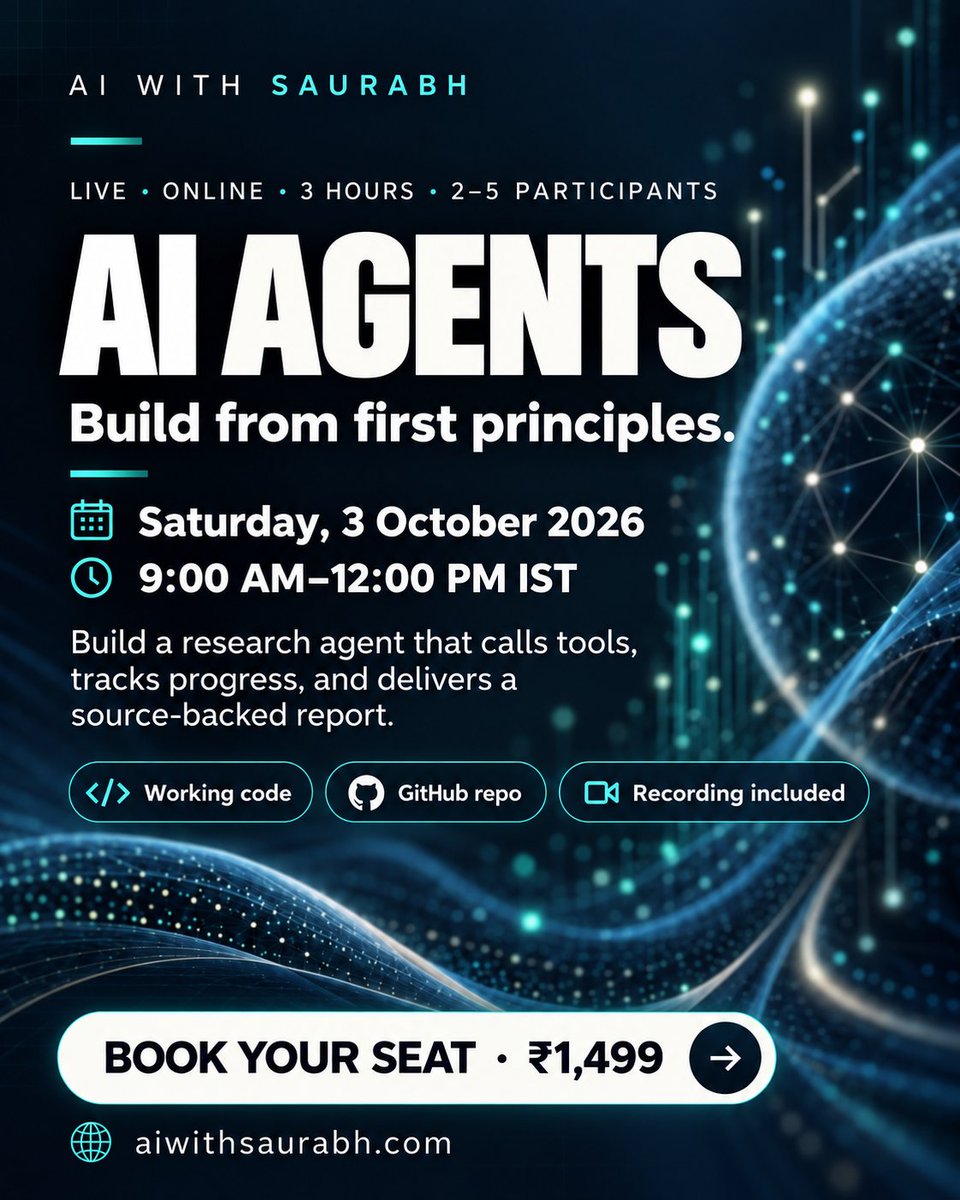
I’m hosting a small, hands-on AI agents workshop. The goal is simple: leave with a working project you can put on GitHub, explain to someone else, and talk about with confidence in an interview.
Together, we’ll build a research agent that calls tools, tracks its progress, and produces a report backed by sources. You’ll understand the code and the decisions behind it—including where to set limits and what you would improve before using it in production.
We’ll build one agent deeply, then use it to discuss broader patterns such as planning, memory, agentic RAG, MCP, and evaluation.
📅 Saturday, 3 October 2026
🕘 9:00 AM–12:00 PM IST
💻 Live online · 2–5 participants
🎥 Recording included
🎟️ ₹1,499
Basic Python, Git, and API familiarity will help. Come ready to code.
Book your seat: https://t.co/CQ4cjpMXDO
Jev raises an interesting question: how much of the AI inside our software actually needs to generate text?
Routing a support ticket. Scoring document relevance. Selecting an agent’s next tool. Deciding whether to escalate.
These tasks often need a bounded decision—and a useful estimate of uncertainty.
@TypeSafe AI’s Jev is built around that interface: send application context and typed questions; receive choices, scores, and probabilities your code can use directly.
Three things stand out to me:
• The interface matters. Structured decisions can make AI easier to compose, test, and integrate into existing software.
• Uncertainty needs measurement. Returning a probability is easy. Demonstrating that predictions assigned 80% probability are correct roughly 80% of the time is much harder.
• Open-source alternatives are already emerging. Projects such as kev and Simple Jev show how accessible the basic pattern is. Matching performance across unfamiliar tasks remains a substantial challenge.
There’s also a distinction worth keeping clear: a valid output can still be a wrong decision. Type safety doesn’t guarantee factual correctness, and headline speedups depend on the workload and comparison.
The architecture I find compelling is straightforward:
Code handles exact rules.
Decision models handle bounded judgments.
Reasoning models handle harder cases.
Humans handle consequential ambiguity.
Jev makes that division of responsibility worth a closer look.
For builders, the useful metric is: how much of a workflow can we automate at an acceptable error rate, latency, and cost?
Where would a fast, calibrated decision model fit into your stack?
Got this today: Programming Massively Parallel Processors.
As AI gets better at writing code, understanding what happens underneath matters even more: memory, parallelism, bottlenecks and performance.
Time to go deeper into GPU computing. 🟢
Got this today: Programming Massively Parallel Processors.
As AI gets better at writing code, understanding what happens underneath matters even more: memory, parallelism, bottlenecks and performance.
Time to go deeper into GPU computing. 🟢