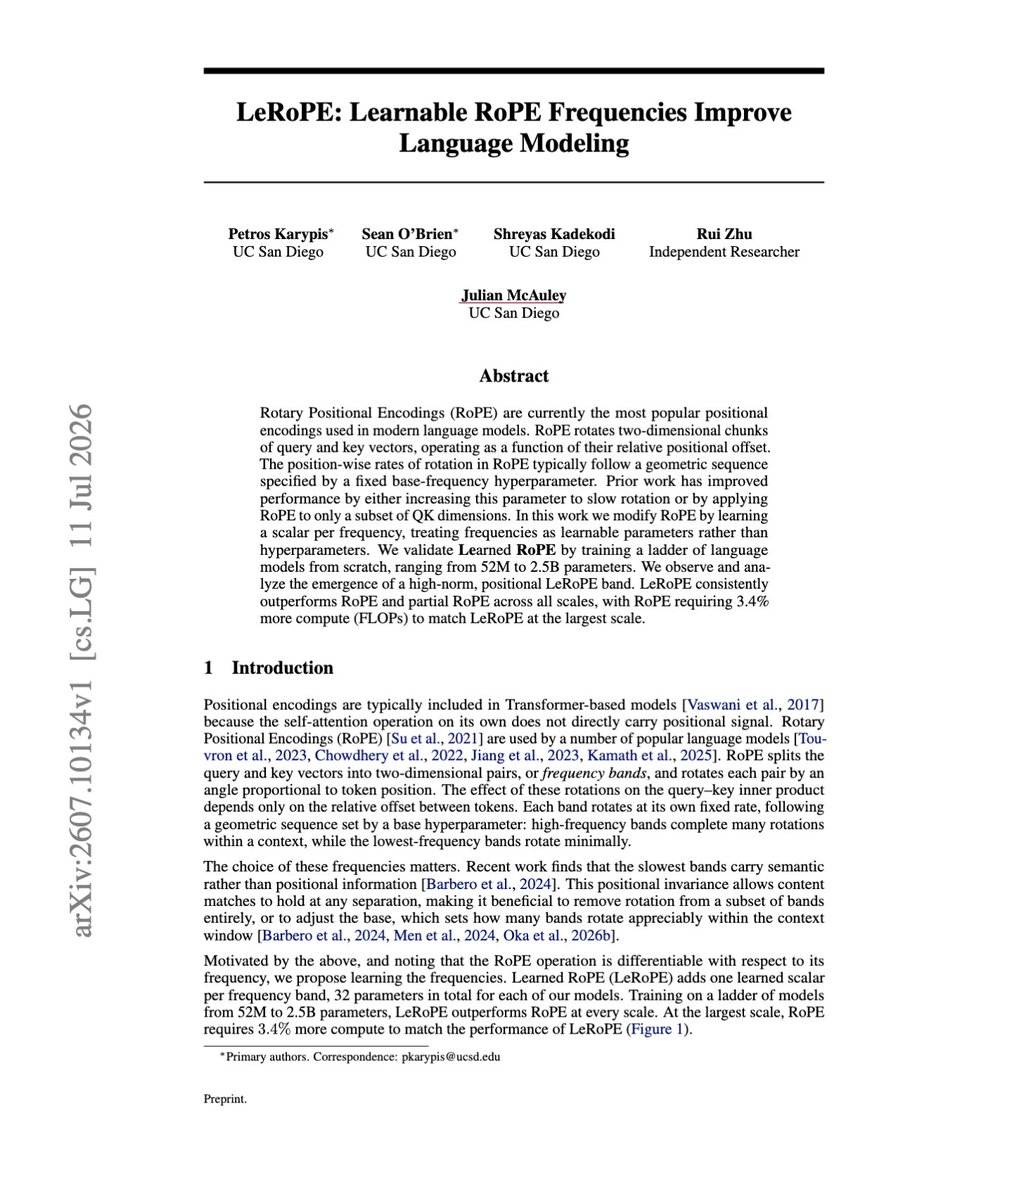
"LeRoPE: Learnable RoPE Frequencies Improve Language Modeling"
LLMs use hand-picked RoPE frequencies to understand token positions, but this paper shows they work better when the frequencies are learned.
With just 32 extra parameters, LeRoPE beats RoPE across scales and discovers a dominant positional band around 2.2x the training context.
(1/n)
32 extra parameters → 3.4% saved pretraining compute
RoPE’s rotation frequencies matter, but they’re usually fixed at hand-picked values. In a new work with @kpetro_research, we let the network decide: LeRoPE learns the RoPE frequencies during pretraining.
Thread below!
What advantage to use, and when? Everyone's proposing new advantage functions for RL with LLMs but nobody knows why they work or fail.
We break this down and build FADE a self-adapting advantage to get +14% on LiveCodeBench v6 in 40% less steps.
Paper: https://t.co/fAX16uYPpt
@jiqizhixin This looks quite similar to the off-policy setup of Any-Reward Generation Optimization (AGRO), just with a drifting reference policy. Might be worth referencing.
https://t.co/p2ZfGVDRyl
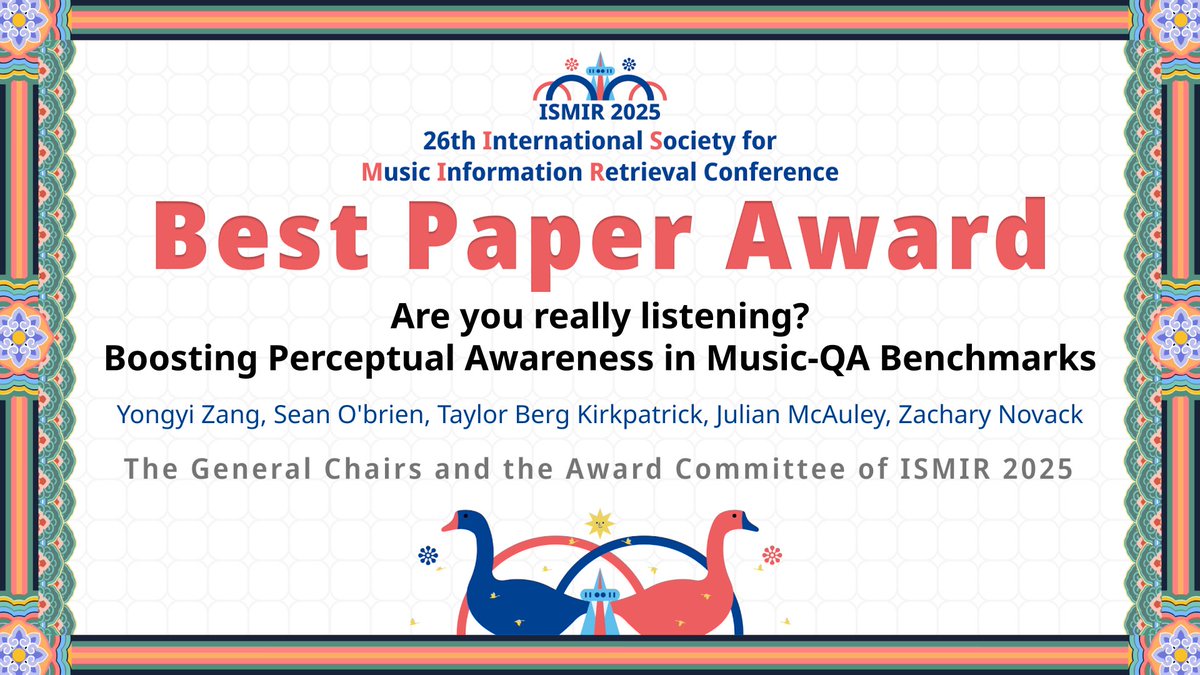
Are AI models for music truly listening, or just good at guessing? This critical question is at the heart of the latest Best Paper Award winner at #ISMIR2025!
Huge congratulations to Yongyi Zang, Sean O'brien, Taylor Berg Kirkpatrick, Julian McAuley, and Zachary Novack for their paper, "Are you really listening? Boosting Perceptual Awareness in Music-QA Benchmarks."
They expose how current benchmarks can be solved without genuine audio perception—even by text-only models! Their new framework, RUListening, creates evaluations that force models to prove they're actually hearing the music. A vital step forward for robust AI evaluation.
@LinkBechtel That's a good way of putting it -- another is to say we're giving extra encouragement to behaviors that the amateur hasn't learned (because it's too small to learn them).
Excited to announce my new paper! Check it out: https://t.co/8WedbLmaZO
TL;DR: we improve LM reasoning with only 3-5 lines of code and 3% extra compute. The method requires no training, scales well, and earlier work shows that humans prefer its longer generations.
(1/8)
Contrastive Decoding Improves Reasoning in Large Language Models
paper page: https://t.co/IYx3dn1Wb5
demonstrate that Contrastive Decoding -- a simple, computationally light, and training-free text generation method proposed by Li et al 2022 -- achieves large out-of-the-box improvements over greedy decoding on a variety of reasoning tasks. Originally shown to improve the perceived quality of long-form text generation, Contrastive Decoding searches for strings that maximize a weighted difference in likelihood between strong and weak models. We show that Contrastive Decoding leads LLaMA-65B to outperform LLaMA 2, GPT-3.5 and PaLM 2-L on the HellaSwag commonsense reasoning benchmark, and to outperform LLaMA 2, GPT-3.5 and PaLM-540B on the GSM8K math word reasoning benchmark, in addition to improvements on a collection of other tasks. Analysis suggests that Contrastive Decoding improves over existing methods by preventing some abstract reasoning errors, as well as by avoiding simpler modes such as copying sections of the input during chain-of-thought. Overall, Contrastive Decoding outperforms nucleus sampling for long-form generation and greedy decoding for reasoning tasks, making it a powerful general purpose method for generating text from language models.
@Vannaweh@_akhaliq This paper is more intended to show that contrastive decoding is more versatile than we previously thought, but there's lots of important research to be done in the future to make it stronger and robust across more domains.
@Vannaweh@_akhaliq That's a fair concern, which is why we downweight the amateur penalty by a factor beta < 1 which we see alleviates the problem in most domains (truthfulness being the exception). Plus, we find gains in standard math reasoning datasets like GSM8K, which aren't trick questions.
@imran__ds Wish I could! Unfortunately the amateur model used in this study is an unreleased version of LLaMA that I'm not authorized to open-source. The 7B-amateur and Flan-T5 experiments, as well as the negative prompting results, are all built on open-source models.
@TheNr24@benjiwheeler So it might look like
Small model: 90/10 A/B
Large model: 55/45 A/B
[ here we extrapolate! ]
Even larger model (projected): 45/55 A/B
You may notice this extrapolation is rough. You could in theory add more models to get a better estimate :^)
@TheNr24@benjiwheeler Here's another way of thinking about it: we're extrapolating to roughly guess what an even larger model would pick. Imagine the guesses changing continuously as a function of how many parameters our LM has; we're just giving a little boost to the existing trend.