THIS IS WHY THEY TOOK DOWN JENSEN HUNAG
Four months ago, Jensen Huang revealed he was about to BREAK the closed-model monopoly over AI and completely reshape the AI industry.
He made a direct THREAT to America’s biggest AI companies.
He revealed Nvidia was working on a MASSIVE new frontier-level, open AI named Nemotron 3 Ultra and that it would be competing directly with Claude Opus…
And most importantly, it would be MUCH cheaper.
Think about what that means. An American, open-weight, frontier-level model at a fraction of the cost could destroy the business models, valuations and upcoming IPOs of America’s AI oligarchs.
And what do you know, the person who leaked the “honeypot” story to the press was none other than ANTHROPIC CO-FOUNDER Jack Clark, who reportedly holds a larger stake in Anthropic than Dario Amodei himself…
NVIDA is well placed to dominate AI as it has the one thing almost every AI company needs but doesn’t produce. The hardware.
And if NVIDIA starts competing directly with its biggest customers with frontier-level, open-weight AI, at dramatically lower prices, its over for the AI Epstein class. And it would be amazing for humanity.
So he had to go.
He has been replaced by a Zionist who starts her day every day talking to Israel. And 3 Israelis are on the list to replace him permanently.
Will they shelve or nerf the Nemotron family and the coalition of eight labs building frontier OPEN models?
Will they CANCEL his five-year, $26 billion commitment to open-weight model development?
And will they kill the pending $13B acquisition of Hugging Face, the default distribution layer for open models. A deal that has not yet closed, very convenient timing.
Founder priorities rarely survive such transitions intact, especially when the stock dives 30%. They know this.
AI is indeed in its childhood. Mark this International Children's Day—the beginning of a new era for personal computing.
https://t.co/RLggVsNoll
Wintel is becoming Windows & NVIDIA.
This also has a fundamental impact on enterprise AI. Every enterprise must have its own brain.
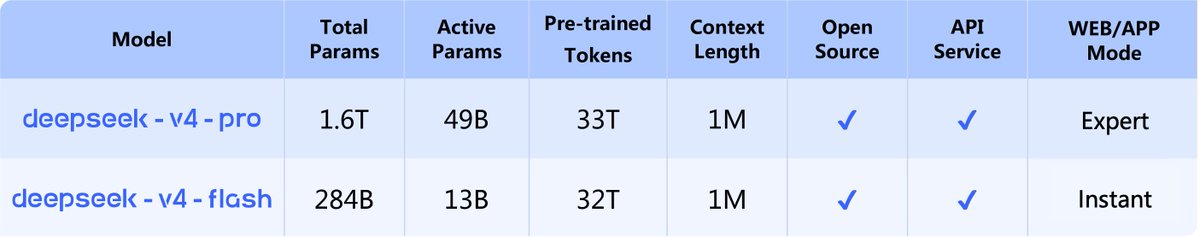
🚀 DeepSeek-V4 Preview is officially live & open-sourced! Welcome to the era of cost-effective 1M context length.
🔹 DeepSeek-V4-Pro: 1.6T total / 49B active params. Performance rivaling the world's top closed-source models.
🔹 DeepSeek-V4-Flash: 284B total / 13B active params. Your fast, efficient, and economical choice.
Try it now at https://t.co/GCdiMzk1Dl via Expert Mode / Instant Mode. API is updated & available today!
📄 Tech Report: https://t.co/drlDrxkYtp
🤗 Open Weights: https://t.co/T13Y8i7SDM
1/n
LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
Toronto, get ready!
Who's streets, Our streets!🇨🇦🫡
Sunday, November 24/2024
Nathan Phillips Square
City Hall I Toronto, Ontario
**if you're behind this, share it**
#canadafirst#makecanadagreatagain#maplemaga#canada
Congratulations to Donald J. Trump on his election as the 47th President of the United States.
The U.S. is Canada’s best friend and biggest trading partner, and I will work with the President to benefit both countries.
My mission: save our jobs.
The U.S. has already taken half a trillion dollars of investment and jobs from Canada under 9 years of Trudeau, and our people cannot afford homes and food. Yesterday’s result confirms we must cancel Trudeau’s plan to quadruple the carbon tax and hike other taxes, which would push hundreds of thousands more jobs south where President Trump will be cutting taxes even further.
We must axe taxes. Bring home our paycheques. Save our jobs. Stand up for Canada.
MASSIVE brawl at a Hindu Temple in Brampton after Khalistani lunatics showed up to protest in front
Who else is fed up of seeing foreign conflicts resulting in violence in our streets
STOP ruining my country over bullshit that has nothing to do with Canada
It was 5 a.m. when a surge of alerts broke through the darkness: A "blue screen of death" was spreading across the globe.
Gregory Richardson discusses initial observations from recent endpoint outages.
🎥 Full video: https://t.co/BBVOHwK95F
9 out of 10 customers are willing to recommend #BlackBerry’s Endpoint Protection Platform – peer recognizing it as a Customers’ Choice by Gartner® Peer Insights™:
💬 Learn more: https://t.co/MEgqPlevUM
💬 Read the review: https://t.co/sH14JvulpX