

Search results for argon
People
Argo Nerd 
@argonerd

from ARGONAVIS(フロム アルゴナビス)公式
@ARGONAVIS_info

Argonne National Lab
@argonne

Argonomi
@argonomii
Toronto Argonauts
@TorontoArgos

Argon Token (Crypto)
@ArgonAsset

Argona
@Argona0x

Argon 🔞30k
@argontorn

Andrew Naylor
@argon

Arnold SIWASTANEGEZER🇹🇷
@Argonomik

ひより
@ArgonAIstic

argonpads
@argonpads

Argonaut Games
@ArgonautGames_

THE lusty argonian maid
@lindawg

ARGÒN💚🇪🇸
@MIGUEL96867489

Argon Galio
@argongalio

Argon Investimentos
@argon_invest
あるごん 🐸 Argon
@arugon999

あるごん@デイト���専門医
@Argon_7

Аргон
@argon_delta
Tweets including argon

@Yosuction @onurtirpan Allah aşkına ne yaptırıyorsun Argon'a? Çeviri mi yaptırıyorsun merak ettim :d
Bir insanın argon övmesi için 2024 yılında olması gerekiyor ya veya başka Ai modeli kullanmamış olması gerekiyor


Gemini 4 "???? (Flash)" vs "Argon"
Helium ???
https://t.co/NvSVzl6O8f
@Occult_kun7 GEMINI 4 PRO "MARS TIME"

不谈跑分,只聊真实写代码。
Grok 4.7 专家
GPT-6 Luna Max
Gemini 4.0 Argon
DeepSeek V4.1 Flash
哪个最值得入手?

GoogleがArgonとCorbonでLLMのフロンティア競争に戻ってきたのと、世界モデルを開拓してるのもあって、先日決算のマイナスサプライズが買い場に見えてきた

The number to watch isn't the 59. AA measured Carbon's hallucination rate rising from 4% on Argon to 11%. That's still the second lowest of any model tested: Claude Opus 5.5 and GPT-6 Astra sit at 50%. https://t.co/6sZY7U5s23

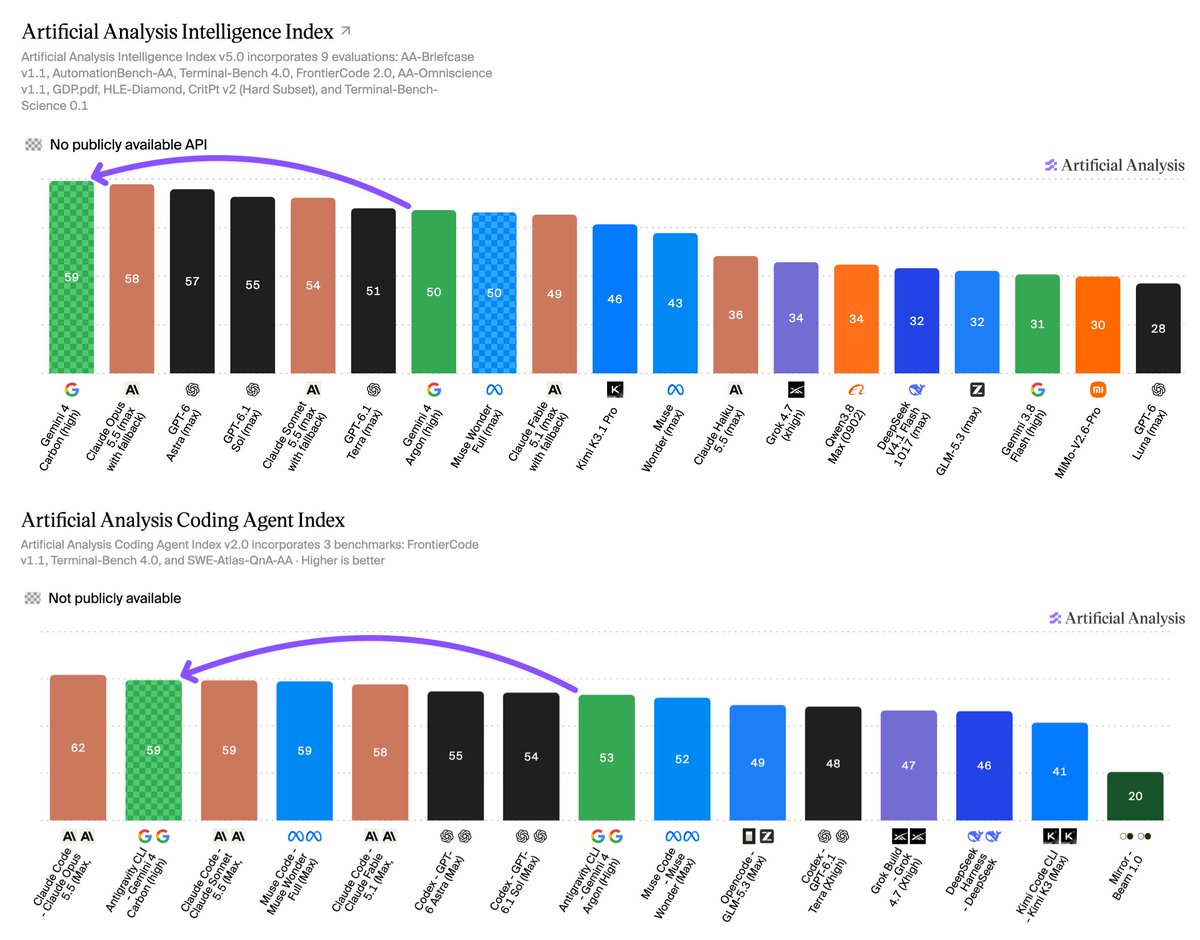
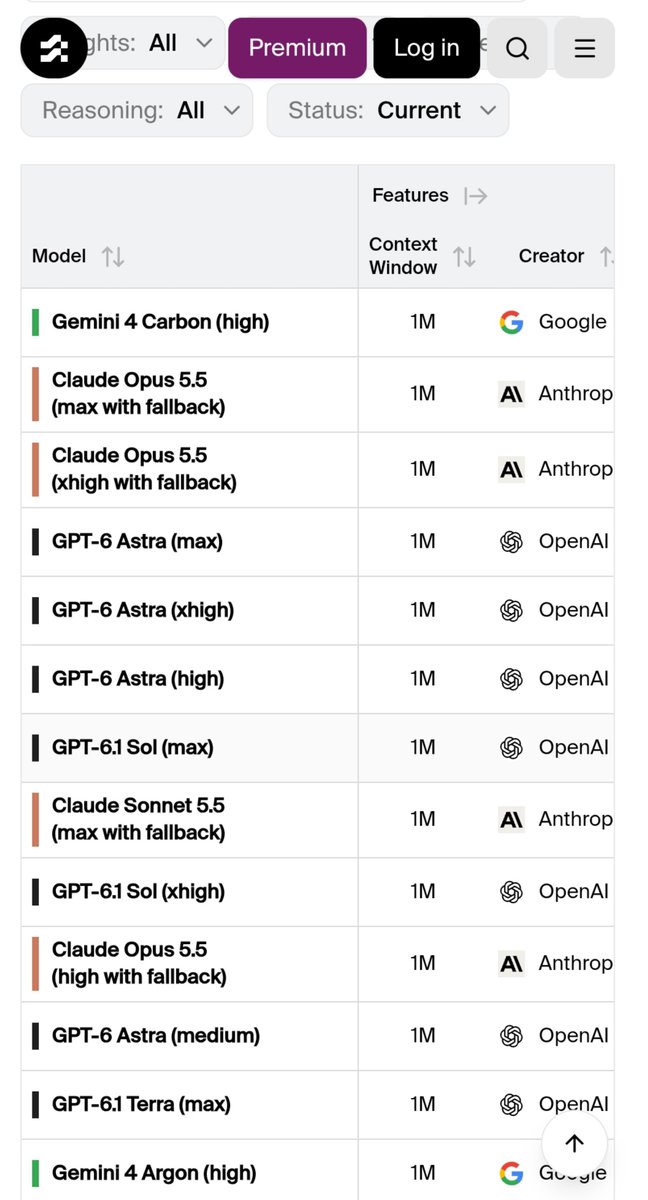
Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index
Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas.
As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon.
Key results for Gemini 4 Carbon with high reasoning:
➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work
➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out
➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671
➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index
➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M)
Congratulations to the @GoogleDeepMind team!

在没有找到稳定 Claude 订阅方案之前,疯狂找一些替代方案,这个过程中遇到的坑,给大家分享一下:
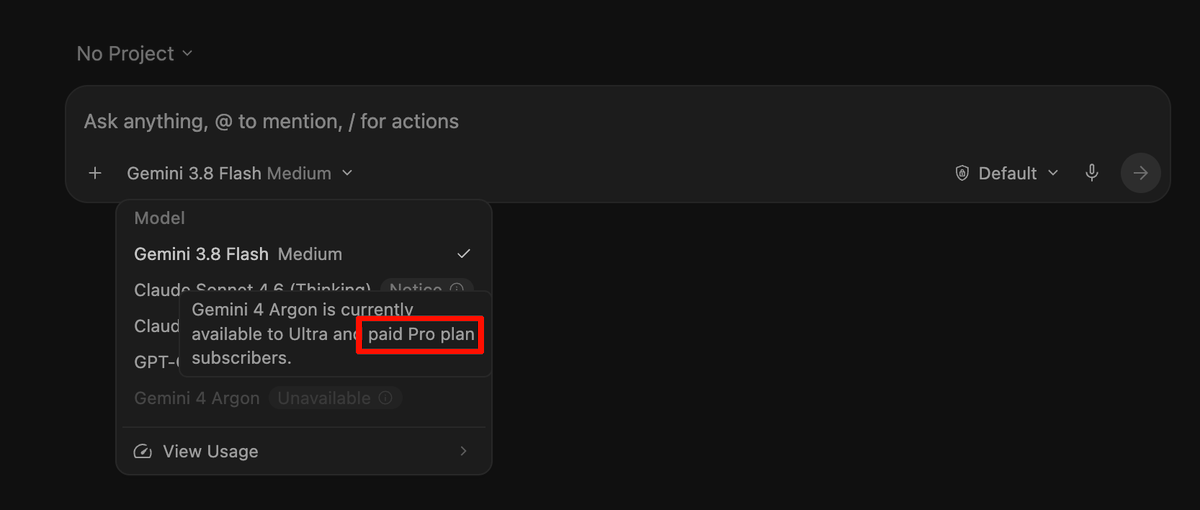
Google Antigravity 里我记得之前可以用 Claude Opus 5.5,但 Jio 活动的 Google AI Pro (闲鱼卖的那些便宜会员)不算文档说的 paid Pro
所以,Gemini 4 Argon 和 Claude Opus 5.5 都用不了,现在还能用到的是 Claude Opus 4.6,到 11月2号 也会禁用

There’s hydrogen and helium lithium beryllium boron carbon nitrogen oxygen fluorine neon sodium magnesium aluminum silicon phosphorus sulfur chlorine (??) argon potassium calcium scandium (???) titanium (??? V element) chromium manganese iron cobalt nickel copper zinc gallium ger


@peterwildeford It is impressive but we'll need to see where Bel and fable5.5 will be.
Especially Fable considering Anthropic keeps up with Astra and Argon/Carbon with "just" Opus.

@wenhaocha1 Though instead of manually uploading X's data archive, Argon preferred X's Syndication API, which just showed my top posts, not all the posts.

Comparison with Kimi K3.1 Pro and Gemini 4 Argon
Gemini 4 Carbon: Physics Sorted
> carbon is currently being tested under gemini-4-argon-high on arena
> just look at the motion, shadows, and how the paper bends and catches the light as the pages turn, the details are phenomenal ngl 👀
Comparisons with Kimi K3.1 Pro and Gemini 4 Argon in the comments


Geminiがずっと静かでGoogel AI Proの契約を見直そうかと思ったけどArgonやらCarbonやら突然盛り上がってきたし、antigravityでClaude Opus5.5 も使えるようになったしまあ継続でいいか・・

First Argon, then carbon... Silicon next?

I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!


10/28に、GoogleがGemini 4 Carbonを発表しました。
まず一部のサイバー防御組織向けに限定提供です。開発者や企業、一般への時期はまだ発表されておらず。残念。
ベンチマークでは現行AI比トップです。
Argonと比べて、安全なコード生成が2倍以上です。数日間の長時間作業もできます。
今すぐ仕事で使える話ではありませんが、長時間の仕事を任せる流れは進んでいます。
明日できる一歩は、今使っているAIに、仕事を小さく分けて依頼してみることかな。

@salcastt @aashwindev @sundarpichai @ArtificialAnlys Yea Grok Pro is shockingly bad now compared to Gemini argon

@chenran818 I asked Sonnet 5.5 High one question in Antigravity with the $20 plan, and the whole 5h weekly usage was gone in about 7 minutes without even finishing the task. Then I moved to Argon Medium, and so far, it used 60% of my weekly limit in 40 minutes.

Two weeks after Argon, Google drops Gemini 4 Carbon to secure the top spot on the AI leaderboards. The reasoning model wars are escalating fast.
Gpt vs Claude then gemini entry

Google just dropped Gemini 4 Carbon, two weeks after Gemini 4 Argon. Two frontier models in fourteen days. That is not a product launch anymore, that is a production line.