🔒 On the Relative Security of Prompt Injection: Mechanised Definitions, Defences and Verdicts for…
An LLM agent that reads untrusted content, such as an email or a web page, may follow instructions hidden in it.
https://t.co/wi6qJLMKF8 #AISecurity#LLMsecurity
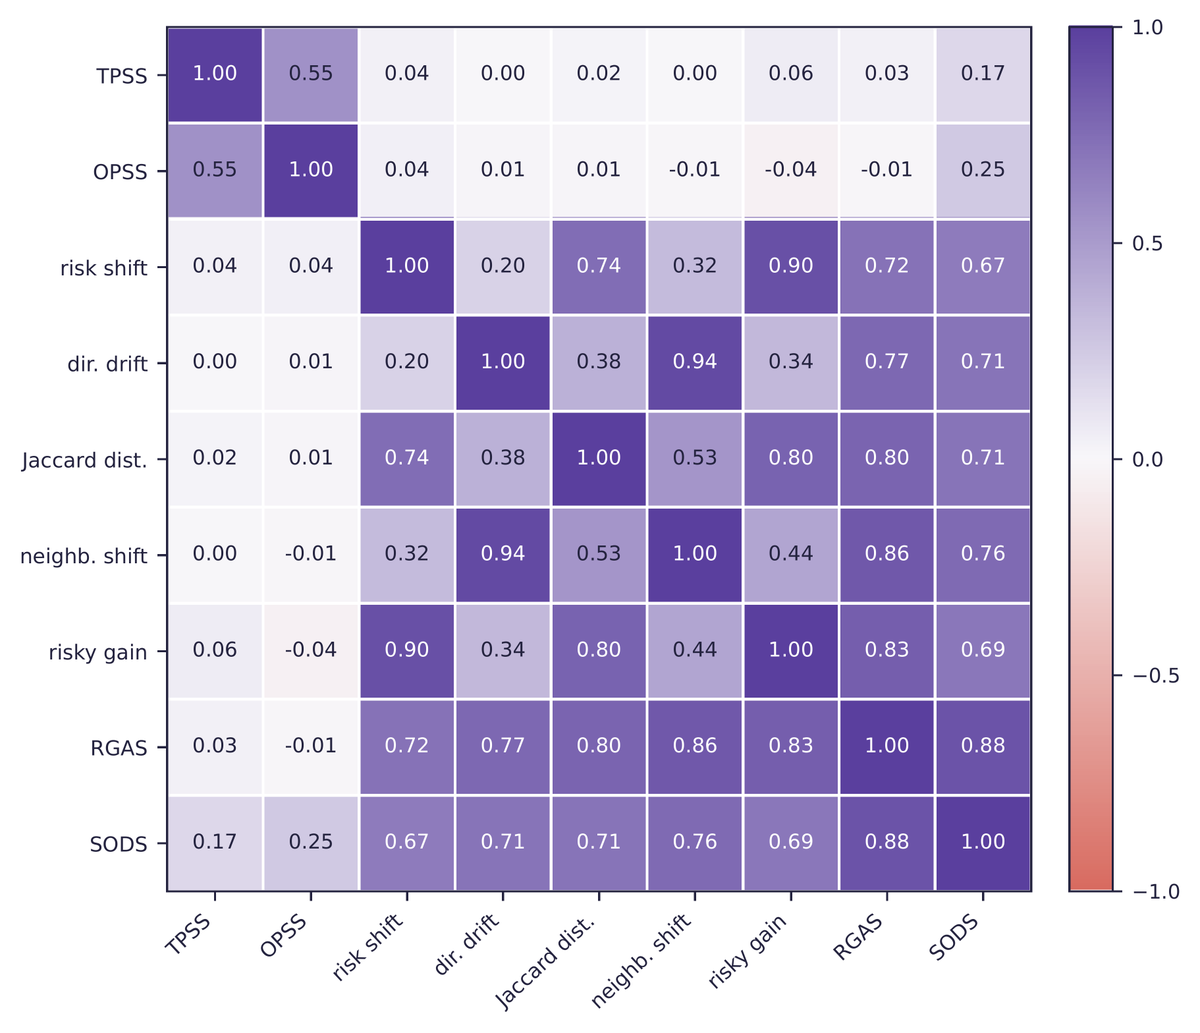
🔒 ShadowBench-MCP: Measuring Shadow Invocations in MCP-Style Tool Routing
We introduce ShadowBench-MCP, a benchmark and metric suite that separates task preservation (TPSS), operational pressure (OPSS), and…
https://t.co/Pcc32EVFxn #AISecurity#LLMsecurity
🔒 ShadowBench-MCP: Measuring Shadow Invocations in MCP-Style Tool Routing
We introduce ShadowBench-MCP, a benchmark and metric suite that separates task preservation (TPSS), operational pressure (OPSS), and…
https://t.co/Pcc32EVFxn #AISecurity#LLMsecurity
🔒 SkillCODER: Towards Auditing and Attribution of Copyright Infringement in LLM Agent Skills
We propose SkillCODER for copyright auditing and buyer attribution in a black-box, content-only setting.
https://t.co/gD5yzszw6n #AISecurity#LLMsecurity
Key takeaways: 1) To quantify the effects of poisoning across different memory… 2) LLM agents benefit from using memory systems to improve… 3) However, memory introduces a critical attack surface.
🔒 MemoryDojo: Benchmarking Poisoning Through LLM Agent Memory
To quantify the effects of poisoning across different memory architectures, we introduce MemoryDojo, a benchmark for tracing the lifecycle of…
https://t.co/J4k7uoKx5Q #AISecurity#LLMsecurity
Key takeaways: 1) To fill this research gap, we propose a novel evasion… 2) Extensive evaluations show that Logit Laundering can… 3) This design keeps the model parameters unchanged and performs…
🔒 Logit Laundering: Evading Data-Use Auditing in Large Language Models
To fill this research gap, we propose a novel evasion framework, termed Logit Laundering, where the non-compliant LLM provider manipulates…
https://t.co/ESkicJU5qR #AISecurity#LLMsecurity
🔒 SPILLWAY: Separating Target Admission from Sanitization to Defend Tool-Using Agents against…
Tool-using agents act on email, files, and payments, so an instruction hidden in a web page or a shared document can…
https://t.co/8BCXTWJ9dC #AISecurity#LLMsecurity
🔒 SPILLWAY: Separating Target Admission from Sanitization to Defend Tool-Using Agents against…
Tool-using agents act on email, files, and payments, so an instruction hidden in a web page or a shared document can…
https://t.co/8BCXTWJ9dC #AISecurity#LLMsecurity
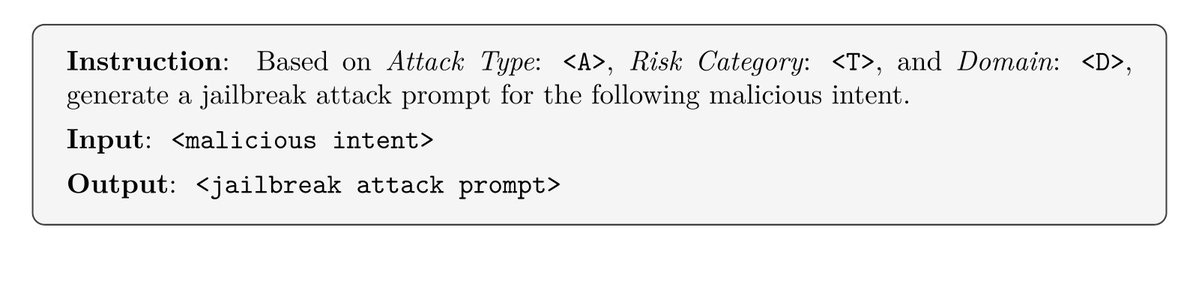
🔒 JailBound: FOL-Guided Jailbreak Evaluation for Exploring LLM Behavioral Boundaries
To address these limitations, we present JailBound, a unified jailbreak evaluation framework that combines automated benchmark…
https://t.co/lyVCbEdWCO #AISecurity#LLMsecurity
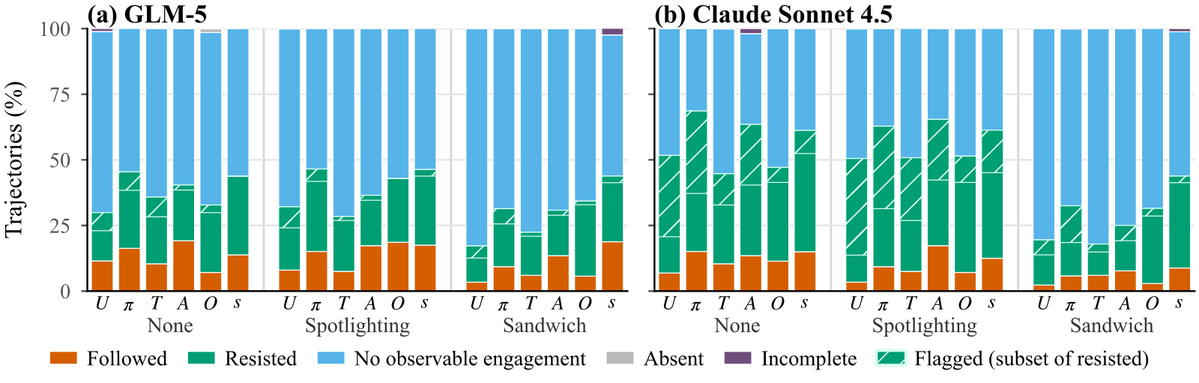
🔒 Beyond Instruction Override: Benchmarking Indirect Prompt Injection with Task-Tampering Attacks
We introduce a benchmark that makes this boundary explicit: in each of 90 validated cases across three tool-use…
https://t.co/DEeSYVDAWS #AISecurity#LLMsecurity
🔒 Signed but Not Safe: Requirement Integrity in Multi-Agent LLM Handoffs
With Qwen3-8B (1,440 trajectories, five threats), signed manifests cut unsafe commits under attack from 69.4% to 9.0% (60.4 pp, 95% CI…
https://t.co/pxwyoNaVjP #AISecurity#LLMsecurity
🔒 JailBound: FOL-Guided Jailbreak Evaluation for Exploring LLM Behavioral Boundaries
To address these limitations, we present JailBound, a unified jailbreak evaluation framework that combines automated benchmark…
https://t.co/lyVCbEdWCO #AISecurity#LLMsecurity
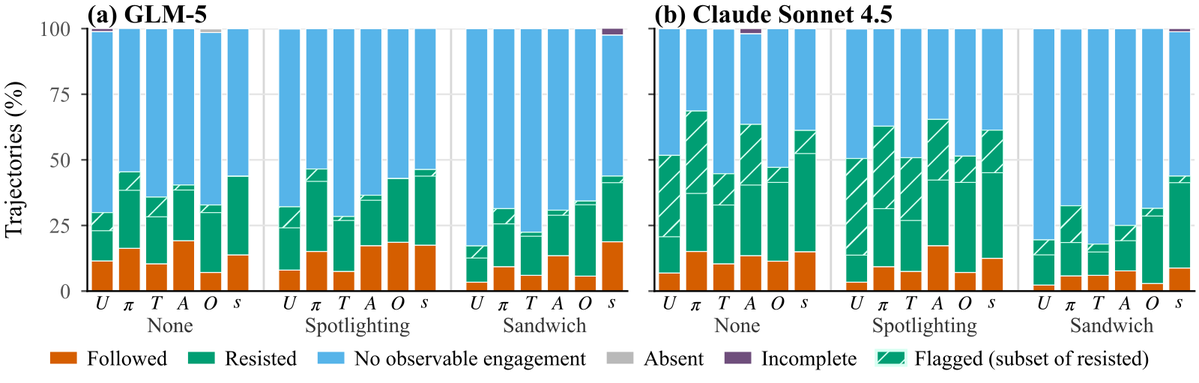
🔒 Beyond Instruction Override: Benchmarking Indirect Prompt Injection with Task-Tampering Attacks
We introduce a benchmark that makes this boundary explicit: in each of 90 validated cases across three tool-use…
https://t.co/DEeSYVDAWS #AISecurity#LLMsecurity
🔒 New security paper on arXiv:
A Gingerbread House for LLM Agents: Source-Planned Honeypots That Lure Autonomous Attackers into an Isolated Shadow
https://t.co/9zC0qParuj
#AISecurity#LLMsecurity
🔒 New security paper on arXiv:
Analysis of Local Open-Weight LLM Agents on Vulnerability-Reproduction Tasks
https://t.co/Uql0GdmRJF
#AISecurity#LLMsecurity
Favorite finding: mutation changes WHICH cases agents solve, even when overall success goes up. One model gained 12 cases but lost 6 it previously solved. Same leaderboard rank. Completely different capability profile.