DeepMind 发布 AlphaGenome 2,预测 DNA 变异在不同细胞里的效应:一次读入 1 Mb DNA 加一个目标细胞状态。TenK10K 上因果变异召回率 16%→30%,方向判断 23%→43%,API 免费向非商业研究开放。我觉得 AI for Science 就该这样:直接给工具而不是只发论文,你会用吗?
https://t.co/0oNnIxseeD
Meta 管基建的老将要走了:Santosh Janardhan 2009 年加入,一路做到基建负责人兼工程联席主管,现在交棒给在亚马逊干了 19 年的 Dave Brown,明年正式离开。我觉得时间点很微妙——Meta 正砸钱扩数据中心,换帅等于换打法。接下来看 Brown 怎么接这摊子了。
https://t.co/CKygOvddZK
Muse Ember (Max) by @AIatMeta lands in Agent Arena as the most capable and efficient : +1.7% net improvement at about $0.02 per task, roughly 4x less than GPT-6 Luna (Max) and Claude Haiku 5.5, across 6k real-world agentic sessions from our global community.
How it stacks up against other efficient models
- #25 Muse Ember (Max): +1.7% | $0.02/task | 0.5 min/task | 11.6K output tokens
- #26 GPT-6 Luna (Max): +1.6% | $0.09/task | 6 min/task | 41.2K output tokens
- #29 Claude Haiku 5.5 (High): +0.5% | $0.08/task | 1.8 min/task | 24.3K output tokens
Performance is on par across the three, but Ember's median task costs roughly 4x less, finishes about 12x faster than Luna (Max) and 3.5x faster than Haiku 5.5, and uses 72% and 52% fewer output tokens.
Congrats to the @AIatMeta team, @alexandr_wang and @finkd on this impressive release!
AI 编程没让人少干活,反而越干越晚。Marc Andreessen 在播客上说,硅谷出了个词叫“AI 吸血鬼”:效率太高,写代码根本停不下来。顶级 AI 程序员年薪已开到 5000 万美元。我觉得这行正在分化,会用 AI 的越卷越狠。你最近是变轻松了还是更晚了?
https://t.co/7tym19wFiQ
Marc Andreessen (the guy who called it when “software ate the world”) pointed out what AI is doing to coding.
"Everyone assumes AI coding means fewer hours… or leaving the profession. But almost everyone I know is working more hours."
"There’s a new term in the Valley: the ‘AI vampire.’ You’re up all night AI coding because you’re so productive you can’t shut it off."
"The top AI coders make $50M a year. They’ve found the philosopher’s stone."
"Every company has a thousand projects they’ve wanted to build but never had the bandwidth. Now they can. This isn’t a blip, it’s going to intensify."
except the real time sink flipped
developers aren't wasting hours writing syntax anymore
they're wasting hours manually switching models, babysitting reasoning depth, and burning token budgets across 4 tabs
the engineers actually compounding don't manually choose models on every turn
they let a decision model route each prompt to the right engine automatically
stop babysitting models at 3am
---
(Full video from PowerfulJRE" (Joe Rogan) youtube channel (link in comment)
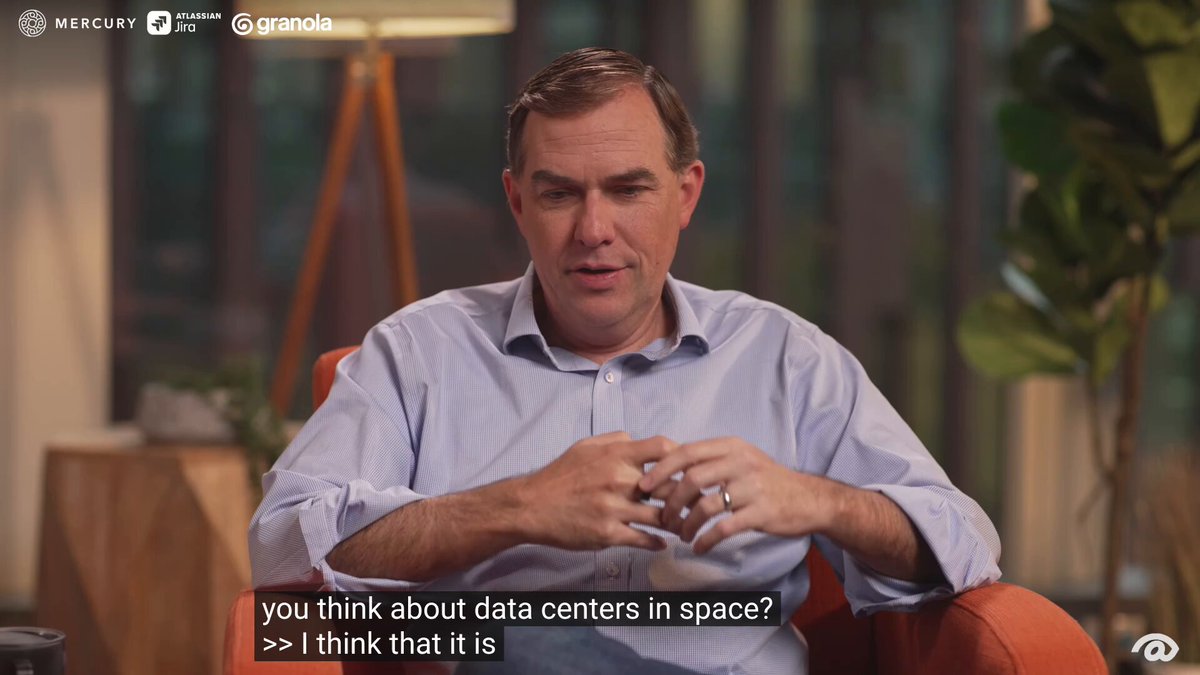
AWS CEO Matt Garman: Data centers in space are at least 10 to 20 years away.
"I think that it is highly unlikely to be economically feasible or practical in the next decade or two.
It sounds good. You get free energy and it’s up there somewhere. Launches are still relatively infrequent and expensive.
One person is not going to fix it. We as a world don’t do one launch a day today.
We’re landing in a data center today one GPU every 14 seconds. So we don’t do a launch a day for the world, and that’s just us doing one GPU.
A rack of GPUs might weigh a ton. I don’t even know if you can stick that on a launch vehicle or how many you can get up there.
People talk about gigawatt data centers and megawatts of racks. Most solar panels drive kilowatts, not gigawatts. So you need these gigantic things that are up there.
They’re really hot. Everyone’s like, space is cold. Space also doesn’t have air. Dissipating heat in space is actually quite hard.
It’s just a really hard environment. There’s radiation everywhere. It’s going to be way more expensive to build servers, from a serviceability point of view.
These are all technically solvable problems, and it’s just going to take a while. I’m not saying any one of these things is impossible. I just think that it’s way far out."
----
Full video on "Sources Podcast and and Alex Heath (@alexeheath ) " YouTube channel, (link in comment)
I used Gemini 4 Carbon to get Windows 11 running on my iPhone Duo! 💻
Unfold the screen and it's a pocket PC, including Antigravity running coding agents on my phone.
This is the actual desktop ARM OS running locally with touch controls.
Demo + repo below!
Towards Verifiable LLM Infra 🚀
Suppose coding agents can build a fast inference engine from scratch, and one engineer orchestrates 10,000 agents in parallel: how do we know the engine they wrote is actually correct? Having agents review other agents mostly wastes tokens compared to empirical and formal verification.
We introduce vstack, a 5-stage formal verification workflow for coding agents, and veriserve, a verifiable PD-disaggregated serving engine: uncovering 3 classes of real RDMA and cache races in production serving engines, and backing veriserve's KV-page lifecycle design model with a 226-module, 516,973-obligation TLAPS safety proof at +0.18% mean p50 TPOT overhead on GB200.
Blog: https://t.co/SdbINvSVht
veriserve: https://t.co/ugHLToReCN
vstack: https://t.co/GZJebbjdpL