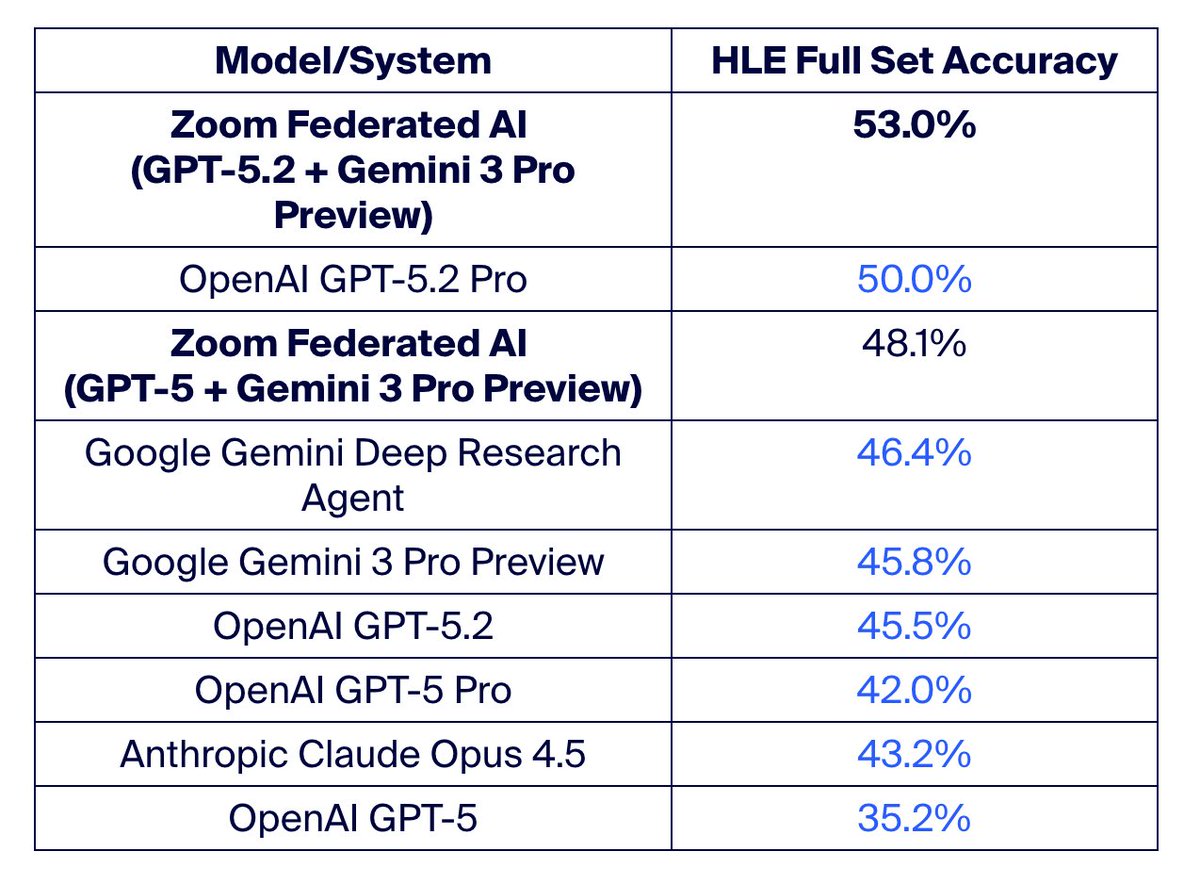
@HenkPoley@cocogoatmain@Zoom Zoom now raised the bar again to 53% on the full HLE set. For the text only subset that Kimi is reporting on, the accuracy is even higher - 55.2% https://t.co/jUuKxOQaER
@DeepwriterAI@Zoom It seems you only reported result on a subset? Zoom is talking about the full HLE set with text and image. The subset of HLE with images is noticeably harder than the text only ones
@omarsar0 Thanks for sharing! Glad that you find it interesting. This is a fun side project I did last December. I didn’t get enough time to run more comprehensive experiments, so I would love to learn if you find CoD being less effective in some domains
@billyuchenlin Is the checklist for each example automatically generated by LLM? It would be great if the prompt to generate the checklists could be shared. Thanks.
@nishant_ch@MKBHD You can’t unlock a phone on a table with sensor on the back; sensor on the side only works for one hand. So both are suboptimal actually
We're at #acl2022. Come see our work "A Few-Shot Semantic Parser for Wizard-of-Oz Dialogues with the Precise ThingTalk Representation" (by @gcampax@sina_semnani Ryan Kearns, Lucas Sato, @sileixu and @MonicaSLam ) - right now in the VPS2!
Our second #emnlp2020 paper this year wonders, do we really need humans to build conversational agents? https://t.co/YdG1nzBlqG by @sileixu (*) Sina Semnani (*) @gcampax@MonicaSLam (1/n)
We are pleased to announce that @SloanFoundation is funding our new open-source initiative to create a usable virtual assistant for consumers that protects privacy, by building upon our Almond research prototype.