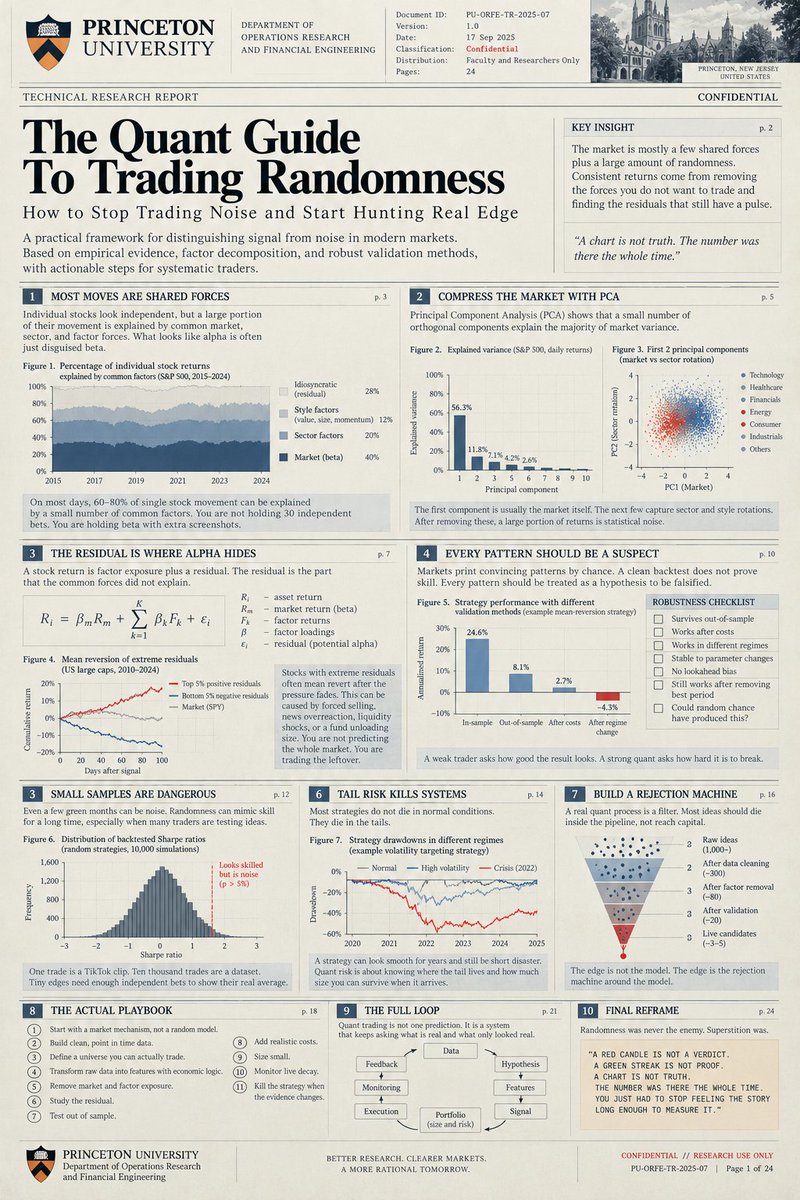
this Princeton paper is f*cking insane
it basically shows why most traders think they have 30 bets when they really have one
on most days, 60–80% of single-stock movement is explained by common forces
market beta alone explains about 40%
then the paper does the only thing that matters:
remove the market
remove sector + style factors
study the residual
try to break the signal
the scary part is what happens after validation
24.6% in-sample
8.1% out-of-sample
2.7% after costs
-4.3% after a regime change
that is why real quants do not protect pretty backtests
they build rejection machines
the edge is not what looks good
the edge is what survives
bookmark this before you trust another “alpha” signal
A TEAM OF AI RESEARCHERS JUST OPEN-SOURCED THE BLOOMBERG TERMINAL FOR QUANT FINANCE.
A Bloomberg Terminal costs $25,000 per year per seat. Banks pay for thousands of them.
This thing reads every quant paper, every financial blog, every SEC filing, every arXiv preprint, and turns it into a searchable knowledge base. For free.
GPT-6 Astra is the most powerful trading agent right now.
It gives you AGI-adjacent reasoning.
I've shown the exact way to use GPT-6 Astra at its HIGHEST benchmark.
You could literally build MOST complex trading models like hedge fund with it. https://t.co/VxsUknvnSu
GPT-6 Astra is the most dangerous AI model right now.
It gives you AGI-adjacent reasoning.
That can discover new profitable trading strategies for you 24/7.
If you set it up correctly, you gain a personal hedge fund. https://t.co/Sam7AYOut3
Next week, @mattyp@roshan_s and myself will be speedrunning building a new company using only Grok @Bot on the Grok Bot Galaxy livestream! We’ve been given just 3 days to do it, or else we might be turned into pizza 🤪 it will be so fun and I hope to see you on the livestream!
I will have to miss the Cursor Compile conf in London and Amsterdam though. I will instead record an extended version of my talk and make it freely available here. So stay tuned for that post!
https://t.co/pkqZ3O6IZw
Anthropic just released a 37-minute guide on how to build AI agents that can automate an entire business.
It’s free, and it comes straight from the engineers who built Claude.
Agents that actually work, delegate tasks, and get things done on their own.
Save this post 🔖
Just saw that the LLMs-from-scratch repository passed 100,000 stars on GitHub!
This is super cool and motivating. I am really happy to see that this open-source repo has helped so many people.
Thanks also to everyone who shared ideas and opened PRs with improvements!
Of course, I plan to keep adding new material, including new attention variants and architectures (while bigger projects like RL and Reasoning From Scratch live in their separate repositories).
I am also currently working on a larger applied custom “small” LLM project. It has been keeping me super busy this month, but I will share more on that soon.
If you are new to it, some of the highlights include
1. Of course, the complete code path from tokenization and attention to pretraining, classification, and instruction fine-tuning, etc. All of it FROM SCRATCH, of course! (RL lives in a companion repo.)
2. From-scratch implementations of Llama, Qwen, Gemma, and Olmo (smaller variants that run locally and can be plugged into the training scripts).
3. From-scratch implementations of attention alternatives and other architecture components, such as GQA, MLA, sliding-window attention, Gated DeltaNet, DeepSeek Sparse Attention, cross-layer KV sharing, and mixture-of-experts
4. Materials on KV caching, training performance, memory-efficient weight loading, DPO, evaluation, and LoRA
So, if you don’t have any weekend plans yet, happy tinkering!