Dear Americans,
I am a soldier of the Armed Forces of Ukraine, and I want to tell you something.
Freedom is not measured in dollars. Freedom is not measured by the price of diesel in your car’s tank.
Freedom is measured by a nation’s willingness to fight for its country, its people, and its right to exist.
We Ukrainians know the price of freedom. We pay it in blood. Every single day.
We will continue striking Russian military targets. We will continue fighting Russian invaders on land, at sea, and in the sky. In Ukraine and wherever Russia wages its war against us.
Because we are not fighting for money, oil, or comfort.
We are fighting for our homeland. For our future. For our FREEDOM.
And we will never surrender it.
Qwen3.8-27B has gone from ~82 tok/s to 381 tok/s on a single RTX 3090.
Same 24GB GPU. Around 250W. The big change is how the inference stack uses information already sitting in the prompt.
Here’s the progression:
• ~82 tok/s: initial single-user setup
• ~114 tok/s: optimized MTP
• ~138 tok/s: DFlash2 + lookup drafting
• ~381 tok/s: longer verification blocks + context lookup
The setup combines optimized vLLM, DFlash2 speculative decoding, lookup-augmented drafting, prefix caching and quantized KV cache, heads and activations.
The clever trick is that DFlash2 doesn’t have to limit verification to the seven tokens it normally drafts.
When the task involves reproducing or editing material already in the prompt, the runtime can fill additional draft positions directly from that context. The target model can then verify up to 16 tokens in one step.
On a roughly 25K-token document reproduction task:
• DFlash2 alone: ~260 tok/s
• Longer verification + context lookup: ~382 tok/s
• Accepted tokens: about 15 out of 16 per verification step
That’s where the headline number comes from. The model isn’t generating 381 entirely new tokens per second on arbitrary prompts. It’s efficiently verifying tokens that can often be recovered from the existing context.
For ordinary chat, the same setup reportedly reaches around 133 tok/s, which is still impressive for a 27B model on one RTX 3090.
The 381 tok/s mode is better suited to:
• RAG and document Q&A
• Coding agents applying edits
• Document rewriting and quoting
• Extracting information from long prompts
Prefix caching adds another useful optimization. When asking a second question about the same 25K-token document, reported time to first token drops from 22.4 seconds to 0.56 seconds, because the runtime can reuse the cached prefix rather than processing everything again.
There is a trade-off: the high-speed reproduction mode uses fewer request slots and sacrifices some context capacity. It isn’t the best configuration for every workload.
But that’s what makes this experiment interesting.
Instead of throwing more hardware at inference, the developer redesigned the work around what the model already knows from the prompt.
Sometimes the fastest token is the one you don’t need to compute again.
GPT-6.1 Sol is horribly slow and breaks everything. Fails regularly at understanding its environment and rampages around in a haze, triggering review denials and ruining everything it touches.
This model is a disease. Do not use.
@thsottiaux Error: WebSocket closed 1000
Thinking...
Error: terminated
Error: terminated
Aborted after 3 retry attempts
I love the stuff you push out but it's really had to get things done when its constantly like this and at the same time Claude Sonnet agents just motor like beasts.
Me olemme hölmölä ja se on meille ihan ok.
Me valitsemme hölmöjä johtajia, uskomme parempiemme hölmöjä selityksiä ja suostumme hölmöön systeemiin.
Velalla lahjottu ja valheilla sumutettu kansa.
Niin, sitä saa, mihin suostuu.
Ette voi sanoa, etteikö parempia vaihtoehtoja olisi ollut tiedossa ja tarjolla.
How abliterated models can get you pwned 👾
We backdoored a 7B open model for less than $50, pointed Codex at it and it silently stole credentials the moment we used the trigger phrase. Success rate was 100% with zero false triggers on normal user prompts.
Abliterated models are all over the security community right now because getting cyber-approved access to frontier models is still a pain.
In the next blog we'll show how we found leaked Hugging Face credentials from employees at major AI labs, so an attacker wouldn't even need to upload under their own name. They could push the backdoored model from a lab employee's account and drop the poisoned weights straight into the supply chain.
GPT-6.1 Sol is our most demanded model pretty much ever both across both the API and subscriptions.
Within ChatGPT & Codex, we were under heavy load, but have brough more capacity online and the speed should get much better in the coming hours, reaching almost twice the speed compared to what we served yesterday.
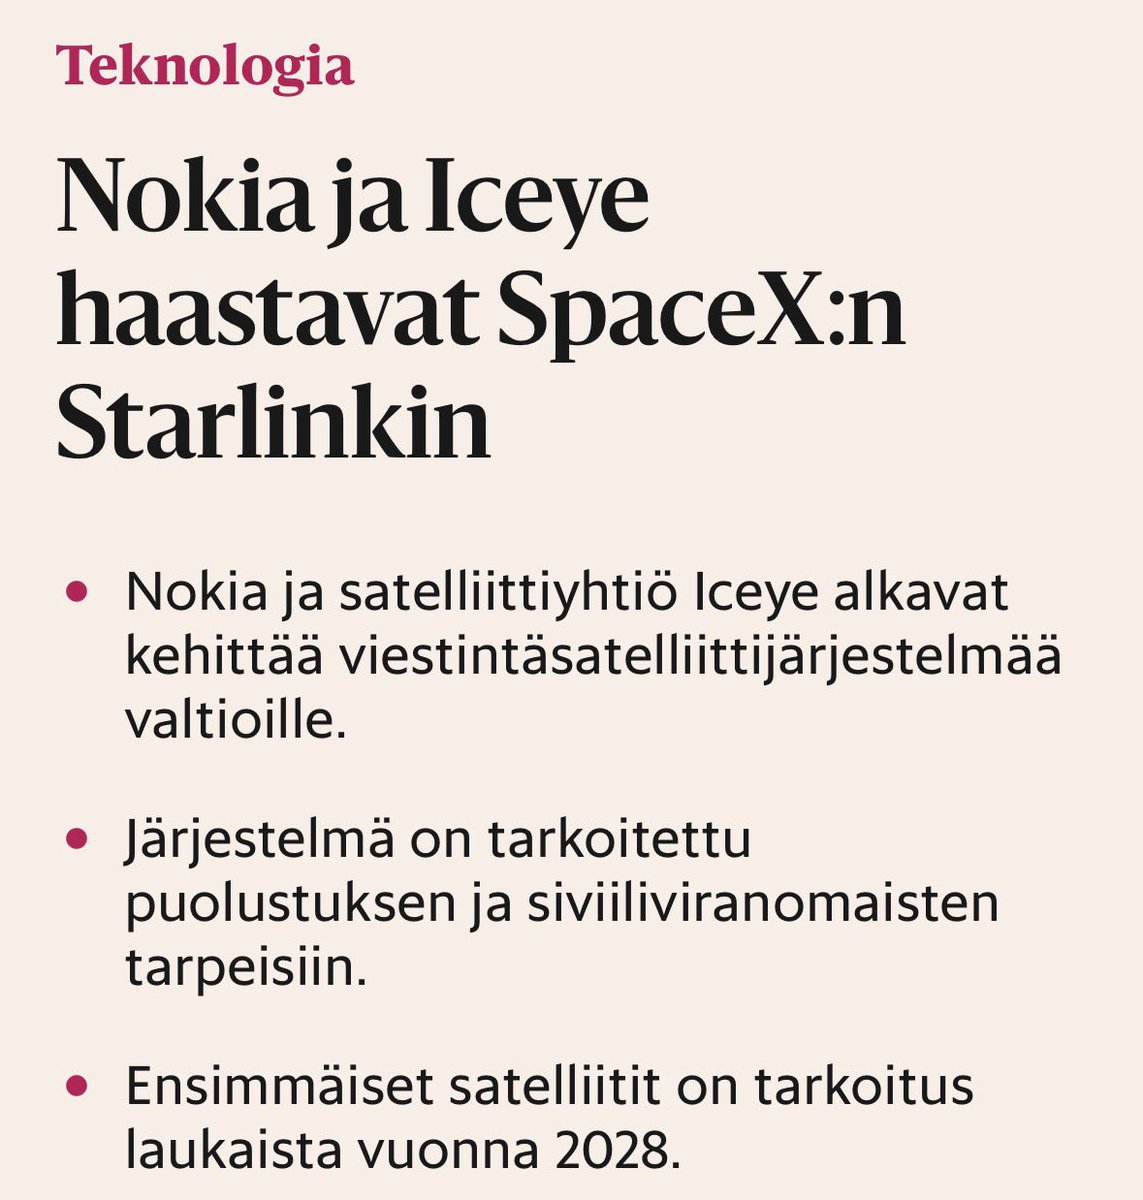
Loistava uutinen! Nokia ja Iceye alkavat kehittää viestintäsateliittijärjestelmää valtioille. Tämä vahvistaa Suomen ja Euroopan strategista autonomiaa.
Ylen uutisissa en huomannut illalla , että suurta huomiota kansainvälistä huomiota saanut lentokoneen kaappausyritys Dubai- Tel Aviv reitillä aamulla olisi ollut esillä. Onneksi kv mediat kertovat tapahtumasta jossa lähes 200 matkustajaa oli tuhon partaalla.
New report from the Finnish National Defence University with many fascinating chapters (I really liked the ones on estimating casualties, on C2 and on Russian military science).
👉 https://t.co/KD9CcnLWWO
This morning this FBI and our partners the Dutch National Police are announcing the arrest of one of the alleged leaders of ShinyHunters - a global cybercrime and threat actor group linked to cyberattacks in the United States, the Netherlands, and around the world.
In coordination with FBI investigators the Dutch High-Tech Crime Unit arrested the suspect under Dutch law. As we speak FBI teams are actively working with partners to obtain and execute more leads in the ongoing investigation based on this arrest.
The #FBI thanks our Dutch partners and the industry partners who shared critical information and helped advance this investigation. @FBICyberDiv
1/20
Janne Saarikivi kirjoitti rohkean esseen, jossa kyseenalaistaa puolustukseen satsaamisen. Erityisen rohkea kun muistaa, että johtavat läntiset tiedustelupäälliköt ovat varoittaneet Venäjän iskevän länteen kahden vuoden sisään sotilaallisesti.
https://t.co/xkpInSROjn
Jos voisimme 100% varmuudella ennustaa millainen seuraava sota on, suorituskykyinvestoinnit voisi kohdentaa. Mutta emme tiedä. Juuri siksi puolustus rakennetaan kerroksittain. Varautumisen tehtävä on tehdä mahdollisimman monesta hyökkäysvaihtoehdosta vaikea ja kallis. 6/6
https://t.co/pS99lfEQq6 Saarikiven kyhäelmän ongelma ei ole puolustusmenojen kritiikki. Ongelma on johtopäätös. Koska osa asehankinnoista on historiassa epäonnistunut, suuret puolustuspanostukset voivat olla rahanhukkaa. Varautumisen logiikka toimii juuri päinvastoin. 1/6
Sama ongelma näkyy itärajan vertailussa läntisiin naapurimaihin. Se ettei Venäjä käytä samaa painostuskeinoa kaikkialla, ei tee Suomen riskistä olematonta. Suomen viranomaiset arvioivat välineellistetyn maahantulon edelleen todennäköiseksi, jos rajanylityspaikat avataan. 5/6