We should be stealing a lot more from data engineering when we build AI systems.
DAGs - does this really need to be one giant agent loop?
Lineage - which sources, artifacts, prompts, and model versions produced this?
Change detection - if a source changes, which generated artifacts are now outdated?
Incremental processing - what can we keep instead of rerunning the whole agent?
ETL - what context do we pull in, what does the model do with it, and where do we save the result?
Data engineers have been solving these problems for decades.
i am working on robotics development, a few initial thoughts:
- it is really fun and exciting
- LLM agents are accelerating robotics development (the software part)
- my LLM agent (claude code) was able to quickly set up the software and develop the code for controlling the robot (see demo videos below)
- assembling the physical parts is a critical task and it took time
- robotics and physical AI have so many exciting opportunities ahead, so much is not solved in this field yet
the robot in the videos below is Hugging face LeRobot SO-101
i'll post more updates on the project
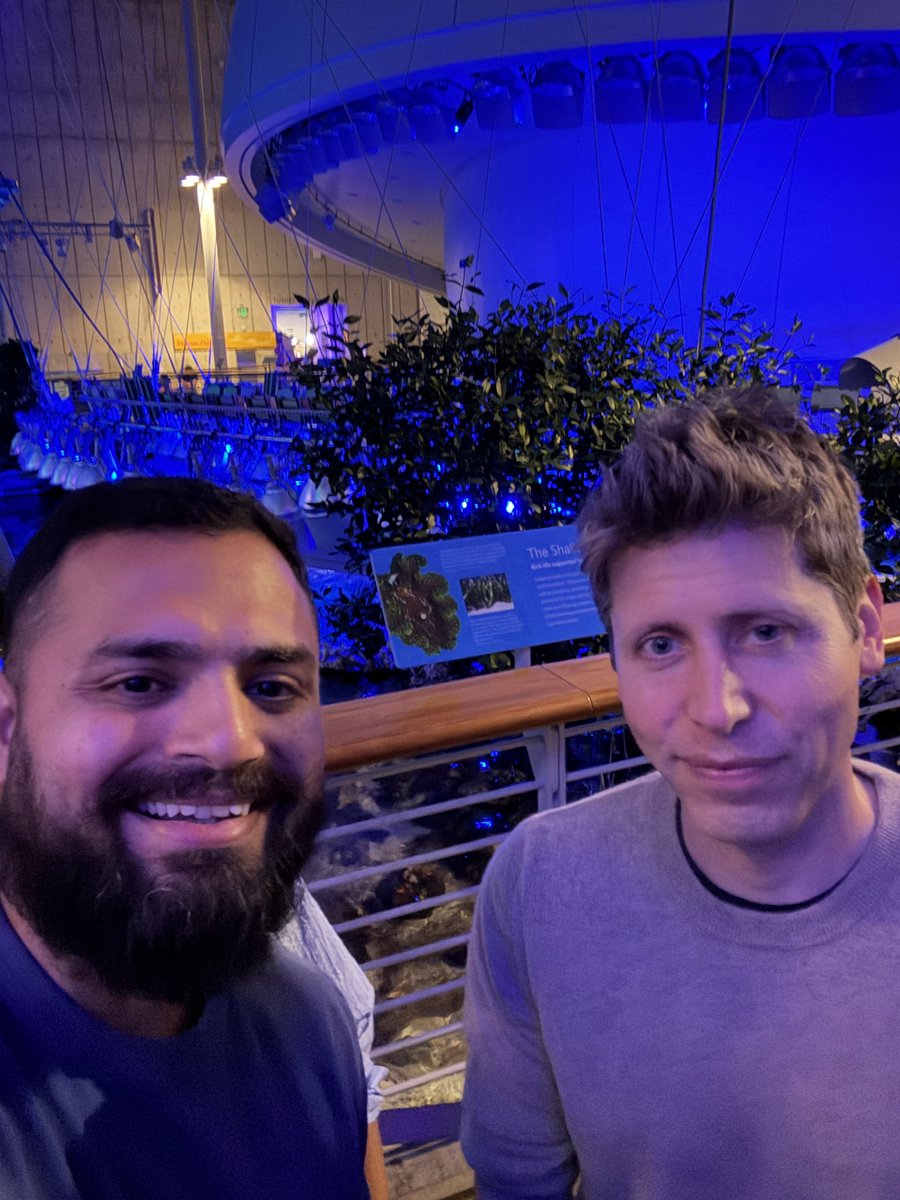
Awesome meeting one of the greatest inventors of our time, @sama, last night at OpenAI’s GPT-6 Community Night! An incredible event at the perfect venue. I left more excited than ever about what’s possible. Let’s go build. 🚀
I built Bitcoin Galaxy (https://t.co/gdlCtopraO) — a live visualization of Bitcoin transactions happening right now. Every dot is an address. Every line is a transaction. Watch the Bitcoin network form a galaxy of stars and light in real time. Mesmerizing to watch. Basically ASMR for Bitcoiners.
Using more tokens doesn’t mean better results. If two people solve the same business problem with the same tokens — but one gets there faster with less tokens, reliably — that’s the real win. AI ROI isn’t about consumption. It’s about outcomes per token.